
To IRT or not to IRT: how to decide STANAG


Description: To IRT or not to IRT: how to decide STANAG 6001 Testing Workshop Kranjska Gora, Slovenia 4-6 September 2018 What are we going to talk about? Ülle Türk 2 How to statistically analyse tests. How it is done in jMetrik. Ülle Türk 3 Ülle Türk
Related Topics
Download Presentation
"To IRT or not to IRT: how to decide STANAG" is the property of its rightful owner. Permission is granted to download and print the materials on this website for personal, non-commercial use only, and to display it on your personal computer provided you do not modify the materials and that you retain all copyright notices contained in the materials. By downloading content from our website, you accept the terms of this agreement.
Presentation Transcript
slide1. To IRT or not to IRT: how to decide STANAG 6001 Testing Workshop – Kranjska Gora, Slovenia
4-6 September 2018<br>
slide2. What are we going to talk about? Ülle Türk 2<br>
slide3. How to statistically analyse tests.
How it is done in jMetrik. Ülle Türk 3<br>
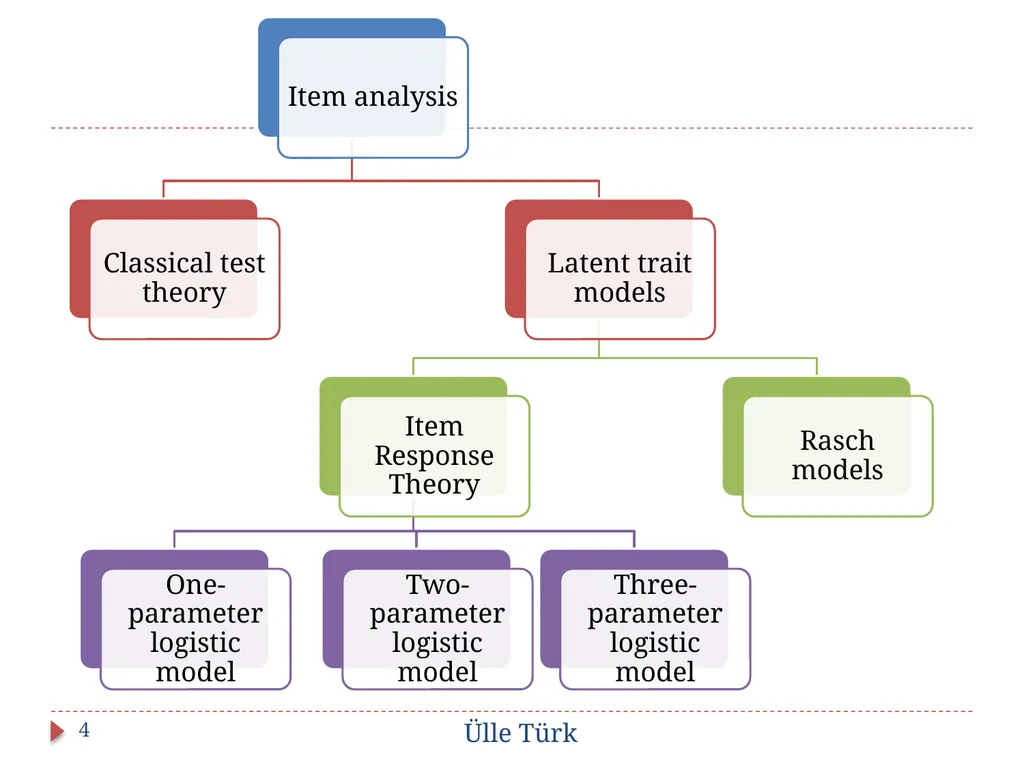
slide4. Ülle Türk 4<br>
slide5. Why ‘latent trait’? Latent trait = unobservable ability or trait
Latent traits or latent variables are constructs that in principle are “hidden” and cannot be measured directly.
They can be measured using observed behaviours or responses (“indicators”).
What is the name of the latent trait measured by a test?
Classical Test Theory (CTT) “True Score” (T)
Item Response Theory (IRT) “Theta” (θ) Ülle Türk 5<br>
slide6. Fundamental difference in approach CTT unit of analysis is the WHOLE TEST (item sum or mean)
Sum = latent trait, so items and persons are inherently tied together (=bad!).
IRT unit of analysis is the ITEM
Model of how item response relates to a separately estimated latent trait.
Provides for separation of item and person properties (=good!). Ülle Türk 6<br>
slide7. Classical Test Theory Ülle Türk 7<br>
slide8. Overview Ülle Türk 8 Originated from the work of Spearman in 1904
Also known as true score theory: observed score (X) = true score (T) + error (E)
Central concern: reliability of measures
Limitations:
Item difficulty and item discrimination depend on particular examinee samples.
The assumption is that standard error of measurement is the same for all subjects.
The focus is on test level information to the exclusion of item level information.<br>
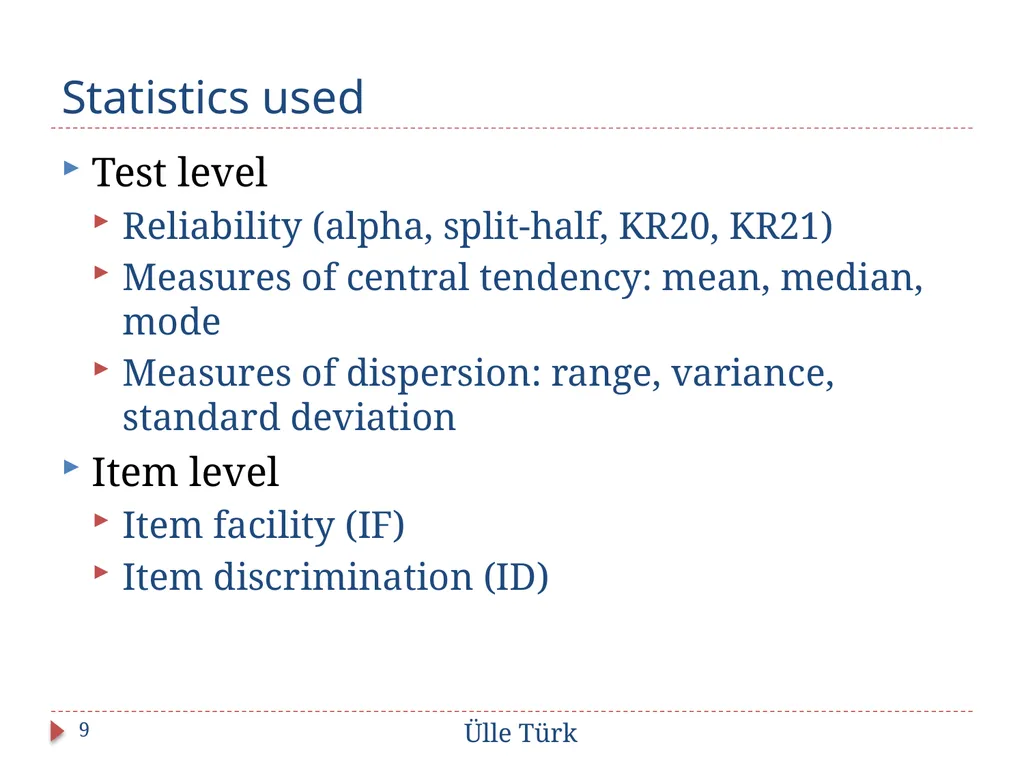
slide9. Statistics used Test level
Reliability (alpha, split-half, KR20, KR21)
Measures of central tendency: mean, median, mode
Measures of dispersion: range, variance, standard deviation
Item level
Item facility (IF)
Item discrimination (ID) Ülle Türk 9<br>
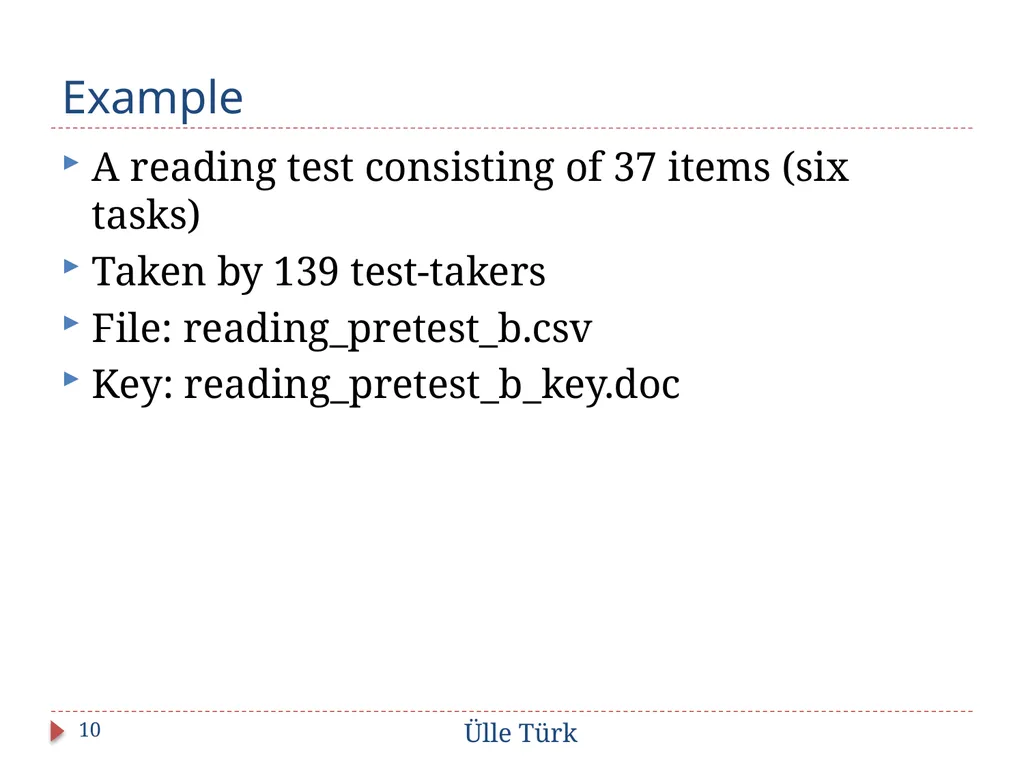
slide10. Example A reading test consisting of 37 items (six tasks)
Taken by 139 test-takers
File: reading_pretest_b.csv
Key: reading_pretest_b_key.doc Ülle Türk 10<br>
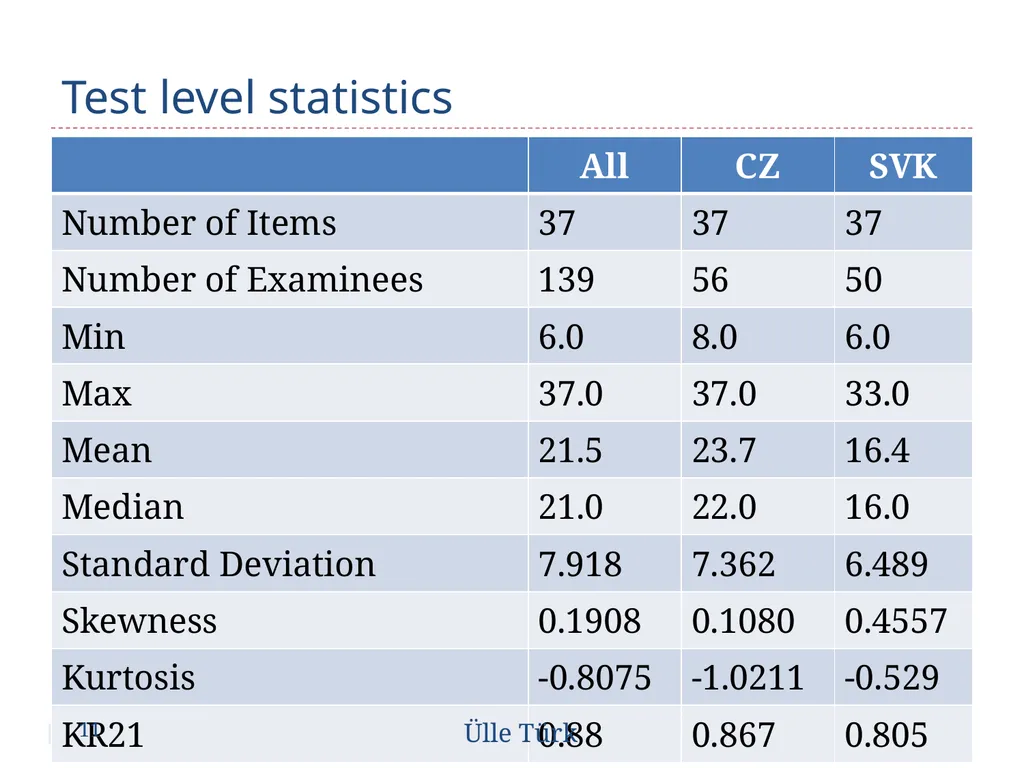
slide11. Test level statistics Ülle Türk 11<br>
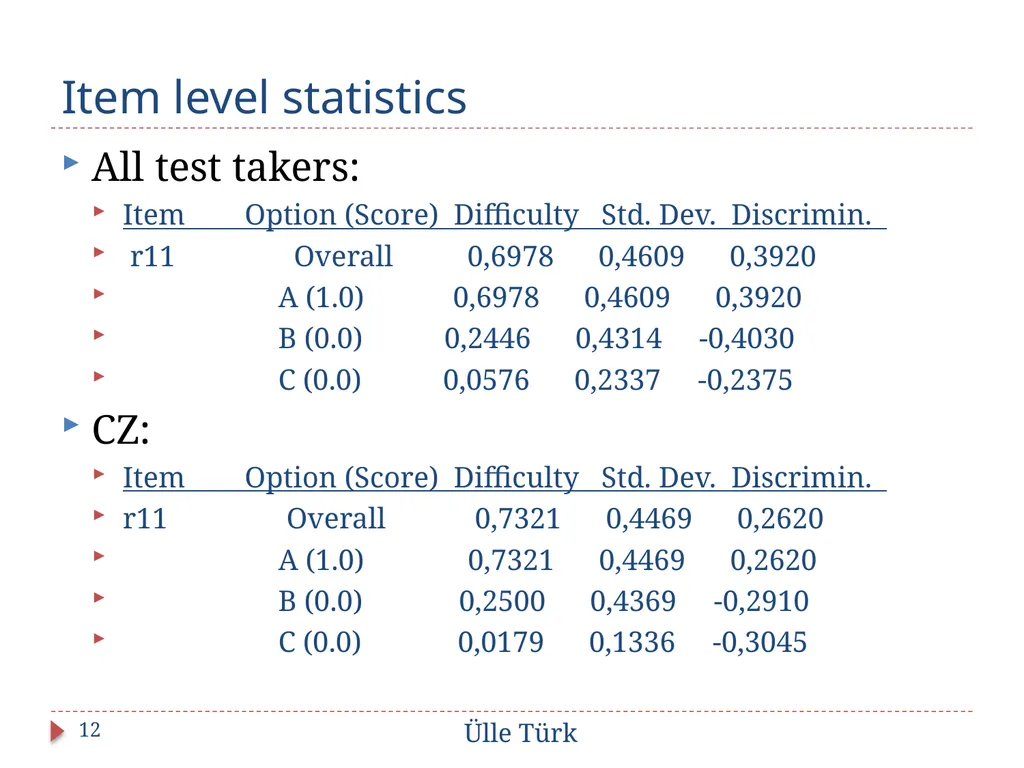
slide12. Item level statistics All test takers:
Item Option (Score) Difficulty Std. Dev. Discrimin.
r11 Overall 0,6978 0,4609 0,3920
A (1.0) 0,6978 0,4609 0,3920
B (0.0) 0,2446 0,4314 -0,4030
C (0.0) 0,0576 0,2337 -0,2375
CZ:
Item Option (Score) Difficulty Std. Dev. Discrimin.
r11 Overall 0,7321 0,4469 0,2620
A (1.0) 0,7321 0,4469 0,2620
B (0.0) 0,2500 0,4369 -0,2910
C (0.0) 0,0179 0,1336 -0,3045 Ülle Türk 12<br>
slide13. Item Response Theory Ülle Türk 13<br>
slide14. Overview Ülle Türk 14 Originated with the work of Rasch in the 1960s and Lord in the 1950s
IRT methods model the probability of an individual's response to an item.
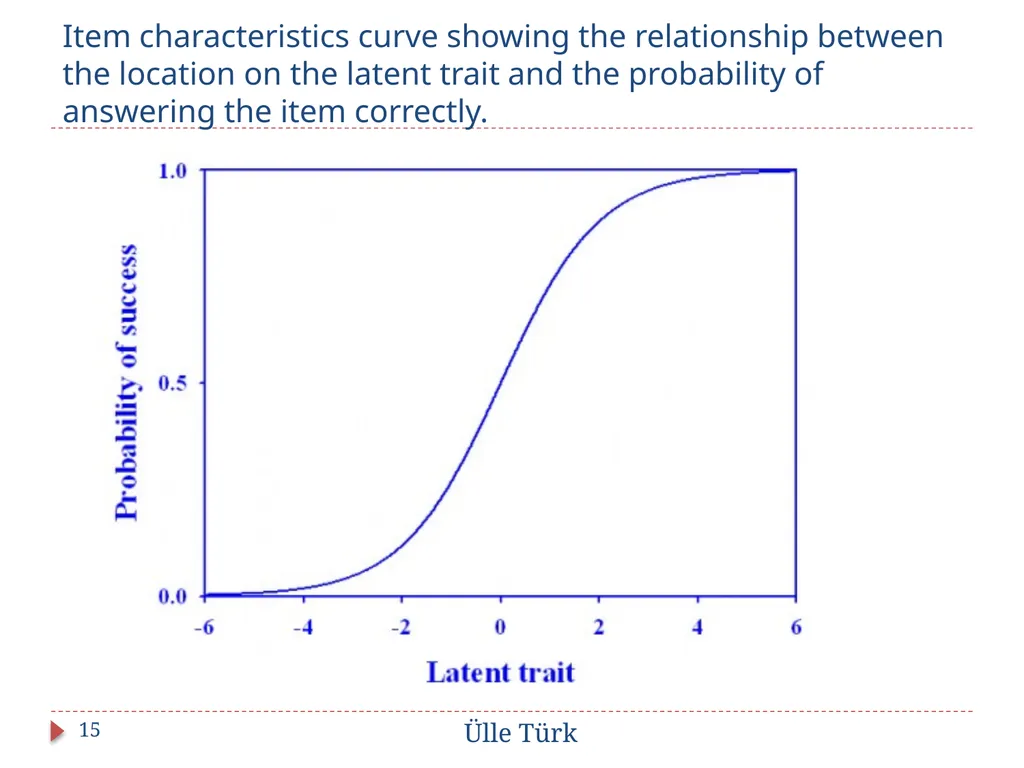
The relationship between the probability of success to an item and the latent trait (e.g., the ability) is described by a function called item characteristic curve (ICC) that takes an S-shape.<br>
slide15. Item characteristics curve showing the relationship between the location on the latent trait and the probability of answering the item correctly. Ülle Türk 15<br>
slide16. A family of models Latent ability = theta ()
Parameters:
b – item location (i.e. difficulty)
a – discrimination
c – guessing
The Rasch model: the probability of a correct response is modelled as a logistic function of the difference between the person and item parameter. Ülle Türk 16<br>
slide17. Rasch model: 2 assumptions and a ‘problem’ The data must fit the model the following two assumptions must be met:
The test measures a single latent trait (i.e. it is unidimensional).
Items are locally independent.
A problem – scale indeterminancy
The latent scale is completely arbitrary.
Indeterminancy is resolved through either person centering or item centering.
jMetric uses item centering. Ülle Türk 17<br>
slide18. Rasch model: benefits Parameter invariance
Item parameters do not depend on the distribution of examinees.
Person parameters do not depend on the distribution of items.
Specific objectivity
Comparisons between individuals are independent of which particular items within the class considered have been used.
It is possible to compare items measuring the same thing independently of which particular individuals within a class considered answered them. Ülle Türk 18<br>
slide19. Do items and persons fit the model? Infit and outfit statistics
Analysis begins with the difference between the observed and expected values of an item response, known as a residual.
Residuals are then standardised by dividing them by their item information.
Item outfit: standardised residuals are squared and averaged over examinees.
Exminee outfit: standardised residuals are squared and averaged over items
Infit: a weighted average of squared standardised residuals, where the weights are the item information Ülle Türk 19<br>
slide20. Infit and outfit – how to interpret? Outfit focusses on an extreme mismatch between the item and person (‘outliers’).
Infit is information weighted: emphasises residuals from well-matched persons and items.
Values are always positive and those close to 1 indicate good model-data fit.
For high-stakes tests, values between 0.8 and 1.2 are recommended.
Otherwise values between 0.5 and 1.5 are still OK.
Standardised infit and outfit can be positive and negative and have an expected value of 0.
Values greater than three in absolute measure indicate a problem. Ülle Türk 20<br>
slide21. Outfit and infit in jMetrik Outfit statistics
UMS = unweighted mean square fit statistic
Std UMS = standardised unweighted mean square fit statistic
Infit statistics
WMS = weighted mean square fit statistic
Std WMS = standardised weighted mean square fit statistic Ülle Türk 21<br>
slide22. Scale quality statistics Prson and item reliability
Person reliability represents the quality of person ordering on the latent trait.
Similar to the reliability coefficient in the classical test theory.
Values larger than 0.8 are desirable.
Person and item separation
Person separation represents the extent to which a measure can reproduce and consistently rank scores.
Separation values larger than 2 are desirable. Ülle Türk 22<br>
slide23. Using jMetrik to do Rasch analyses Ülle Türk 23<br>
slide24. A quick introduction to jMetrik jMetrikTM is free and open source psychometric software.
Psychometric methods include
classical item analysis,
reliability estimation,
test scaling,
differential item functioning,
nonparametric item response theory,
Rasch measurement models,
item response models (e.g. 3PL, 4PL, GPCM), and
item response theory linking and equating. Ülle Türk 24<br>
slide25. Getting to know jMetrik Can be downloaded from the Psychomeasurement Systems website.
A Quick Start Guide and a little more detailed User Guide are available on the website.
There is also a short video Getting started with jMetrik.
We are going to use the file reading_pretest_b.csv (a semi-colon delimited file). Ülle Türk 25<br>
slide26. Getting started with jMetrik Start jMetrik and click Manage > New Database and type a name for the database in the dialog box that appears. Click the Create button to have jMetrik create the database.
Open the database you have just created (Manage > Open Database).
Import data: Click Manage > Import Data and type a name for the table in the Table Name text field. Click the Browse Button to select a delimited text file to import. Select the appropriate delimiter (comma, tab, colon, or semicolon) in the file dialog. Click the Import button to import your data.
Score the items (i.e. tell the program what the right answer to each question is) using Basic Item Scoring. The first row is for the key; the second row is for the numbr of options. The file reading_pretest_b_key.doc has the number of options listeed after each correct answer. Ülle Türk 26a<br>
slide27. Running the Rasch analysis in jMetrik NB! You do not need to score examinees’ answers (Test Scaling) before running the Rasch analyses as the program calculates the total score for each eaminee.
Click Analyze Rasch Models (JMLE).
Rasch Models dialog box appears.
Move the items you want to include in the analysis to the box on the right.
The lower portion of the box includes three tabs:
Global
Item
Person Ülle Türk 27<br>
slide28. Running the Rasch analysis in jMetrik (2) Global tab
Leave the numbers in the Global Estimation panel the way they are.
In the Options panel, decide how to treat missing data.
Ignore the Linear Transformation panel at this point.
Item tab
Select the Save item estimates checkbox to save item parameter estimates to a new database table.
Person tab
Choosing the Save person estimates checkbox will add 5 new variables to the data table: the sum score (sum), valid sum score (vsum), latent trait estimate (theta), standard error of the latter (stderr), whether the examinee had an extreme score (extreme). Ülle Türk 28<br>
slide29. Running the Rasch analysis in jMetrik (3) Person tab (continued)
When you select the Save person fit statistics checkbox, jMetrik will add four new variables to the data table: infit (wms), standardised infit (stdwms), outfit (ums) and standardised outfit (stdums).
Selecting the Save residuals checkbox will produce a new table that contains residual values. This table can be used to check th assumption of local independence using Yen’s Q3 statistic.
Now you can run the analyses by clicking Run. Ülle Türk 29<br>
slide30. Creating an item map Item maps summarise the distribution of person ability and distribution of item difficulty for a whole test.
They are useful for determining whether items align with the examinee population and identifying parts of th scale that are in need of additional items.
To create an item map, select the table that contains the person ability estimates.
Click Graph Item Map to start the Item Map dialog.
In the Variable Selection panel at the top of the dialog, select theta (person ability).
In the Item Parameter Table panel, click the Select button to choose the item parameter table.
Click the Run button to create the item map. Ülle Türk 30<br>
slide31. CTT and IRT compared Ülle Türk 31<br>
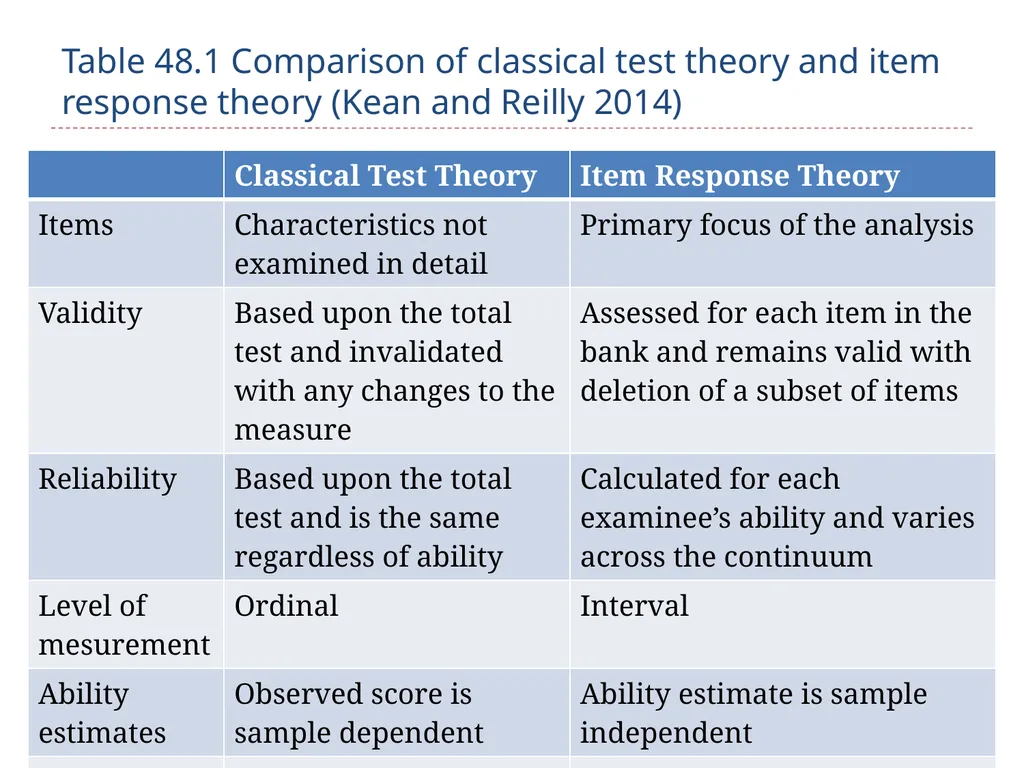
slide32. Table 48.1 Comparison of classical test theory and item response theory (Kean and Reilly 2014) Ülle Türk 32<br>
slide33. Main advantages of IRT over CTT IRT allows item banking, which means that candidates can all be given a completely different set of items, but still provide an equally accurate estimate of ability.
IRT allows for adaptive testing, in which a test gets more, or less difficult depending on the performance of the candidate, tailoring the test to their ability.
If you want to create a proper item bank or start using adaptive testing, learn how to use IRT. Ülle Türk 33<br>
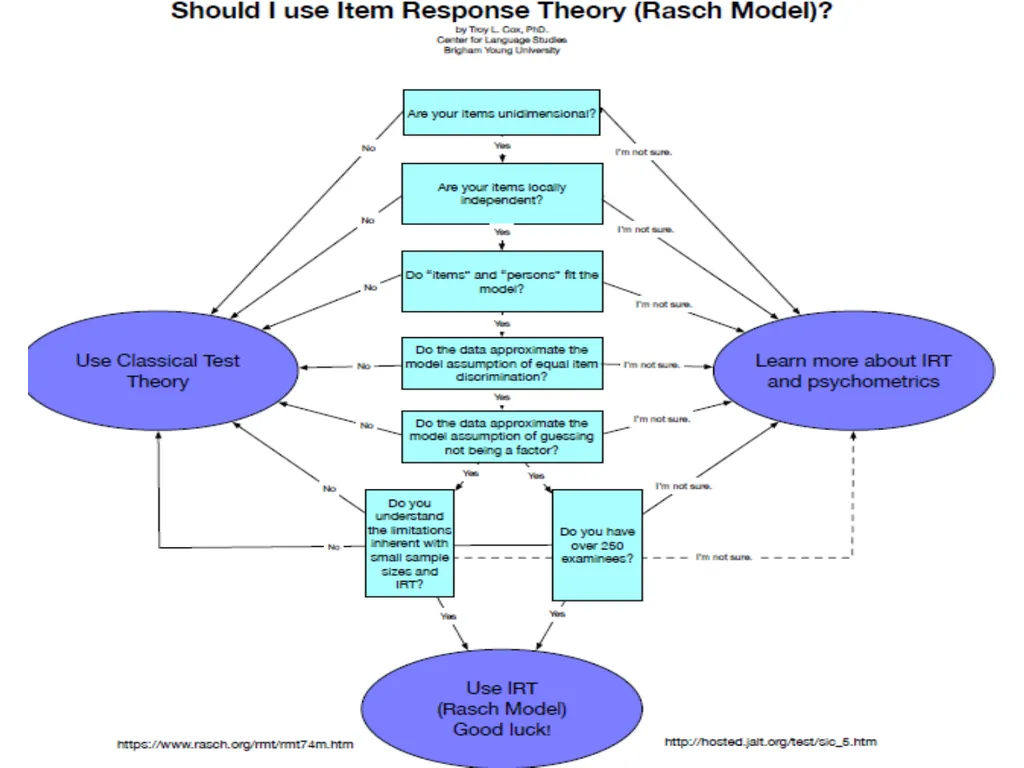
slide34. Are you ready for IRT? Troy L. Cox Ülle Türk 34<br>
slide35. Ülle Türk 35<br>
slide36. Sources Ülle Türk 36<br>
slide37. References Ülle Türk 37 Kean, Jacob and Jamie Reilly. 2014. Classical Test Theory. In: F. M. Hammond, J. F. Malec, T. Nick, & R. Buschbacher (Eds.) Handbook for Clinical Research: Design, Statistics and Implementation. Chapter 48, pp 192-194. New York, NY: Demos Medical Publishing.
Kean, Jacob and Jamie Reilly. 2014. Item Rsponse Theory. In: F. M. Hammond, J. F. Malec, T. Nick, & R. Buschbacher (Eds.) Handbook for Clinical Research: Design, Statistics and Implementation. Chapter 49, pp 195-198. New York, NY: Demos Medical Publishing.<br>
slide38. Some useful sources Janssen, Gerriet, Valerie Meier & Jonathan Trace. 2014. Classical Test Theory and Item Response Theory: Two understandings of one high-stakes performance exam. Colombian Applied Linguistics Journal, 16(2), 167-184.
Thompson, Nathan. 2016. What is item response theory? From Assessment Systems.
Item Response Theory from Columbia University Mailman School of Public Health. Ülle Türk 38<br>
4-6 September 2018<br>
slide2. What are we going to talk about? Ülle Türk 2<br>
slide3. How to statistically analyse tests.
How it is done in jMetrik. Ülle Türk 3<br>
slide4. Ülle Türk 4<br>
slide5. Why ‘latent trait’? Latent trait = unobservable ability or trait
Latent traits or latent variables are constructs that in principle are “hidden” and cannot be measured directly.
They can be measured using observed behaviours or responses (“indicators”).
What is the name of the latent trait measured by a test?
Classical Test Theory (CTT) “True Score” (T)
Item Response Theory (IRT) “Theta” (θ) Ülle Türk 5<br>
slide6. Fundamental difference in approach CTT unit of analysis is the WHOLE TEST (item sum or mean)
Sum = latent trait, so items and persons are inherently tied together (=bad!).
IRT unit of analysis is the ITEM
Model of how item response relates to a separately estimated latent trait.
Provides for separation of item and person properties (=good!). Ülle Türk 6<br>
slide7. Classical Test Theory Ülle Türk 7<br>
slide8. Overview Ülle Türk 8 Originated from the work of Spearman in 1904
Also known as true score theory: observed score (X) = true score (T) + error (E)
Central concern: reliability of measures
Limitations:
Item difficulty and item discrimination depend on particular examinee samples.
The assumption is that standard error of measurement is the same for all subjects.
The focus is on test level information to the exclusion of item level information.<br>
slide9. Statistics used Test level
Reliability (alpha, split-half, KR20, KR21)
Measures of central tendency: mean, median, mode
Measures of dispersion: range, variance, standard deviation
Item level
Item facility (IF)
Item discrimination (ID) Ülle Türk 9<br>
slide10. Example A reading test consisting of 37 items (six tasks)
Taken by 139 test-takers
File: reading_pretest_b.csv
Key: reading_pretest_b_key.doc Ülle Türk 10<br>
slide11. Test level statistics Ülle Türk 11<br>
slide12. Item level statistics All test takers:
Item Option (Score) Difficulty Std. Dev. Discrimin.
r11 Overall 0,6978 0,4609 0,3920
A (1.0) 0,6978 0,4609 0,3920
B (0.0) 0,2446 0,4314 -0,4030
C (0.0) 0,0576 0,2337 -0,2375
CZ:
Item Option (Score) Difficulty Std. Dev. Discrimin.
r11 Overall 0,7321 0,4469 0,2620
A (1.0) 0,7321 0,4469 0,2620
B (0.0) 0,2500 0,4369 -0,2910
C (0.0) 0,0179 0,1336 -0,3045 Ülle Türk 12<br>
slide13. Item Response Theory Ülle Türk 13<br>
slide14. Overview Ülle Türk 14 Originated with the work of Rasch in the 1960s and Lord in the 1950s
IRT methods model the probability of an individual's response to an item.
The relationship between the probability of success to an item and the latent trait (e.g., the ability) is described by a function called item characteristic curve (ICC) that takes an S-shape.<br>
slide15. Item characteristics curve showing the relationship between the location on the latent trait and the probability of answering the item correctly. Ülle Türk 15<br>
slide16. A family of models Latent ability = theta ()
Parameters:
b – item location (i.e. difficulty)
a – discrimination
c – guessing
The Rasch model: the probability of a correct response is modelled as a logistic function of the difference between the person and item parameter. Ülle Türk 16<br>
slide17. Rasch model: 2 assumptions and a ‘problem’ The data must fit the model the following two assumptions must be met:
The test measures a single latent trait (i.e. it is unidimensional).
Items are locally independent.
A problem – scale indeterminancy
The latent scale is completely arbitrary.
Indeterminancy is resolved through either person centering or item centering.
jMetric uses item centering. Ülle Türk 17<br>
slide18. Rasch model: benefits Parameter invariance
Item parameters do not depend on the distribution of examinees.
Person parameters do not depend on the distribution of items.
Specific objectivity
Comparisons between individuals are independent of which particular items within the class considered have been used.
It is possible to compare items measuring the same thing independently of which particular individuals within a class considered answered them. Ülle Türk 18<br>
slide19. Do items and persons fit the model? Infit and outfit statistics
Analysis begins with the difference between the observed and expected values of an item response, known as a residual.
Residuals are then standardised by dividing them by their item information.
Item outfit: standardised residuals are squared and averaged over examinees.
Exminee outfit: standardised residuals are squared and averaged over items
Infit: a weighted average of squared standardised residuals, where the weights are the item information Ülle Türk 19<br>
slide20. Infit and outfit – how to interpret? Outfit focusses on an extreme mismatch between the item and person (‘outliers’).
Infit is information weighted: emphasises residuals from well-matched persons and items.
Values are always positive and those close to 1 indicate good model-data fit.
For high-stakes tests, values between 0.8 and 1.2 are recommended.
Otherwise values between 0.5 and 1.5 are still OK.
Standardised infit and outfit can be positive and negative and have an expected value of 0.
Values greater than three in absolute measure indicate a problem. Ülle Türk 20<br>
slide21. Outfit and infit in jMetrik Outfit statistics
UMS = unweighted mean square fit statistic
Std UMS = standardised unweighted mean square fit statistic
Infit statistics
WMS = weighted mean square fit statistic
Std WMS = standardised weighted mean square fit statistic Ülle Türk 21<br>
slide22. Scale quality statistics Prson and item reliability
Person reliability represents the quality of person ordering on the latent trait.
Similar to the reliability coefficient in the classical test theory.
Values larger than 0.8 are desirable.
Person and item separation
Person separation represents the extent to which a measure can reproduce and consistently rank scores.
Separation values larger than 2 are desirable. Ülle Türk 22<br>
slide23. Using jMetrik to do Rasch analyses Ülle Türk 23<br>
slide24. A quick introduction to jMetrik jMetrikTM is free and open source psychometric software.
Psychometric methods include
classical item analysis,
reliability estimation,
test scaling,
differential item functioning,
nonparametric item response theory,
Rasch measurement models,
item response models (e.g. 3PL, 4PL, GPCM), and
item response theory linking and equating. Ülle Türk 24<br>
slide25. Getting to know jMetrik Can be downloaded from the Psychomeasurement Systems website.
A Quick Start Guide and a little more detailed User Guide are available on the website.
There is also a short video Getting started with jMetrik.
We are going to use the file reading_pretest_b.csv (a semi-colon delimited file). Ülle Türk 25<br>
slide26. Getting started with jMetrik Start jMetrik and click Manage > New Database and type a name for the database in the dialog box that appears. Click the Create button to have jMetrik create the database.
Open the database you have just created (Manage > Open Database).
Import data: Click Manage > Import Data and type a name for the table in the Table Name text field. Click the Browse Button to select a delimited text file to import. Select the appropriate delimiter (comma, tab, colon, or semicolon) in the file dialog. Click the Import button to import your data.
Score the items (i.e. tell the program what the right answer to each question is) using Basic Item Scoring. The first row is for the key; the second row is for the numbr of options. The file reading_pretest_b_key.doc has the number of options listeed after each correct answer. Ülle Türk 26a<br>
slide27. Running the Rasch analysis in jMetrik NB! You do not need to score examinees’ answers (Test Scaling) before running the Rasch analyses as the program calculates the total score for each eaminee.
Click Analyze Rasch Models (JMLE).
Rasch Models dialog box appears.
Move the items you want to include in the analysis to the box on the right.
The lower portion of the box includes three tabs:
Global
Item
Person Ülle Türk 27<br>
slide28. Running the Rasch analysis in jMetrik (2) Global tab
Leave the numbers in the Global Estimation panel the way they are.
In the Options panel, decide how to treat missing data.
Ignore the Linear Transformation panel at this point.
Item tab
Select the Save item estimates checkbox to save item parameter estimates to a new database table.
Person tab
Choosing the Save person estimates checkbox will add 5 new variables to the data table: the sum score (sum), valid sum score (vsum), latent trait estimate (theta), standard error of the latter (stderr), whether the examinee had an extreme score (extreme). Ülle Türk 28<br>
slide29. Running the Rasch analysis in jMetrik (3) Person tab (continued)
When you select the Save person fit statistics checkbox, jMetrik will add four new variables to the data table: infit (wms), standardised infit (stdwms), outfit (ums) and standardised outfit (stdums).
Selecting the Save residuals checkbox will produce a new table that contains residual values. This table can be used to check th assumption of local independence using Yen’s Q3 statistic.
Now you can run the analyses by clicking Run. Ülle Türk 29<br>
slide30. Creating an item map Item maps summarise the distribution of person ability and distribution of item difficulty for a whole test.
They are useful for determining whether items align with the examinee population and identifying parts of th scale that are in need of additional items.
To create an item map, select the table that contains the person ability estimates.
Click Graph Item Map to start the Item Map dialog.
In the Variable Selection panel at the top of the dialog, select theta (person ability).
In the Item Parameter Table panel, click the Select button to choose the item parameter table.
Click the Run button to create the item map. Ülle Türk 30<br>
slide31. CTT and IRT compared Ülle Türk 31<br>
slide32. Table 48.1 Comparison of classical test theory and item response theory (Kean and Reilly 2014) Ülle Türk 32<br>
slide33. Main advantages of IRT over CTT IRT allows item banking, which means that candidates can all be given a completely different set of items, but still provide an equally accurate estimate of ability.
IRT allows for adaptive testing, in which a test gets more, or less difficult depending on the performance of the candidate, tailoring the test to their ability.
If you want to create a proper item bank or start using adaptive testing, learn how to use IRT. Ülle Türk 33<br>
slide34. Are you ready for IRT? Troy L. Cox Ülle Türk 34<br>
slide35. Ülle Türk 35<br>
slide36. Sources Ülle Türk 36<br>
slide37. References Ülle Türk 37 Kean, Jacob and Jamie Reilly. 2014. Classical Test Theory. In: F. M. Hammond, J. F. Malec, T. Nick, & R. Buschbacher (Eds.) Handbook for Clinical Research: Design, Statistics and Implementation. Chapter 48, pp 192-194. New York, NY: Demos Medical Publishing.
Kean, Jacob and Jamie Reilly. 2014. Item Rsponse Theory. In: F. M. Hammond, J. F. Malec, T. Nick, & R. Buschbacher (Eds.) Handbook for Clinical Research: Design, Statistics and Implementation. Chapter 49, pp 195-198. New York, NY: Demos Medical Publishing.<br>
slide38. Some useful sources Janssen, Gerriet, Valerie Meier & Jonathan Trace. 2014. Classical Test Theory and Item Response Theory: Two understandings of one high-stakes performance exam. Colombian Applied Linguistics Journal, 16(2), 167-184.
Thompson, Nathan. 2016. What is item response theory? From Assessment Systems.
Item Response Theory from Columbia University Mailman School of Public Health. Ülle Türk 38<br>