Search Results for 'model speech'
model speech published presentations and documents on DocSlides.
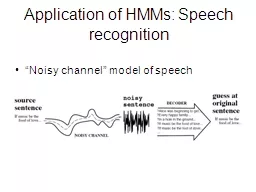
Application of HMMs: Speech recognition
by faustina-dinatale
“Noisy channel” model of speech. Speech featu...
1 Automatic Speech Recognition: An Overview
by QueenBee
Julia Hirschberg. CS 4706. (Thanks . to Roberto . ...
SPEECH RECOGNITION FOR MOBILE SYSTEMS
by calandra-battersby
BY:. PRATIBHA CHANNAMSETTY. SHRUTHI SAMBASIVAN. I...
7.0 Speech Signals and Front-end Processing
by cheryl-pisano
References. : 1. 3.3, 3.4 of Becchetti. 3. 9....
Speech Recognition and HMM Learning
by faustina-dinatale
1. Speech Recognition and HMM Learning. Overview ...
Linguistic knowledge for Speech recognition
by aaron
By : Ahmed Aly. 06/05/2013. Project description. ...
7.0 Speech Signals and Front-end Processing
by giovanna-bartolotta
References. : 1. 3.3, 3.4 of Becchetti. 3. 9....
Unlocking Audio/Video Content with Speech Recognition
by danika-pritchard
Behrooz Chitsaz. Director, IP Strategy. Microsoft...
The audibility of direct sound as a key to measuring the clarity of speech and music
by marina-yarberry
David Griesinger. David Griesinger Acoustics, Ca...
AIRUS (Automatic Information Retrieval Using Speech)
by giovanna-bartolotta
Winter School `09-> Speech Track -> Group ...
Deep Learning: Speech & Information Processing
by elyana
New-Generation Models & Methodology for Advanc...

Structured sparse acoustic modeling for speech separation
by maisie
Afsaneh . Asaei. Joint work with: . Mohammad . Gol...
FLST: Prosodic Models for Speech Techno
by tatiana-dople
Bernd Möbius. moebius@coli.uni-saarland.de. http...
Signal Analysis Using Autoregressive Models of Amplitude Mo
by debby-jeon
Sriram . Ganapathy. Advisor - . Hynek. . Hermans...
Deep Learning for Audio Yuchen Fan, Matt Potok, Christopher Shroba
by faustina-dinatale
Motivation. Text-to-Speech. Accessibility feature...
Announcements Office hours now Mon 3:30-4:30 and Thu 2:30-3:30
by pamella-moone
Today’s learning goals. At the end of today, yo...

Testing the Effort Models tightrope hypothesis insimultaneous interpr
by samantha
*Daniel GileUniversit

Natural Language Understanding
by stefany-barnette
Ling575. Spoken Dialog Systems. April 17, 2013. N...
The Application of Hidden Markov Models
by stefany-barnette
in Speech Recognition. Author. :. Mark . Gale...
1 Intonation and Computation:
by yoshiko-marsland
Emotion. Julia . Hirschberg. LSA 2017. julia@cs....