
D3S: Debug Deployed Distributed Systems Xuezheng
TF
Published · 29 slides · 0 views
1 / 1

Description
D3S: Debug Deployed Distributed Systems Xuezheng Liu, Zhenyu Guo, Xi Wang, Feibo Chen, Xiaochen Lian, Jian Tang, Ming Wu, M. Frans Kaashoek, Zheng Zhang Microsoft Research Asia, Tsinghua University, Fudan University, Shanghai Jiaotong
Related Topics
Share
Embed code
Download this presentation From Below
"D3S: Debug Deployed Distributed Systems Xuezheng" is the property of its rightful owner. Permission is granted to download and print the materials on this website for personal, non-commercial use only, and to display it on your personal computer provided you do not modify the materials and that you retain all copyright notices contained in the materials. By downloading content from our website, you accept the terms of this agreement.
Presentation Transcript
01
D3S: Debug Deployed Distributed Systems Xuezheng Liu, Zhenyu Guo, Xi Wang, Feibo Chen,
Xiaochen Lian, Jian Tang, Ming Wu, M. Frans Kaashoek, Zheng Zhang
Microsoft Research Asia, Tsinghua University, Fudan University, Shanghai Jiaotong University, MIT CSAIL<br>
Microsoft Research Asia, Tsinghua University, Fudan University, Shanghai Jiaotong University, MIT CSAIL<br>
02
Debugging distributed systems is difficult Bugs are difficult to reproduce
Many machines executing concurrently
Machines may fail
Network may fail<br>
Many machines executing concurrently
Machines may fail
Network may fail<br>
03
Example: Distributed lock Distributed reader-writer locks
Lock mode: exclusive, shared
Invariant: only one client can hold a lock in the exclusive mode
Debugging is difficult because the protocol is complex
For performance, clients cache locks
For failure tolerance, locks have a lease<br>
Lock mode: exclusive, shared
Invariant: only one client can hold a lock in the exclusive mode
Debugging is difficult because the protocol is complex
For performance, clients cache locks
For failure tolerance, locks have a lease<br>
04
How do people debug? Simulation
Model-checking
Runtime checking<br>
Model-checking
Runtime checking<br>
05
State-of-the-art of runtime checking Step 1: add logs
void ClientNode::OnLockAcquired(…) {
…
print_log( m_NodeID, lock, mode);
} Step 2: Collect logs, align them into a globally consistent sequence
Keep partial order Step 3: Write checking scripts
Scan the logs to retrieve lock states
Check the consistency of locks<br>
void ClientNode::OnLockAcquired(…) {
…
print_log( m_NodeID, lock, mode);
} Step 2: Collect logs, align them into a globally consistent sequence
Keep partial order Step 3: Write checking scripts
Scan the logs to retrieve lock states
Check the consistency of locks<br>
06
Problems for large/deployed systems Too much manual effort
Difficult to anticipate what needs to log
Too much information: slow systems down
Too little information: miss a problem
Checking for large system is challenging
A central checker cannot keep up
Snapshots must be consistent
Our focus: make runtime checking easier and feasible for deployed/large-scale system<br>
07
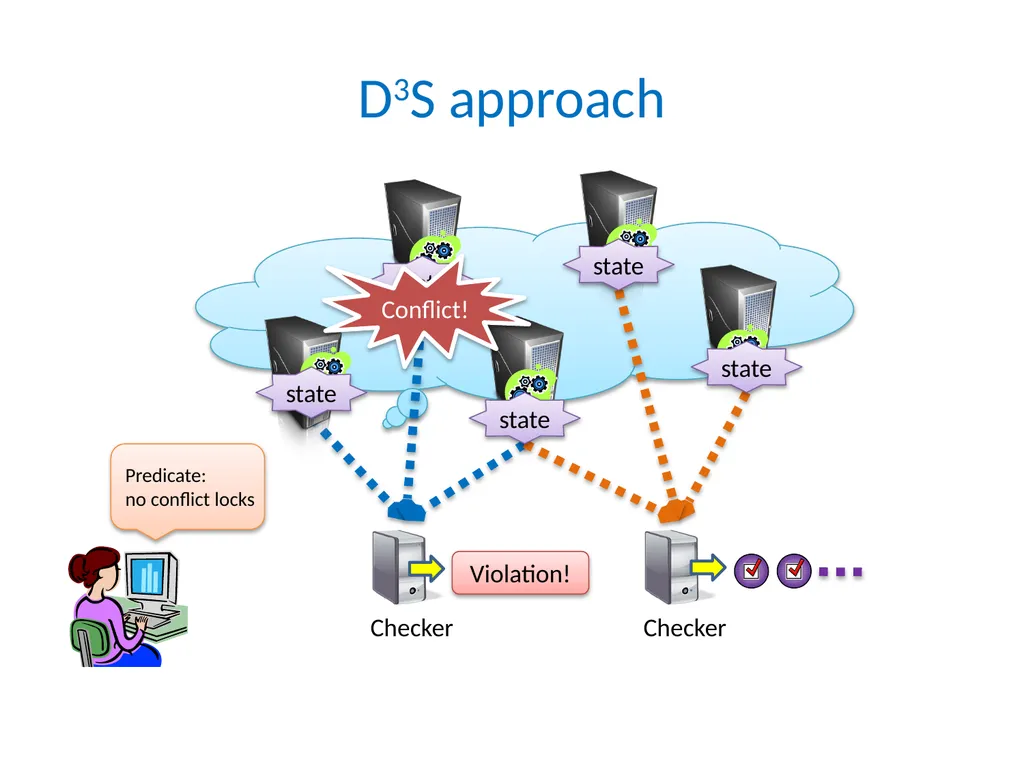
D3S approach Predicate:
no conflict locks Violation! state state state state state Conflict!<br>
no conflict locks Violation! state state state state state Conflict!<br>
08
Our contributions/outline A simple language for writing distributed predicates
Programmers can change what is being checked on-the-fly
Failure tolerant consistent snapshot for predicate checking
Evaluation with five real-world applications<br>
Programmers can change what is being checked on-the-fly
Failure tolerant consistent snapshot for predicate checking
Evaluation with five real-world applications<br>
09
Design goals Simplicity: a sequential style for writing predicates
Parallelism: run in parallel on multiple checkers
Correctness: check consistent states in spite of failures
Solution
MapReduce model
Failure-tolerant consistent snapshot<br>
Parallelism: run in parallel on multiple checkers
Correctness: check consistent states in spite of failures
Solution
MapReduce model
Failure-tolerant consistent snapshot<br>
10
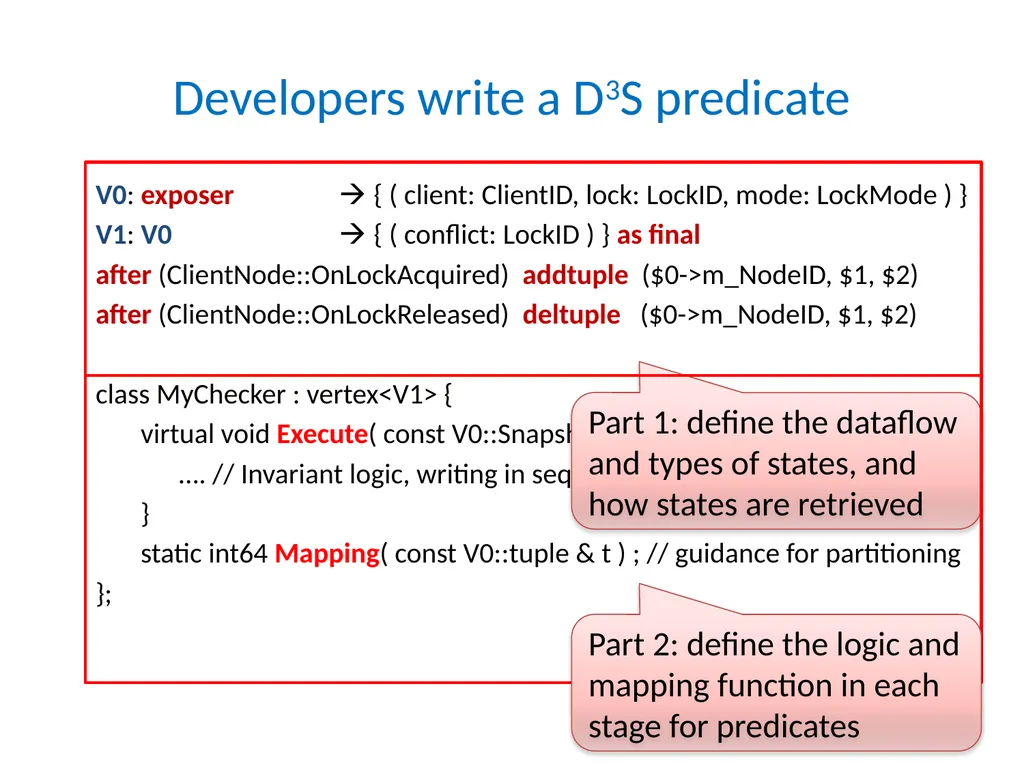
Developers write a D3S predicate V0: exposer { ( client: ClientID, lock: LockID, mode: LockMode ) }
V1: V0 { ( conflict: LockID ) } as final
after (ClientNode::OnLockAcquired) addtuple ($0->m_NodeID, $1, $2)
after (ClientNode::OnLockReleased) deltuple ($0->m_NodeID, $1, $2)
class MyChecker : vertex<V1> {
virtual void Execute( const V0::Snapshot & snapshot ) {
…. // Invariant logic, writing in sequential style
}
static int64 Mapping( const V0::tuple & t ) ; // guidance for partitioning
}; Part 1: define the dataflow and types of states, and how states are retrieved Part 2: define the logic and mapping function in each stage for predicates<br>
11
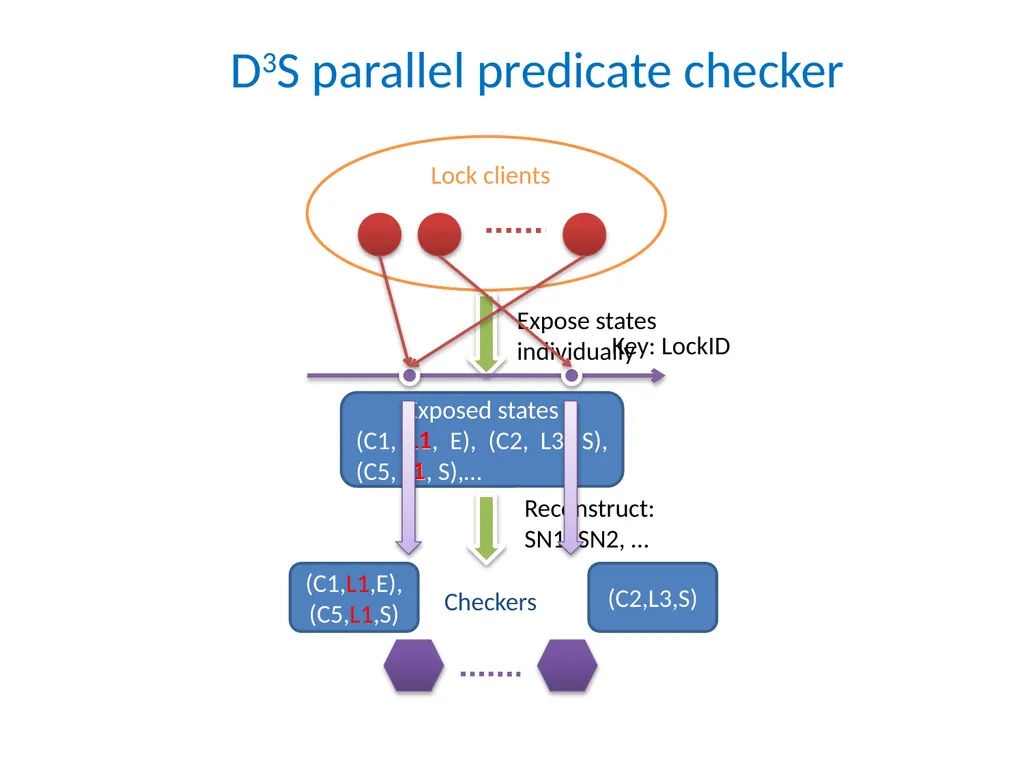
D3S parallel predicate checker Lock clients Checkers Expose states
individually Reconstruct:
SN1, SN2, … Exposed states
(C1, L1, E), (C2, L3, S), (C5, L1, S),… L1 L1 (C1,L1,E),(C5,L1,S) (C2,L3,S)<br>
individually Reconstruct:
SN1, SN2, … Exposed states
(C1, L1, E), (C2, L3, S), (C5, L1, S),… L1 L1 (C1,L1,E),(C5,L1,S) (C2,L3,S)<br>
12
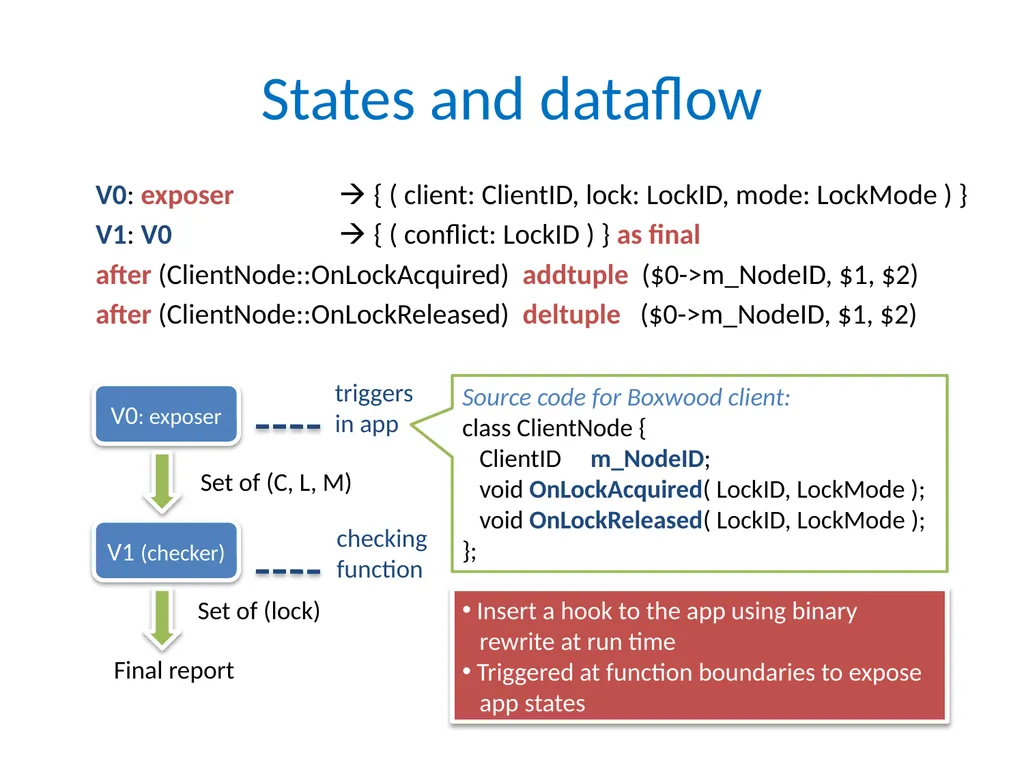
States and dataflow V0: exposer { ( client: ClientID, lock: LockID, mode: LockMode ) }
V1: V0 { ( conflict: LockID ) } as final
after (ClientNode::OnLockAcquired) addtuple ($0->m_NodeID, $1, $2)
after (ClientNode::OnLockReleased) deltuple ($0->m_NodeID, $1, $2) Insert a hook to the app using binary rewrite at run time
Triggered at function boundaries to expose app states<br>
V1: V0 { ( conflict: LockID ) } as final
after (ClientNode::OnLockAcquired) addtuple ($0->m_NodeID, $1, $2)
after (ClientNode::OnLockReleased) deltuple ($0->m_NodeID, $1, $2) Insert a hook to the app using binary rewrite at run time
Triggered at function boundaries to expose app states<br>
13
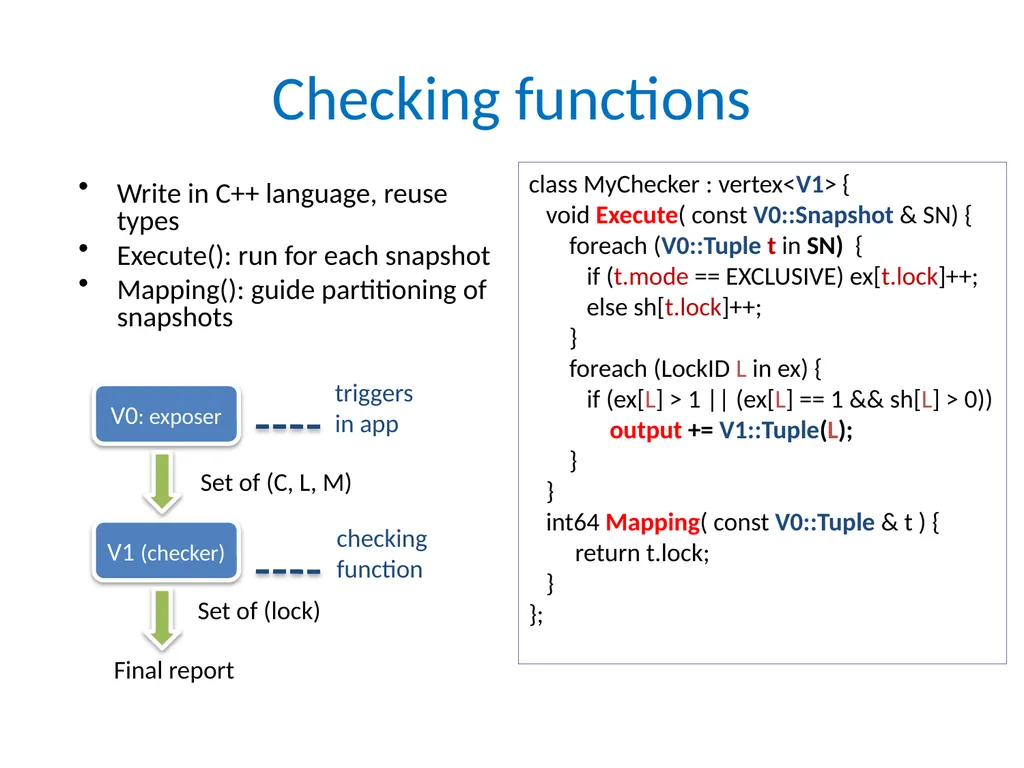
Checking functions Write in C++ language, reuse types
Execute(): run for each snapshot
Mapping(): guide partitioning of snapshots V1 (checker) Set of (lock) Final report class MyChecker : vertex<V1> {
void Execute( const V0::Snapshot & SN) {
foreach (V0::Tuple t in SN) {
if (t.mode == EXCLUSIVE) ex[t.lock]++;
else sh[t.lock]++;
}
foreach (LockID L in ex) {
if (ex[L] > 1 || (ex[L] == 1 && sh[L] > 0))
output += V1::Tuple(L);
}
}
int64 Mapping( const V0::Tuple & t ) {
return t.lock;
}
};<br>
14
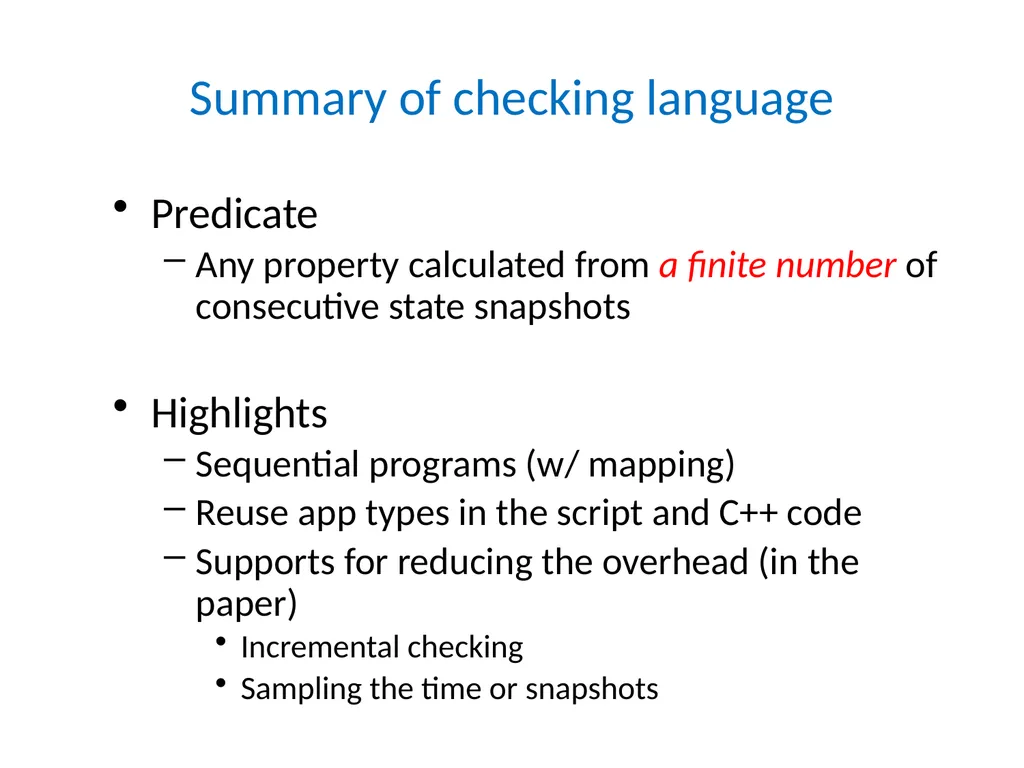
Summary of checking language Predicate
Any property calculated from a finite number of consecutive state snapshots
Highlights
Sequential programs (w/ mapping)
Reuse app types in the script and C++ code
Supports for reducing the overhead (in the paper)
Incremental checking
Sampling the time or snapshots<br>
Any property calculated from a finite number of consecutive state snapshots
Highlights
Sequential programs (w/ mapping)
Reuse app types in the script and C++ code
Supports for reducing the overhead (in the paper)
Incremental checking
Sampling the time or snapshots<br>
15
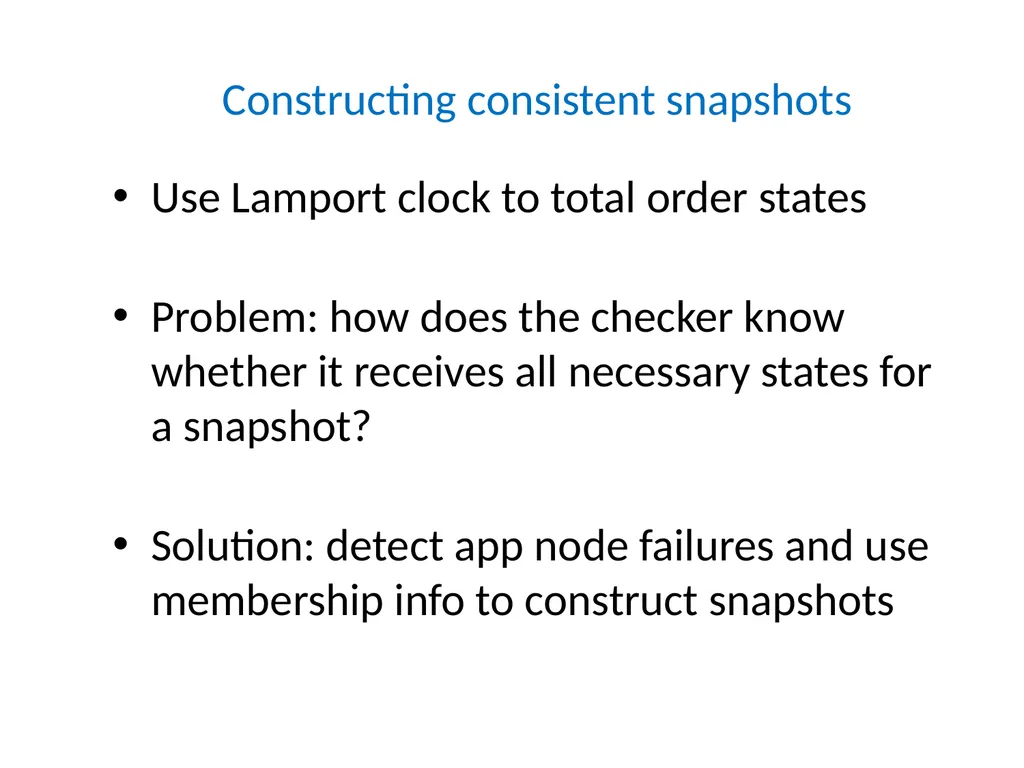
Constructing consistent snapshots Use Lamport clock to total order states
Problem: how does the checker know whether it receives all necessary states for a snapshot?
Solution: detect app node failures and use membership info to construct snapshots<br>
Problem: how does the checker know whether it receives all necessary states for a snapshot?
Solution: detect app node failures and use membership info to construct snapshots<br>
16
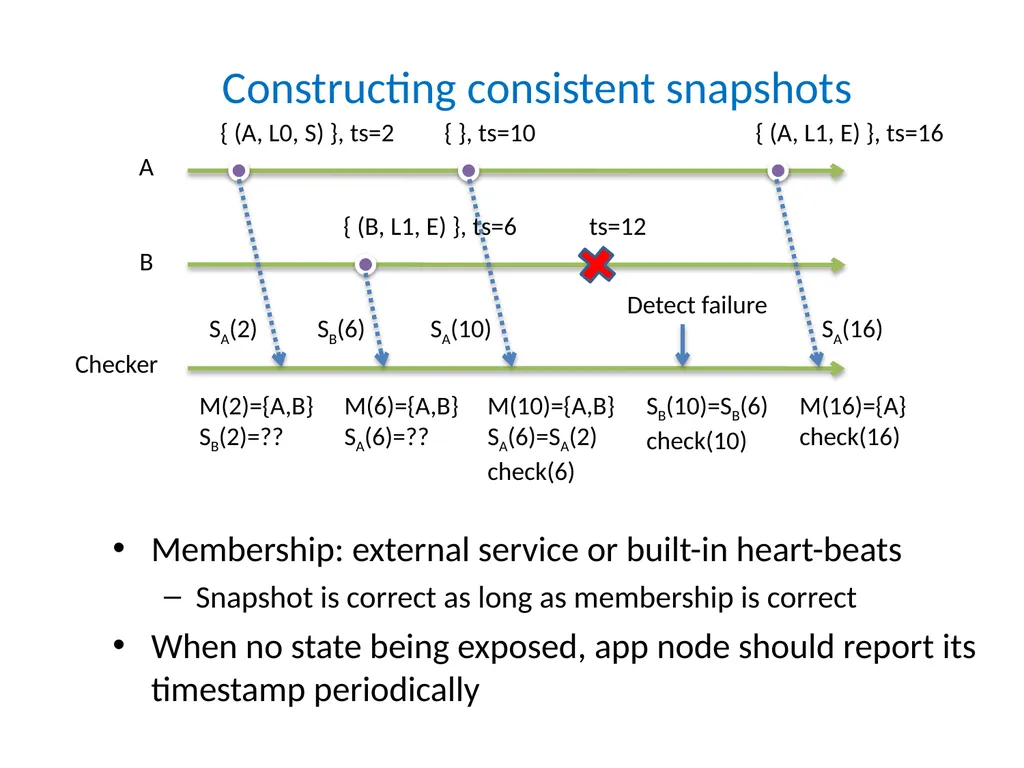
Constructing consistent snapshots Membership: external service or built-in heart-beats
Snapshot is correct as long as membership is correct
When no state being exposed, app node should report its timestamp periodically A B Checker { (A, L0, S) }, ts=2 { (B, L1, E) }, ts=6 { }, ts=10 ts=12 { (A, L1, E) }, ts=16 M(2)={A,B}
SB(2)=?? M(6)={A,B}
SA(6)=?? M(10)={A,B}
SA(6)=SA(2)
check(6) Detect failure SB(10)=SB(6)
check(10) M(16)={A}
check(16)<br>
17
Fault tolerant checking When a checker fails
Remap unassigned key to another checker
Re-calculate the snapshots<br>
Remap unassigned key to another checker
Re-calculate the snapshots<br>
18
Experimental method By debugging 5 real systems, we answer
Can D3S help developers find bugs?
Are predicates simple to write?
Is the checking overhead acceptable?
None of the apps are written by us!<br>
Can D3S help developers find bugs?
Are predicates simple to write?
Is the checking overhead acceptable?
None of the apps are written by us!<br>
19
Case study: Leader-election Predicate
There is at most one leader in each group of replicas
Deployment
8 machines (1 Gb Ethernet, 2 GHz Intel Xeon CPU, and 4 GB memory)
Test scenario: database app with random I/O (40 MB/s per machine at peak time)
Randomly crash & restart processes
Debugging
3 checkers, partitioned by replica groups
Time to trigger violation: several hours<br>
20
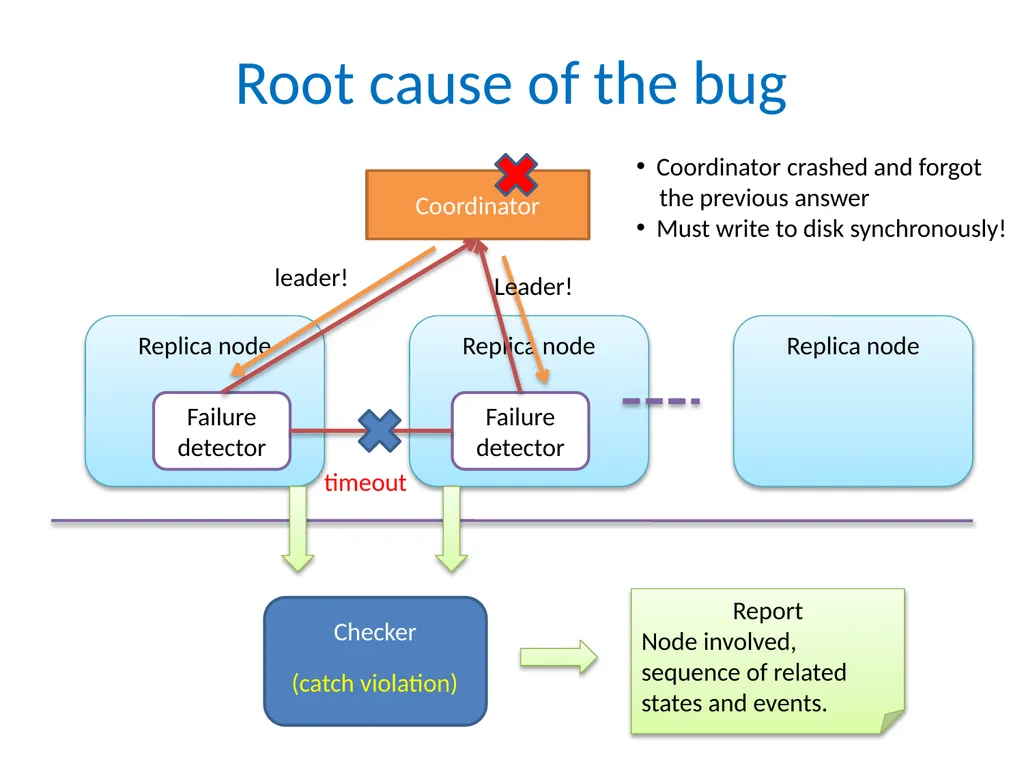
Root cause of the bug Coordinator Replica node Replica node Failure detector Failure detector Checker timeout Replica node Coordinator crashed and forgot
the previous answer
Must write to disk synchronously!<br>
the previous answer
Must write to disk synchronously!<br>
21
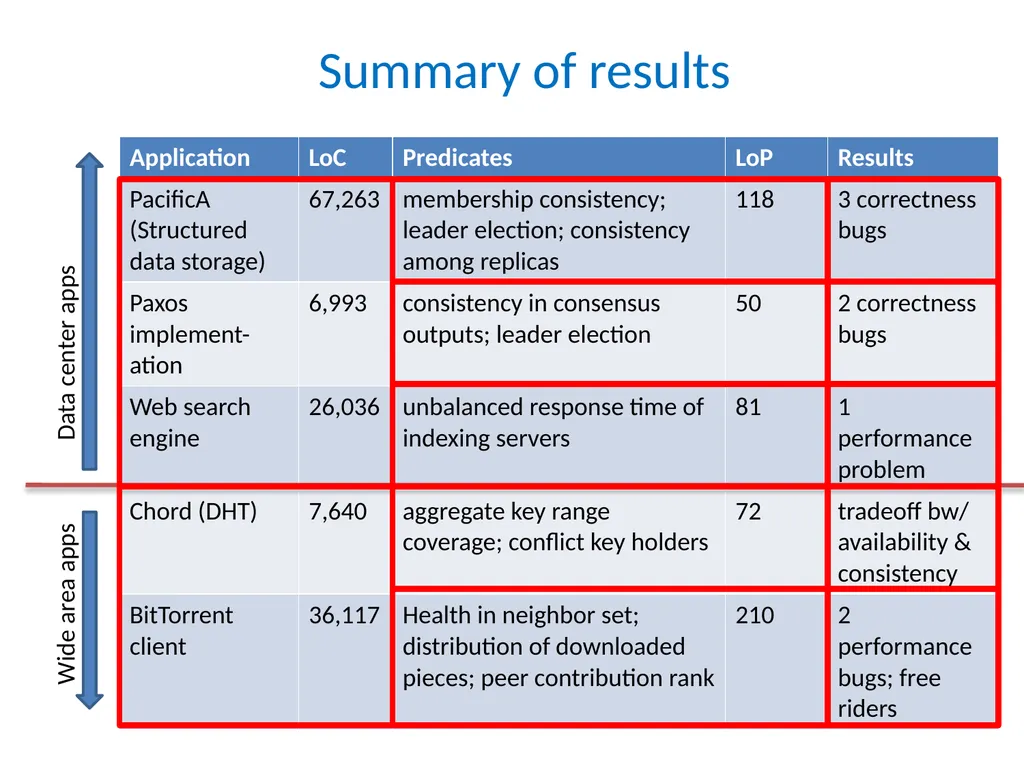
Summary of results Data center apps Wide area apps<br>
22
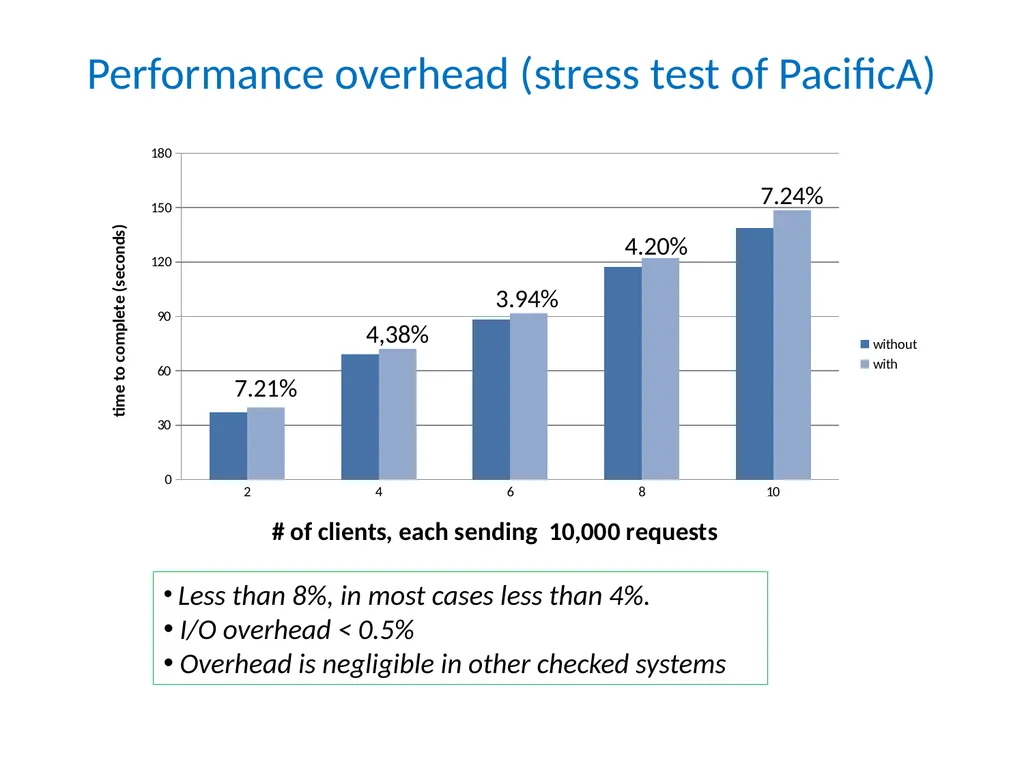
Performance overhead (stress test of PacificA) Less than 8%, in most cases less than 4%.
I/O overhead < 0.5%
Overhead is negligible in other checked systems<br>
I/O overhead < 0.5%
Overhead is negligible in other checked systems<br>
23
Related work Log analysis
Magpie[OSDI’04], Pip[NSDI’06], X-Trace[NSDI’07]
Predicate checking at replay time
WiDS Checker[NSDI’07], Friday[NSDI’07]
P2-based online monitoring
P2-monitor[EuroSys’06]
Model checking
MaceMC[NSDI’07], CMC[OSDI’04]<br>
Magpie[OSDI’04], Pip[NSDI’06], X-Trace[NSDI’07]
Predicate checking at replay time
WiDS Checker[NSDI’07], Friday[NSDI’07]
P2-based online monitoring
P2-monitor[EuroSys’06]
Model checking
MaceMC[NSDI’07], CMC[OSDI’04]<br>
24
Conclusions Predicate checking is effective for debugging deployed & large-scale distributed systems
D3S enables:
Change of what is monitored on-the-fly
Checking with multiple checkers
Specify predicate in sequential & centralized manner<br>
D3S enables:
Change of what is monitored on-the-fly
Checking with multiple checkers
Specify predicate in sequential & centralized manner<br>
25
Thanks & Q/A<br>
26
Design goals An advanced predicate checker designed for deployment & large scale
Deployment
Flexibility: change which states are checked on-the-fly
Low overhead
Large scale
Distributed checking
Failure-tolerance: continue to check correctly when
App node fails
Checking machine fails<br>
Deployment
Flexibility: change which states are checked on-the-fly
Low overhead
Large scale
Distributed checking
Failure-tolerance: continue to check correctly when
App node fails
Checking machine fails<br>
27
Case study: PacificA A BigTable-like distributed database
Replica group management
Perfect failure detection on storage node
Group reconfiguration to handle node failures
Primary-backup replication
Two-phase commit for consistent updates
Data reconciliation when re-joining a node<br>
Replica group management
Perfect failure detection on storage node
Group reconfiguration to handle node failures
Primary-backup replication
Two-phase commit for consistent updates
Data reconciliation when re-joining a node<br>
28
Case study: PacificA A bunch of invariants stem from the design
Group consistency:
single-primary in all replica groups
Data consistency
same data for the same version number
Reliability
when committing, all replicas are already prepared
Correctness of reconciliation
After joining the group, the new node have up-to-date states
Etc…
Specify the invariants as predicates, and check them
Necessary to use multiple checkers
Result: detected 3 correctness bugs caused by atomicity violation and incorrect failure handling<br>
29
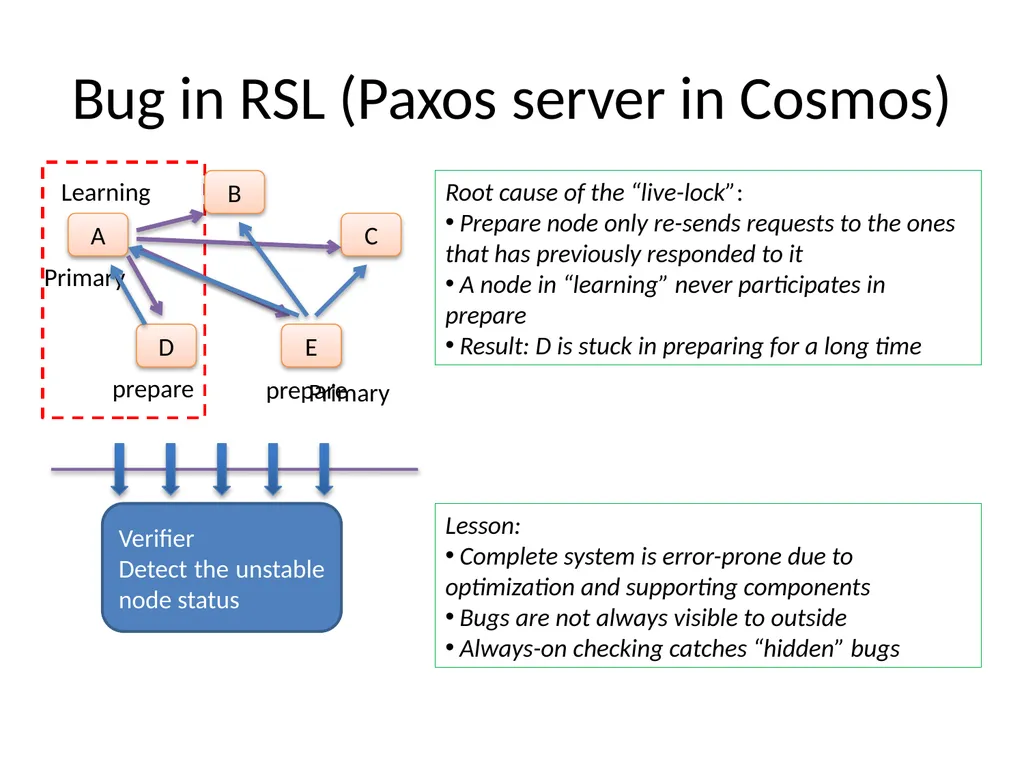
Bug in RSL (Paxos server in Cosmos) RSL
1 primary, 4 secondaries
Two phase commit
Leader election/failure detection D E Primary prepare prepare Primary Learning Root cause of the “live-lock”:
Prepare node only re-sends requests to the ones that has previously responded to it
A node in “learning” never participates in prepare
Result: D is stuck in preparing for a long time Lesson:
Complete system is error-prone due to optimization and supporting components
Bugs are not always visible to outside
Always-on checking catches “hidden” bugs<br>
30
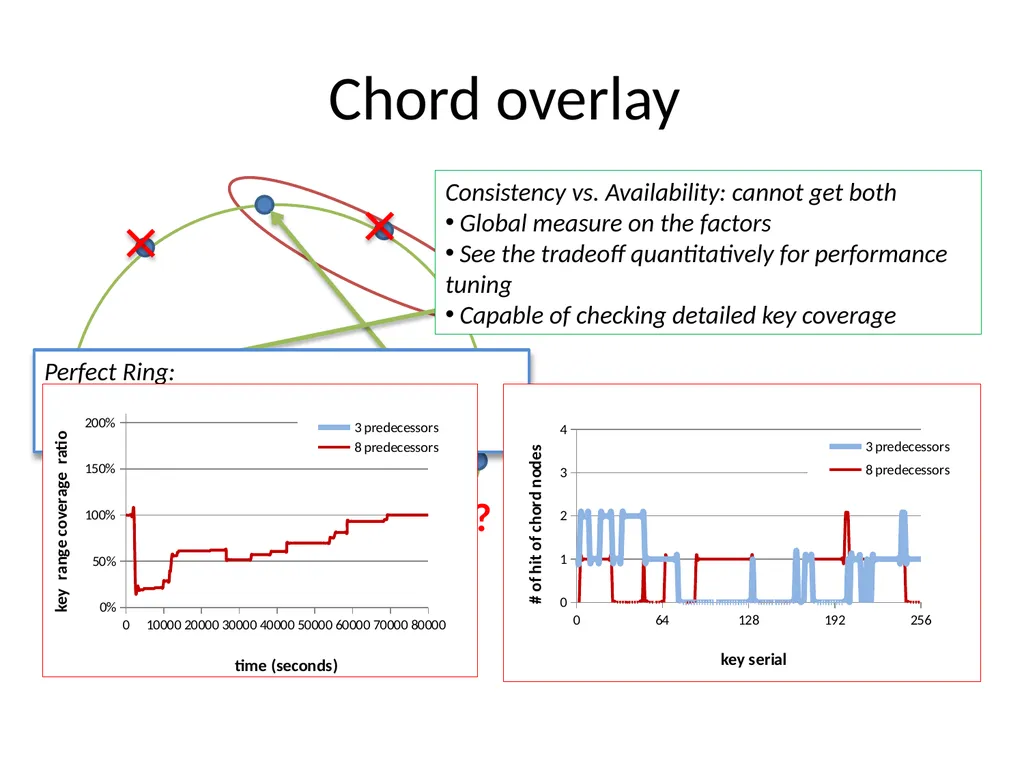
Chord overlay Perfect Ring:
No overlap, no hole
Aggregated key coverage is 100% ??? Consistency vs. Availability: cannot get both
Global measure on the factors
See the tradeoff quantitatively for performance tuning
Capable of checking detailed key coverage<br>
No overlap, no hole
Aggregated key coverage is 100% ??? Consistency vs. Availability: cannot get both
Global measure on the factors
See the tradeoff quantitatively for performance tuning
Capable of checking detailed key coverage<br>