
Eco 6380 Predictive Analytics For Economists
Description: Eco 6380 Predictive Analytics For Economists Spring 2016 Professor Tom Fomby Department of Economics SMU Presentation 8 Ensemble Predictions, Bagging and Boosting Classroom Notes Benefits of Combining Forecasts The accuracy of Ensemble
Related Topics
Download Presentation
"Eco 6380 Predictive Analytics For Economists" is the property of its rightful owner. Permission is granted to download and print the materials on this website for personal, non-commercial use only, and to display it on your personal computer provided you do not modify the materials and that you retain all copyright notices contained in the materials. By downloading content from our website, you accept the terms of this agreement.
Presentation Transcript
slide1. Eco 6380
Predictive Analytics For Economists
Spring 2016 Professor Tom Fomby
Department of Economics
SMU<br>
slide2. Presentation 8 Ensemble Predictions, Bagging and Boosting Classroom Notes<br>
slide3. Benefits of Combining Forecasts The accuracy of Ensemble (Combination) predictions are usually better (especially if the individual methods making up the ensemble are pre-picked (“trimmed”) and there are not too many of them (rule of thumb: 4 or less)
This general result holds in both prediction and classification problems<br>
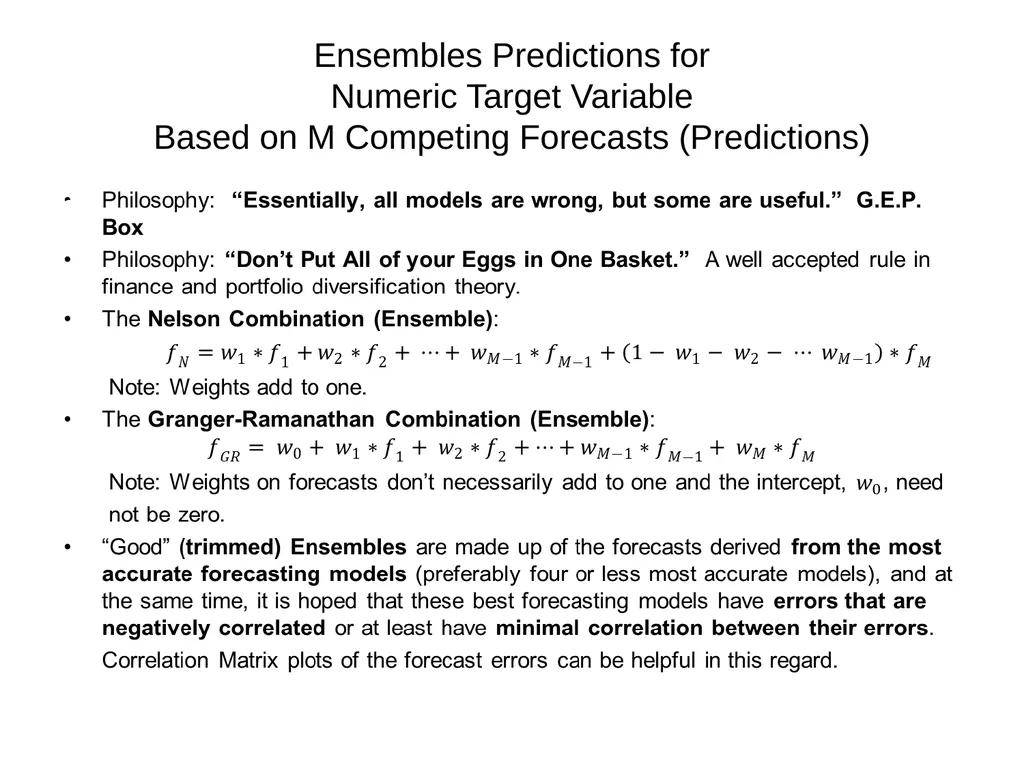
slide4. Ensembles Predictions for Numeric Target Variable Based on M Competing Forecasts (Predictions)<br>
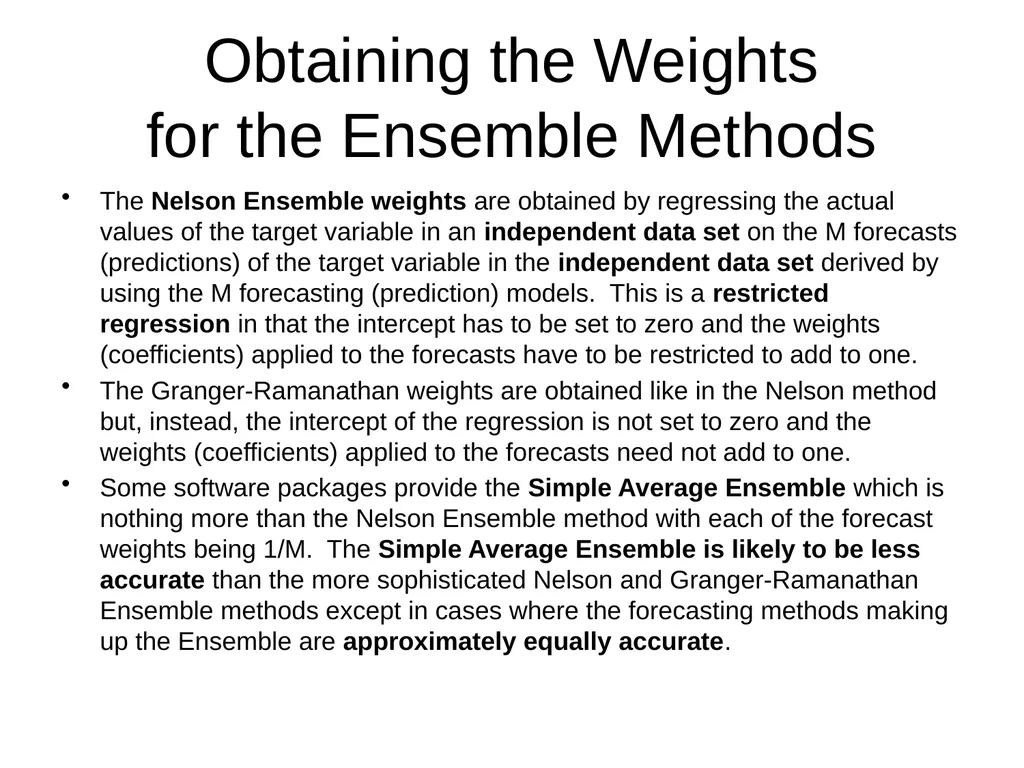
slide5. Obtaining the Weights for the Ensemble Methods The Nelson Ensemble weights are obtained by regressing the actual values of the target variable in an independent data set on the M forecasts (predictions) of the target variable in the independent data set derived by using the M forecasting (prediction) models. This is a restricted regression in that the intercept has to be set to zero and the weights (coefficients) applied to the forecasts have to be restricted to add to one.
The Granger-Ramanathan weights are obtained like in the Nelson method but, instead, the intercept of the regression is not set to zero and the weights (coefficients) applied to the forecasts need not add to one.
Some software packages provide the Simple Average Ensemble which is nothing more than the Nelson Ensemble method with each of the forecast weights being 1/M. The Simple Average Ensemble is likely to be less accurate than the more sophisticated Nelson and Granger-Ramanathan Ensemble methods except in cases where the forecasting methods making up the Ensemble are approximately equally accurate.<br>
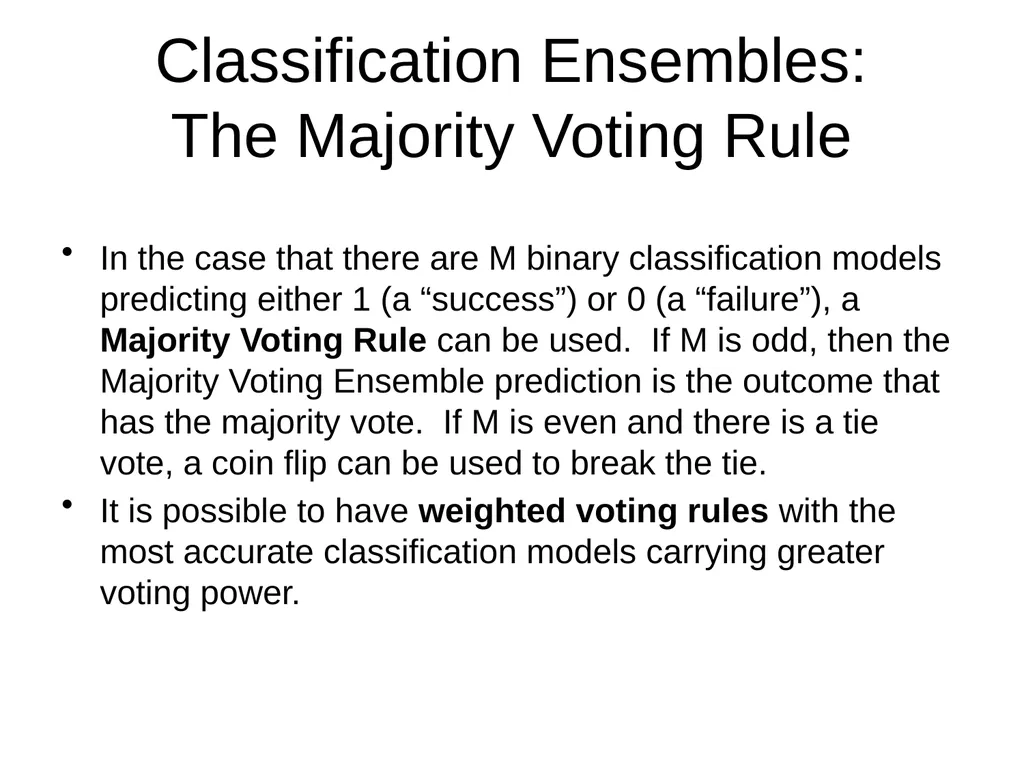
slide6. Classification Ensembles: The Majority Voting Rule In the case that there are M binary classification models predicting either 1 (a “success”) or 0 (a “failure”), a Majority Voting Rule can be used. If M is odd, then the Majority Voting Ensemble prediction is the outcome that has the majority vote. If M is even and there is a tie vote, a coin flip can be used to break the tie.
It is possible to have weighted voting rules with the most accurate classification models carrying greater voting power.<br>
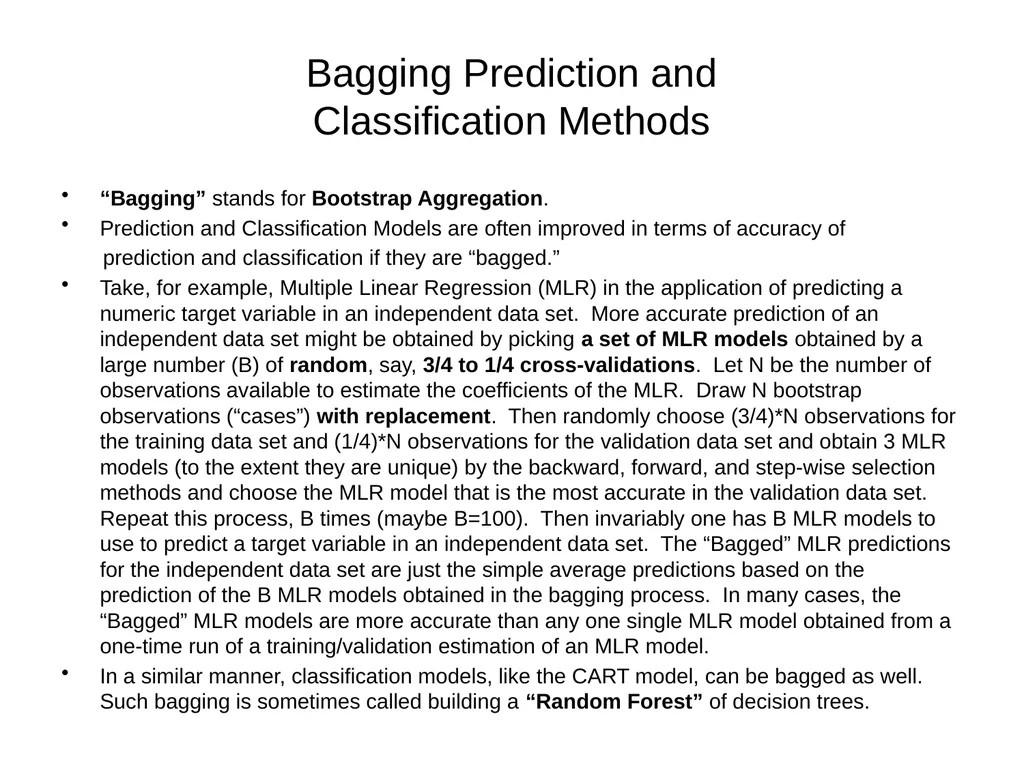
slide7. Bagging Prediction and Classification Methods “Bagging” stands for Bootstrap Aggregation.
Prediction and Classification Models are often improved in terms of accuracy of
prediction and classification if they are “bagged.”
Take, for example, Multiple Linear Regression (MLR) in the application of predicting a numeric target variable in an independent data set. More accurate prediction of an independent data set might be obtained by picking a set of MLR models obtained by a large number (B) of random, say, 3/4 to 1/4 cross-validations. Let N be the number of observations available to estimate the coefficients of the MLR. Draw N bootstrap observations (“cases”) with replacement. Then randomly choose (3/4)*N observations for the training data set and (1/4)*N observations for the validation data set and obtain 3 MLR models (to the extent they are unique) by the backward, forward, and step-wise selection methods and choose the MLR model that is the most accurate in the validation data set. Repeat this process, B times (maybe B=100). Then invariably one has B MLR models to use to predict a target variable in an independent data set. The “Bagged” MLR predictions for the independent data set are just the simple average predictions based on the prediction of the B MLR models obtained in the bagging process. In many cases, the “Bagged” MLR models are more accurate than any one single MLR model obtained from a one-time run of a training/validation estimation of an MLR model.
In a similar manner, classification models, like the CART model, can be bagged as well. Such bagging is sometimes called building a “Random Forest” of decision trees.<br>
slide8. “Boosting” a Model Boosting – Combines models of the same type (e.g., decision tree) and is iterative, i.e., a new model is influenced by the performance of the previously built model.
If, for example, there are several cases that were very poorly predicted by a CART tree, these cases are given more weight and a second CART tree is fit to the data. This process continues with successive reweighting of “tough to classify cases” and the building of a succession of trees reflecting the successive reweighting of tough cases.
Like Bagging, Boosting of a classifier (or predictor) leads to Majority Voting of classifications or simple averages of predictions across the succession of boosted versions of the given model.
The most popular of Boosting Methods is called AdaBoost.M1
For more on AdaBoost.M1 see AdaBoost.M1.pdf.<br>
slide9. Now for a Discussion of the Nelson and Granger-Ramanathan Ensemble Methods read the comments in the SAS program combo.sas and run it. The data analyzed is from the article by J.A. Brandt and D.A. Bessler entitled "Price Forecasting and Evaluation: An Application in Agriculture," Journal of Forecasting (July - Sept. 1983), pp. 237-248.<br>
Department of Economics
SMU<br>
slide2. Presentation 8 Ensemble Predictions, Bagging and Boosting Classroom Notes<br>
slide3. Benefits of Combining Forecasts The accuracy of Ensemble (Combination) predictions are usually better (especially if the individual methods making up the ensemble are pre-picked (“trimmed”) and there are not too many of them (rule of thumb: 4 or less)
This general result holds in both prediction and classification problems<br>
slide4. Ensembles Predictions for Numeric Target Variable Based on M Competing Forecasts (Predictions)<br>
slide5. Obtaining the Weights for the Ensemble Methods The Nelson Ensemble weights are obtained by regressing the actual values of the target variable in an independent data set on the M forecasts (predictions) of the target variable in the independent data set derived by using the M forecasting (prediction) models. This is a restricted regression in that the intercept has to be set to zero and the weights (coefficients) applied to the forecasts have to be restricted to add to one.
The Granger-Ramanathan weights are obtained like in the Nelson method but, instead, the intercept of the regression is not set to zero and the weights (coefficients) applied to the forecasts need not add to one.
Some software packages provide the Simple Average Ensemble which is nothing more than the Nelson Ensemble method with each of the forecast weights being 1/M. The Simple Average Ensemble is likely to be less accurate than the more sophisticated Nelson and Granger-Ramanathan Ensemble methods except in cases where the forecasting methods making up the Ensemble are approximately equally accurate.<br>
slide6. Classification Ensembles: The Majority Voting Rule In the case that there are M binary classification models predicting either 1 (a “success”) or 0 (a “failure”), a Majority Voting Rule can be used. If M is odd, then the Majority Voting Ensemble prediction is the outcome that has the majority vote. If M is even and there is a tie vote, a coin flip can be used to break the tie.
It is possible to have weighted voting rules with the most accurate classification models carrying greater voting power.<br>
slide7. Bagging Prediction and Classification Methods “Bagging” stands for Bootstrap Aggregation.
Prediction and Classification Models are often improved in terms of accuracy of
prediction and classification if they are “bagged.”
Take, for example, Multiple Linear Regression (MLR) in the application of predicting a numeric target variable in an independent data set. More accurate prediction of an independent data set might be obtained by picking a set of MLR models obtained by a large number (B) of random, say, 3/4 to 1/4 cross-validations. Let N be the number of observations available to estimate the coefficients of the MLR. Draw N bootstrap observations (“cases”) with replacement. Then randomly choose (3/4)*N observations for the training data set and (1/4)*N observations for the validation data set and obtain 3 MLR models (to the extent they are unique) by the backward, forward, and step-wise selection methods and choose the MLR model that is the most accurate in the validation data set. Repeat this process, B times (maybe B=100). Then invariably one has B MLR models to use to predict a target variable in an independent data set. The “Bagged” MLR predictions for the independent data set are just the simple average predictions based on the prediction of the B MLR models obtained in the bagging process. In many cases, the “Bagged” MLR models are more accurate than any one single MLR model obtained from a one-time run of a training/validation estimation of an MLR model.
In a similar manner, classification models, like the CART model, can be bagged as well. Such bagging is sometimes called building a “Random Forest” of decision trees.<br>
slide8. “Boosting” a Model Boosting – Combines models of the same type (e.g., decision tree) and is iterative, i.e., a new model is influenced by the performance of the previously built model.
If, for example, there are several cases that were very poorly predicted by a CART tree, these cases are given more weight and a second CART tree is fit to the data. This process continues with successive reweighting of “tough to classify cases” and the building of a succession of trees reflecting the successive reweighting of tough cases.
Like Bagging, Boosting of a classifier (or predictor) leads to Majority Voting of classifications or simple averages of predictions across the succession of boosted versions of the given model.
The most popular of Boosting Methods is called AdaBoost.M1
For more on AdaBoost.M1 see AdaBoost.M1.pdf.<br>
slide9. Now for a Discussion of the Nelson and Granger-Ramanathan Ensemble Methods read the comments in the SAS program combo.sas and run it. The data analyzed is from the article by J.A. Brandt and D.A. Bessler entitled "Price Forecasting and Evaluation: An Application in Agriculture," Journal of Forecasting (July - Sept. 1983), pp. 237-248.<br>