
Harnessing epoch-based reclamation for efficient
Description: Harnessing epoch-based reclamation for efficient range queries Trevor Brown, IST Austria Motivation Lots of data structures offer search, insert, delete Many real applications (e.g., databases) also require range query operations
Related Topics
Download Presentation
"Harnessing epoch-based reclamation for efficient" is the property of its rightful owner. Permission is granted to download and print the materials on this website for personal, non-commercial use only, and to display it on your personal computer provided you do not modify the materials and that you retain all copyright notices contained in the materials. By downloading content from our website, you accept the terms of this agreement.
Presentation Transcript
slide1. Harnessing epoch-based reclamation
for efficient range queries
Trevor Brown, IST Austria<br>
slide2. Motivation Lots of data structures offer search, insert, delete
Many real applications (e.g., databases) also require range query operations
range-query(lo,hi) returns all keys in [lo, hi) that are in the data structure
Requires an instantaneous snapshot
Traversing the data structure is not enough 2<br>
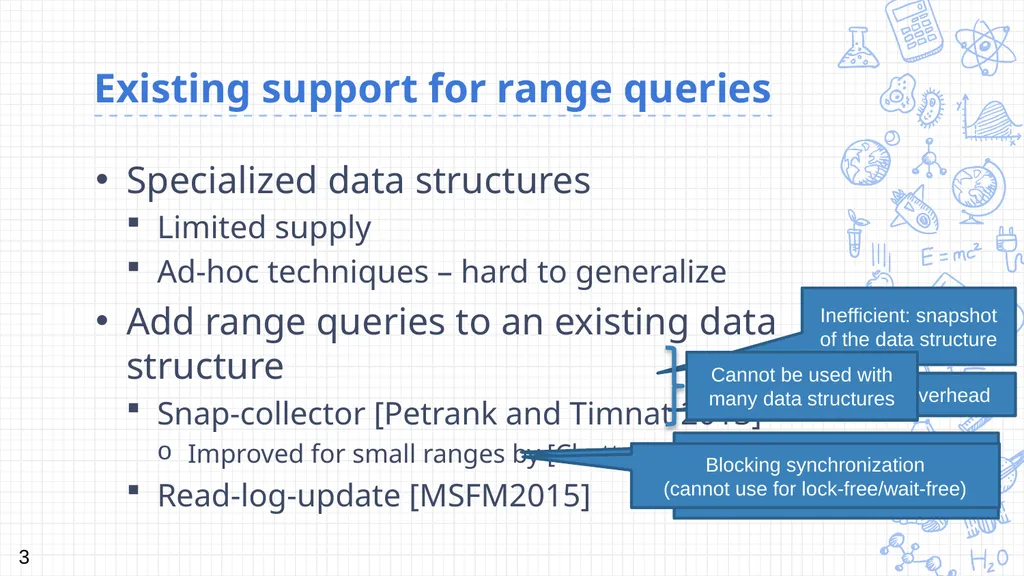
slide3. Existing support for range queries Specialized data structures
Limited supply
Ad-hoc techniques – hard to generalize
Add range queries to an existing data structure
Snap-collector [Petrank and Timnat 2013]
Improved for small ranges by [Chatterjee 2016]
Read-log-update [MSFM2015] 3 Still high overhead Inefficient: snapshot of the data structure Cannot be used with many data structures Must rewrite all synchronization; High overhead for updates Blocking synchronization
(cannot use for lock-free/wait-free)<br>
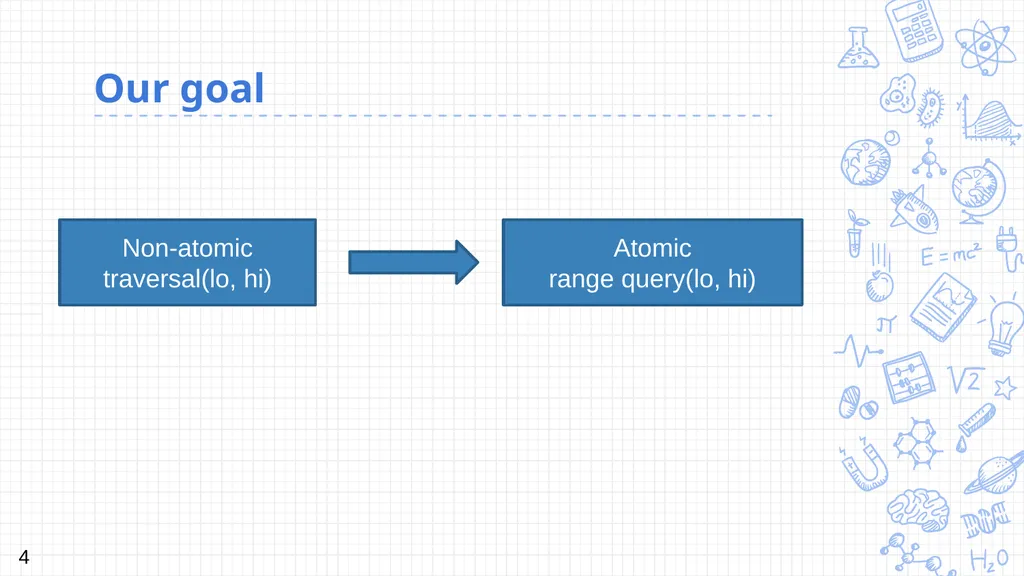
slide4. Our goal 4 Non-atomic traversal(lo, hi) Atomic range query(lo, hi)<br>
slide5. What should traversal guarantee? Traversal(lo, hi) should visit each node that:
contains a key in [lo, hi] and
is in the data structure at all times during the traversal
Many data structures satisfy this with a simple DFS-based traversal procedure (proof in paper) 5<br>
slide6. Other requirements Linearizable data structures
Each update that changes the data structure is linearized at a write or CAS
Programmer should know where they are linearized 6<br>
slide7. Effort to use our algorithm In a traversal
Invoke TraversalStart
Invoke Visit(node) for each node visited
Invoke TraversalEnd
In an update
Invoke UpdateWrite or UpdateCAS at lin. point 7<br>
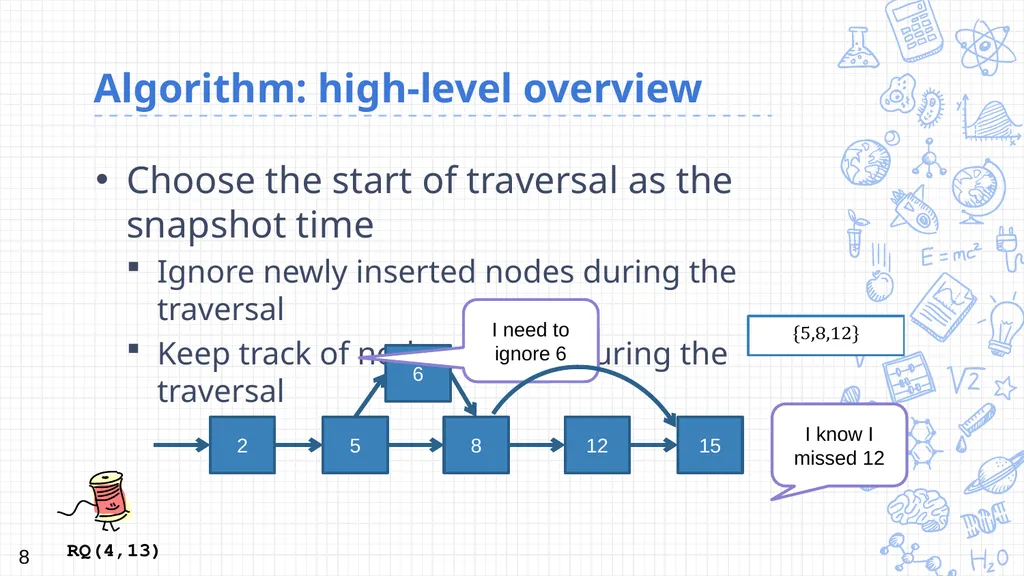
slide8. Algorithm: high-level overview Choose the start of traversal as the snapshot time
Ignore newly inserted nodes during the traversal
Keep track of nodes deleted during the traversal 2 5 8 12 15 RQ(4,13) 6 I need to ignore 6 I know I missed 12 8<br>
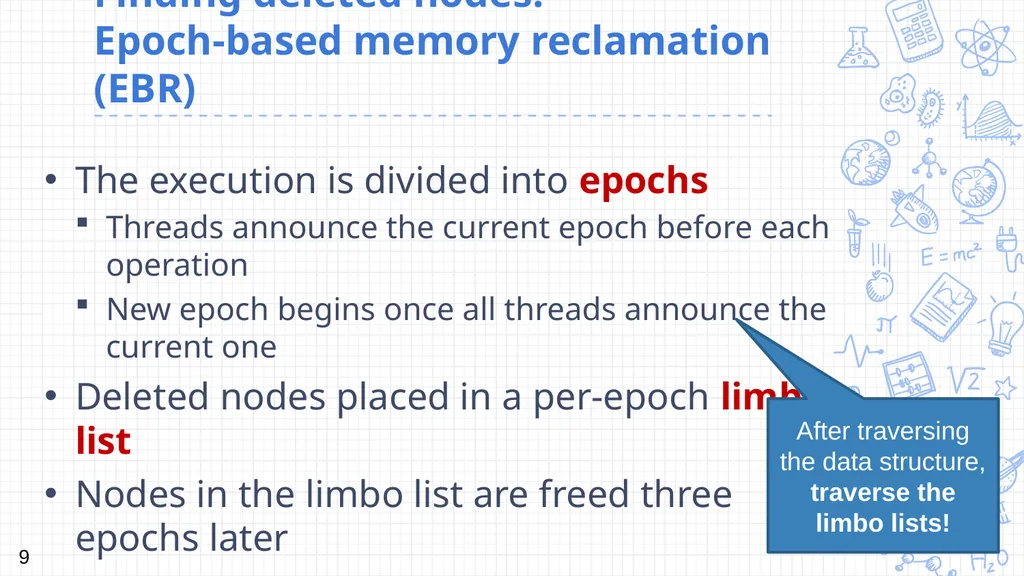
slide9. Finding deleted nodes: Epoch-based memory reclamation (EBR) The execution is divided into epochs
Threads announce the current epoch before each operation
New epoch begins once all threads announce the current one
Deleted nodes placed in a per-epoch limbo list
Nodes in the limbo list are freed three epochs later After traversing the data structure, traverse the limbo lists! 9<br>
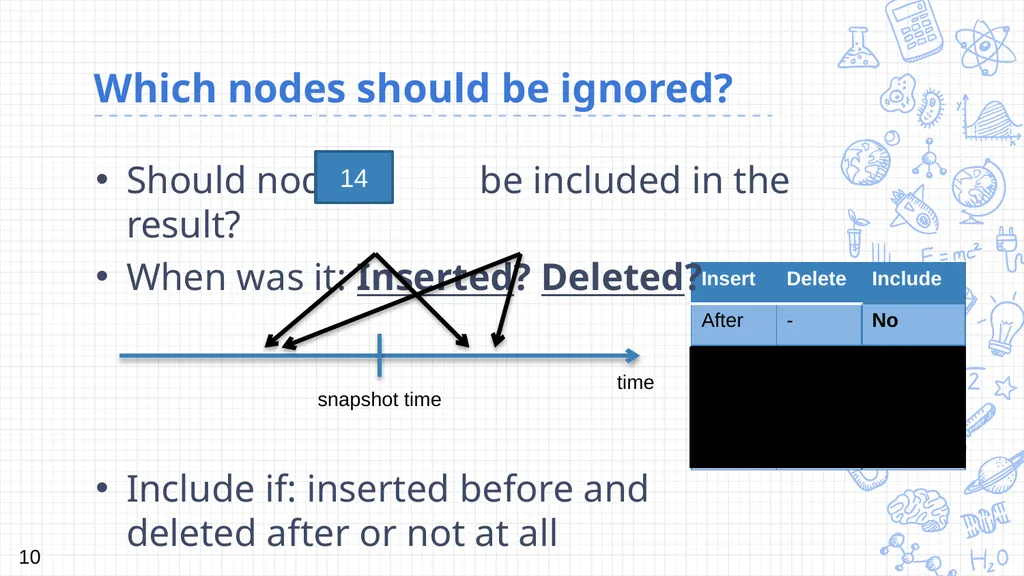
slide10. Which nodes should be ignored? Should node be included in the result?
When was it: Inserted? Deleted?
Include if: inserted before and deleted after or not at all time snapshot time 14 10<br>
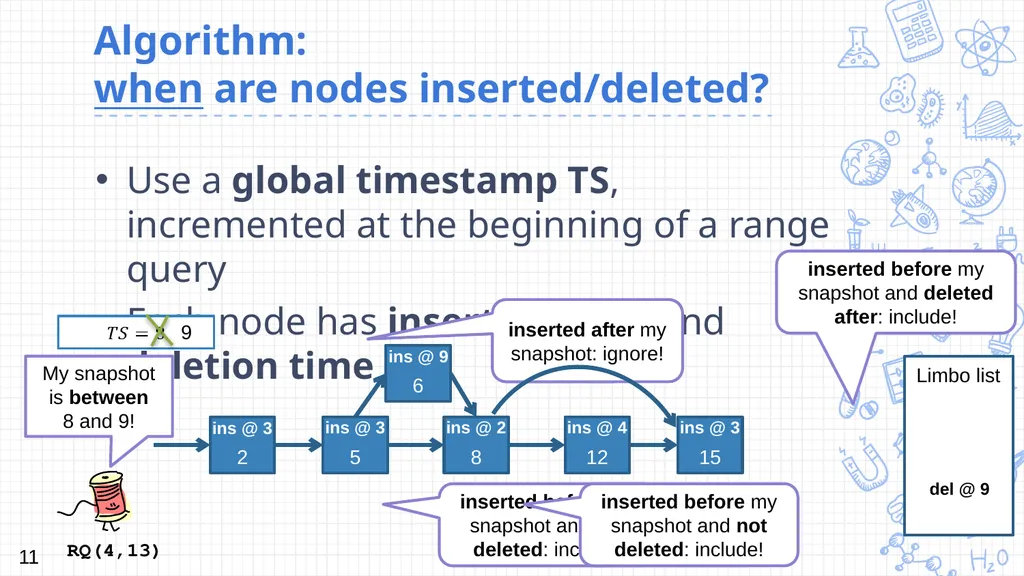
slide11. Algorithm: when are nodes inserted/deleted? Use a global timestamp TS, incremented at the beginning of a range query
Each node has insertion time and deletion time 2 5 8 15 RQ(4,13) 6 inserted after my snapshot: ignore! inserted before my snapshot and deleted after: include! My snapshot is between 8 and 9! ins @ 9 ins @ 3 ins @ 3 ins @ 2 ins @ 3 Limbo list 12 ins @ 4 del @ 9 inserted before my snapshot and not deleted: include! inserted before my snapshot and not deleted: include! 11<br>
slide12. Implementing node times Different algorithms for maintaining nodes’ times
Locking with shared and exclusive modes (Lock)
Hardware transactional memory (HTM)
Lock-free synchronization (Lock-free) 12<br>
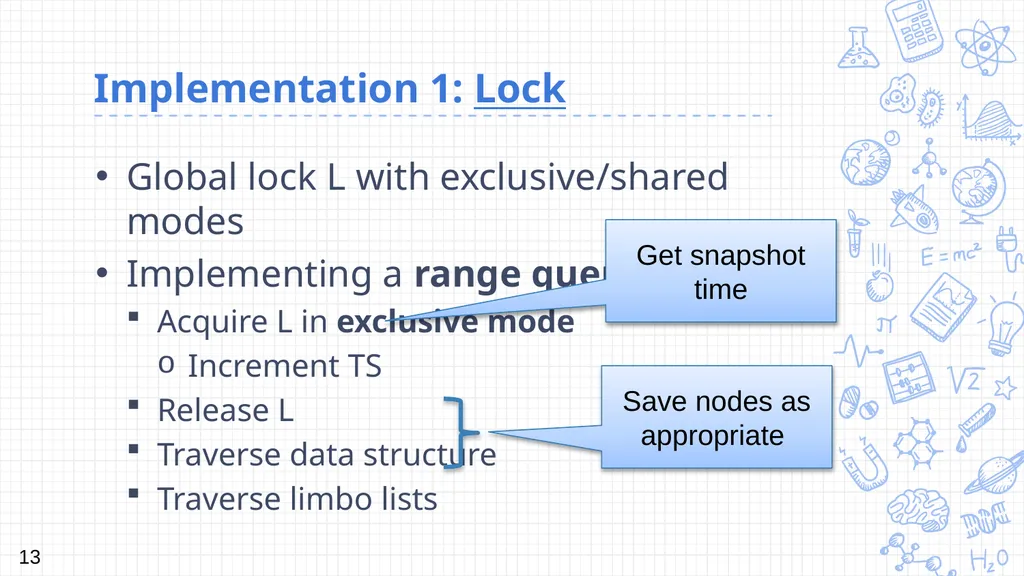
slide13. Implementation 1: Lock Global lock L with exclusive/shared modes
Implementing a range query
Acquire L in exclusive mode
Increment TS
Release L
Traverse data structure
Traverse limbo lists 13 Get snapshot time Save nodes as appropriate<br>
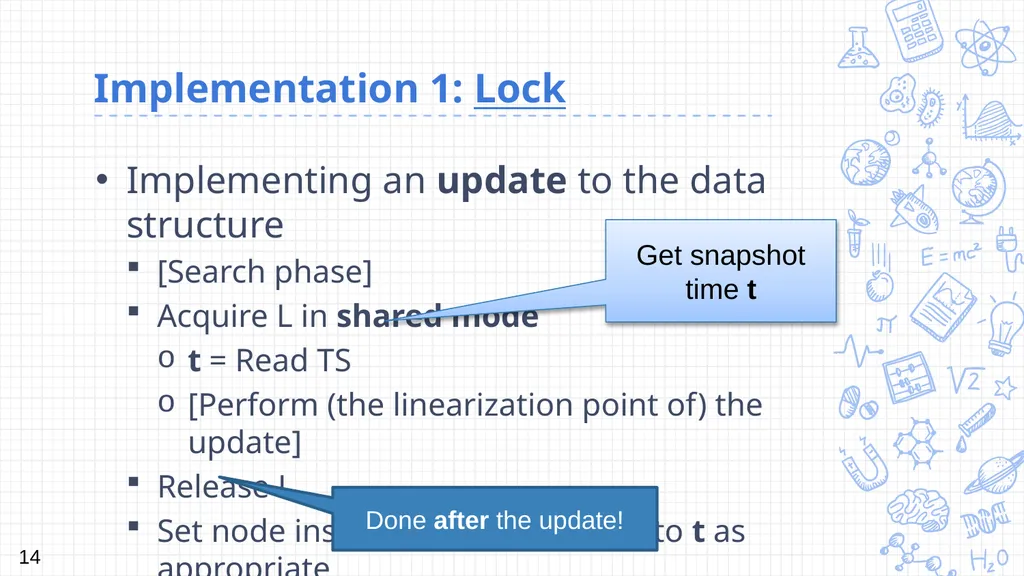
slide14. Implementation 1: Lock 14 Implementing an update to the data structure
[Search phase]
Acquire L in shared mode
t = Read TS
[Perform (the linearization point of) the update]
Release L
Set node insertion/deletion times to t as appropriate Get snapshot time t Done after the update!<br>
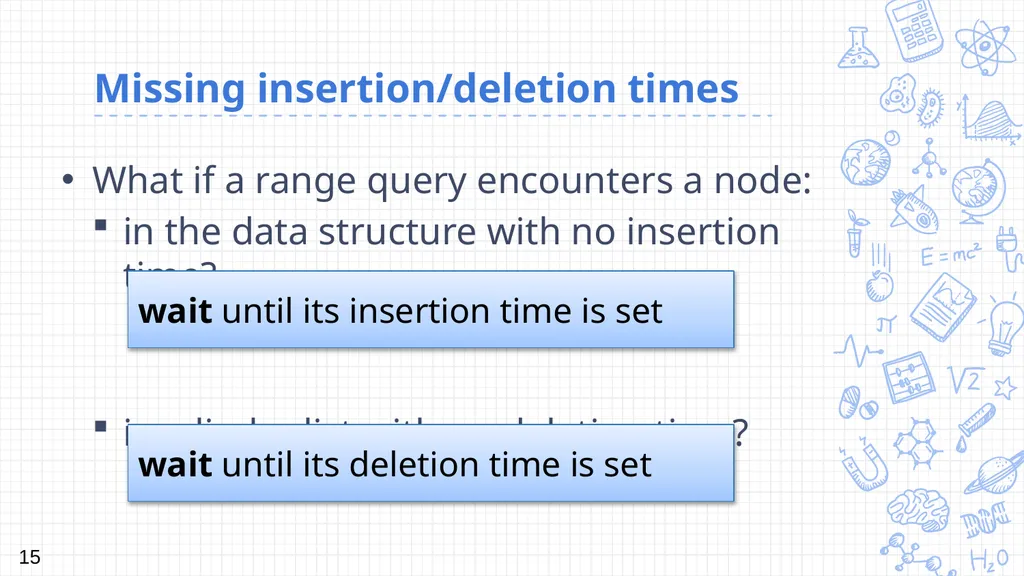
slide15. Missing insertion/deletion times What if a range query encounters a node:
in the data structure with no insertion time?
in a limbo list with no deletion time? 15 wait until its insertion time is set wait until its deletion time is set<br>
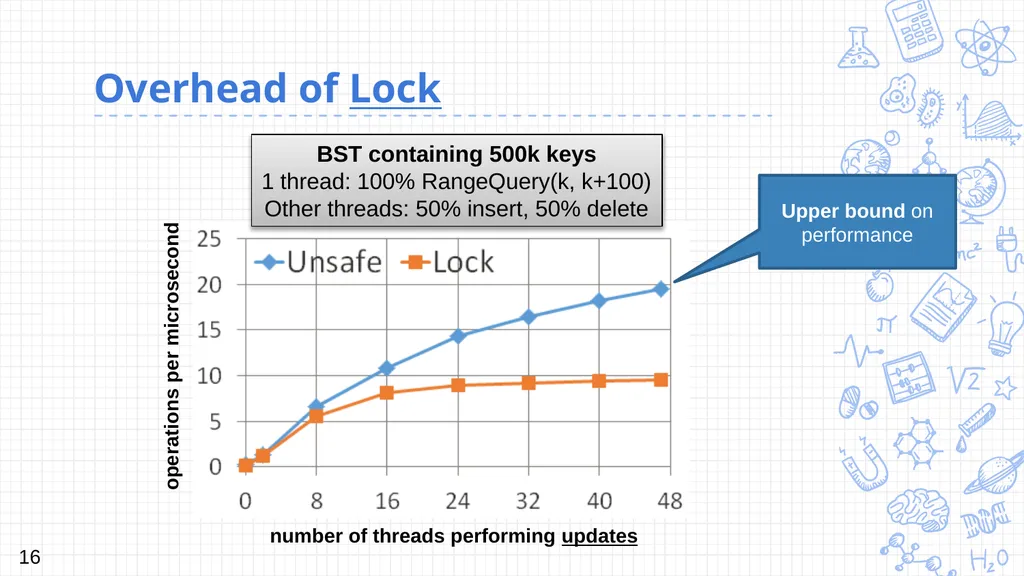
slide16. Overhead of Lock 16 operations per microsecond number of threads performing updates BST containing 500k keys
1 thread: 100% RangeQuery(k, k+100)
Other threads: 50% insert, 50% delete Upper bound on performance<br>
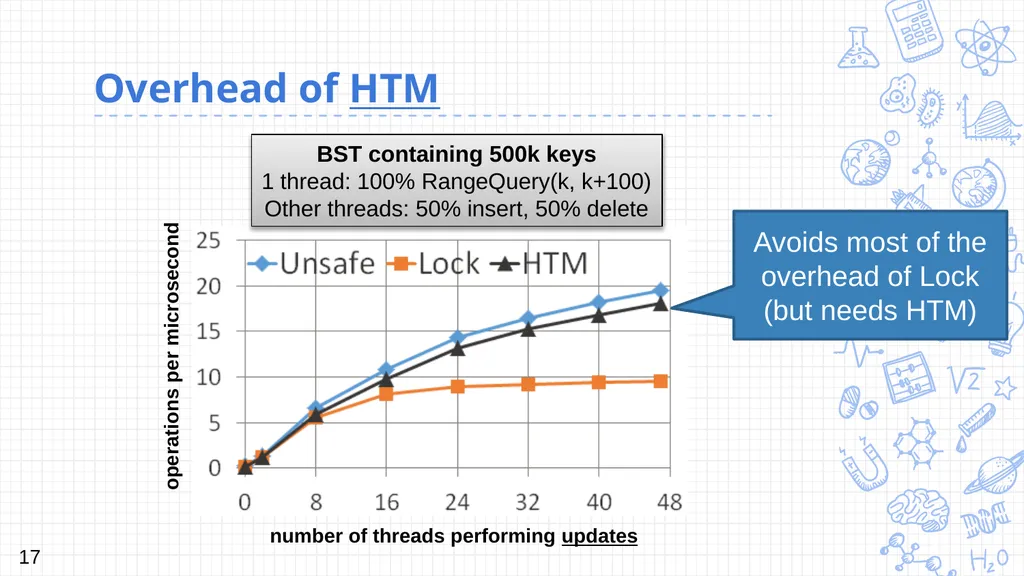
slide17. Overhead of HTM 17 operations per microsecond number of threads performing updates BST containing 500k keys
1 thread: 100% RangeQuery(k, k+100)
Other threads: 50% insert, 50% delete Avoids most of the overhead of Lock (but needs HTM)<br>
slide18. Implementation 3: Lock-free / wait-free Real subtlety is here
Main challenges:
Must atomically read TS and perform update’s lin. point without using locks
Cannot wait for missing insertion/deletion times 18<br>
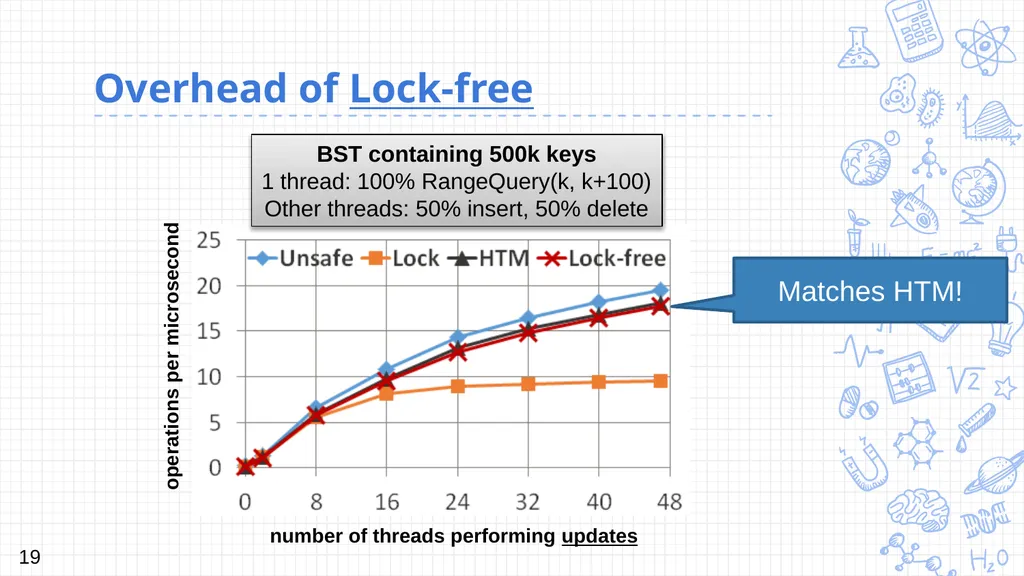
slide19. Overhead of Lock-free 19 operations per microsecond number of threads performing updates BST containing 500k keys
1 thread: 100% RangeQuery(k, k+100)
Other threads: 50% insert, 50% delete Matches HTM!<br>
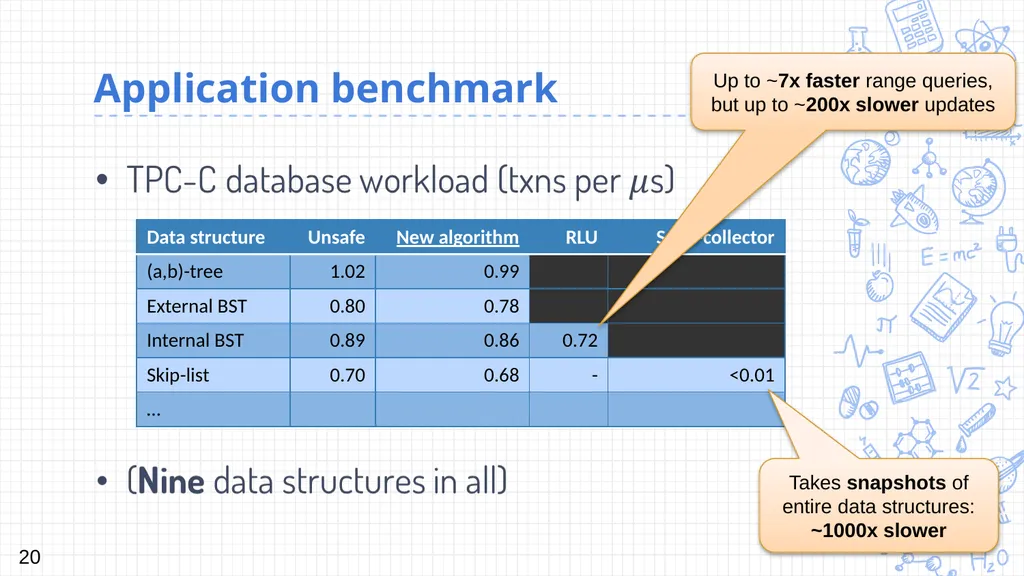
slide20. Application benchmark Up to ~7x faster range queries,
but up to ~200x slower updates Takes snapshots of entire data structures: ~1000x slower 20<br>
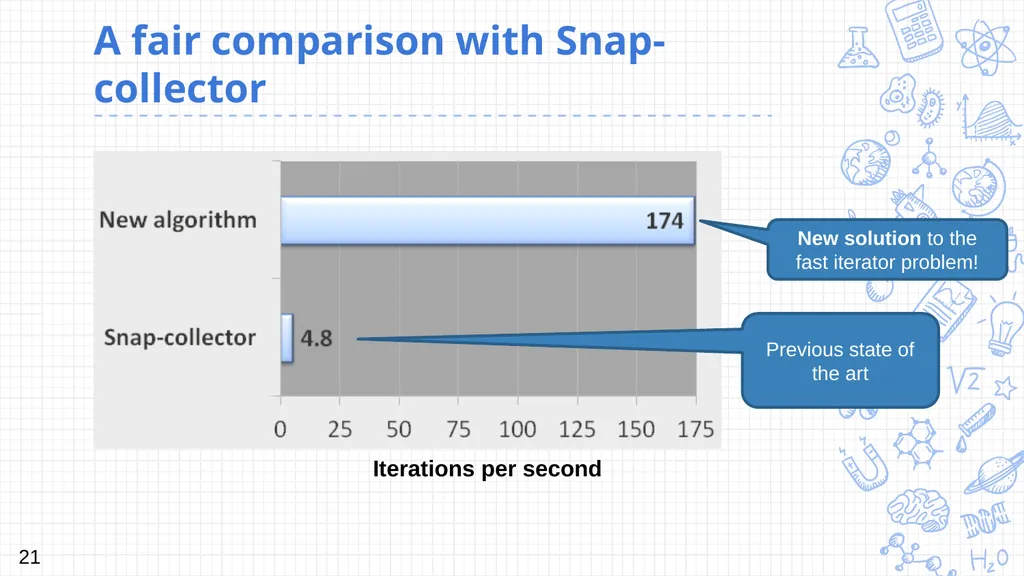
slide21. A fair comparison with Snap-collector Iterations per second 21 Previous state of the art New solution to the fast iterator problem!<br>
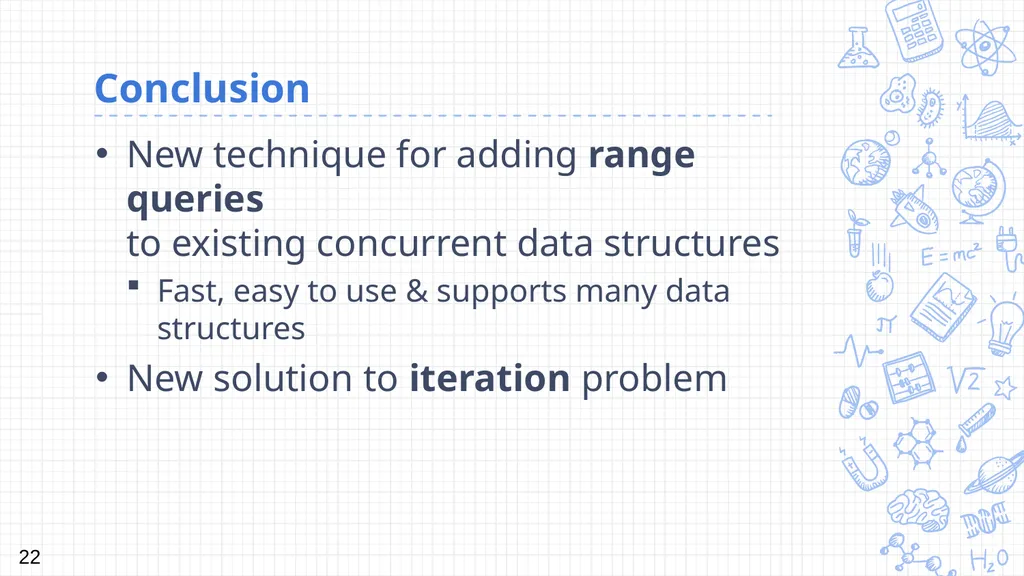
slide22. Conclusion New technique for adding range queries to existing concurrent data structures
Fast, easy to use & supports many data structures
New solution to iteration problem 22<br>
slide2. Motivation Lots of data structures offer search, insert, delete
Many real applications (e.g., databases) also require range query operations
range-query(lo,hi) returns all keys in [lo, hi) that are in the data structure
Requires an instantaneous snapshot
Traversing the data structure is not enough 2<br>
slide3. Existing support for range queries Specialized data structures
Limited supply
Ad-hoc techniques – hard to generalize
Add range queries to an existing data structure
Snap-collector [Petrank and Timnat 2013]
Improved for small ranges by [Chatterjee 2016]
Read-log-update [MSFM2015] 3 Still high overhead Inefficient: snapshot of the data structure Cannot be used with many data structures Must rewrite all synchronization; High overhead for updates Blocking synchronization
(cannot use for lock-free/wait-free)<br>
slide4. Our goal 4 Non-atomic traversal(lo, hi) Atomic range query(lo, hi)<br>
slide5. What should traversal guarantee? Traversal(lo, hi) should visit each node that:
contains a key in [lo, hi] and
is in the data structure at all times during the traversal
Many data structures satisfy this with a simple DFS-based traversal procedure (proof in paper) 5<br>
slide6. Other requirements Linearizable data structures
Each update that changes the data structure is linearized at a write or CAS
Programmer should know where they are linearized 6<br>
slide7. Effort to use our algorithm In a traversal
Invoke TraversalStart
Invoke Visit(node) for each node visited
Invoke TraversalEnd
In an update
Invoke UpdateWrite or UpdateCAS at lin. point 7<br>
slide8. Algorithm: high-level overview Choose the start of traversal as the snapshot time
Ignore newly inserted nodes during the traversal
Keep track of nodes deleted during the traversal 2 5 8 12 15 RQ(4,13) 6 I need to ignore 6 I know I missed 12 8<br>
slide9. Finding deleted nodes: Epoch-based memory reclamation (EBR) The execution is divided into epochs
Threads announce the current epoch before each operation
New epoch begins once all threads announce the current one
Deleted nodes placed in a per-epoch limbo list
Nodes in the limbo list are freed three epochs later After traversing the data structure, traverse the limbo lists! 9<br>
slide10. Which nodes should be ignored? Should node be included in the result?
When was it: Inserted? Deleted?
Include if: inserted before and deleted after or not at all time snapshot time 14 10<br>
slide11. Algorithm: when are nodes inserted/deleted? Use a global timestamp TS, incremented at the beginning of a range query
Each node has insertion time and deletion time 2 5 8 15 RQ(4,13) 6 inserted after my snapshot: ignore! inserted before my snapshot and deleted after: include! My snapshot is between 8 and 9! ins @ 9 ins @ 3 ins @ 3 ins @ 2 ins @ 3 Limbo list 12 ins @ 4 del @ 9 inserted before my snapshot and not deleted: include! inserted before my snapshot and not deleted: include! 11<br>
slide12. Implementing node times Different algorithms for maintaining nodes’ times
Locking with shared and exclusive modes (Lock)
Hardware transactional memory (HTM)
Lock-free synchronization (Lock-free) 12<br>
slide13. Implementation 1: Lock Global lock L with exclusive/shared modes
Implementing a range query
Acquire L in exclusive mode
Increment TS
Release L
Traverse data structure
Traverse limbo lists 13 Get snapshot time Save nodes as appropriate<br>
slide14. Implementation 1: Lock 14 Implementing an update to the data structure
[Search phase]
Acquire L in shared mode
t = Read TS
[Perform (the linearization point of) the update]
Release L
Set node insertion/deletion times to t as appropriate Get snapshot time t Done after the update!<br>
slide15. Missing insertion/deletion times What if a range query encounters a node:
in the data structure with no insertion time?
in a limbo list with no deletion time? 15 wait until its insertion time is set wait until its deletion time is set<br>
slide16. Overhead of Lock 16 operations per microsecond number of threads performing updates BST containing 500k keys
1 thread: 100% RangeQuery(k, k+100)
Other threads: 50% insert, 50% delete Upper bound on performance<br>
slide17. Overhead of HTM 17 operations per microsecond number of threads performing updates BST containing 500k keys
1 thread: 100% RangeQuery(k, k+100)
Other threads: 50% insert, 50% delete Avoids most of the overhead of Lock (but needs HTM)<br>
slide18. Implementation 3: Lock-free / wait-free Real subtlety is here
Main challenges:
Must atomically read TS and perform update’s lin. point without using locks
Cannot wait for missing insertion/deletion times 18<br>
slide19. Overhead of Lock-free 19 operations per microsecond number of threads performing updates BST containing 500k keys
1 thread: 100% RangeQuery(k, k+100)
Other threads: 50% insert, 50% delete Matches HTM!<br>
slide20. Application benchmark Up to ~7x faster range queries,
but up to ~200x slower updates Takes snapshots of entire data structures: ~1000x slower 20<br>
slide21. A fair comparison with Snap-collector Iterations per second 21 Previous state of the art New solution to the fast iterator problem!<br>
slide22. Conclusion New technique for adding range queries to existing concurrent data structures
Fast, easy to use & supports many data structures
New solution to iteration problem 22<br>