
MAJOR PROJECT SYNOPSIS EvalBench A Pytest-Style
Description: MAJOR PROJECT SYNOPSIS EvalBench A Pytest-Style Automated Evaluation Framework for Self-Hosted Large Language Models Aman Kumar Sharma (2501940041) Suhanee Gupta (2501940025) Under the supervision of Dr. Reenu Sharma K.R Mangalam University
Related Topics
Download Presentation
"MAJOR PROJECT SYNOPSIS EvalBench A Pytest-Style" is the property of its rightful owner. Permission is granted to download and print the materials on this website for personal, non-commercial use only, and to display it on your personal computer provided you do not modify the materials and that you retain all copyright notices contained in the materials. By downloading content from our website, you accept the terms of this agreement.
Presentation Transcript
slide1. MAJOR PROJECT SYNOPSIS EvalBench A Pytest-Style Automated Evaluation Framework for
Self-Hosted Large Language Models Aman Kumar Sharma (2501940041)
Suhanee Gupta (2501940025) Under the supervision of Dr. Reenu Sharma K.R Mangalam University · Department of Computer Science and Engineering<br>
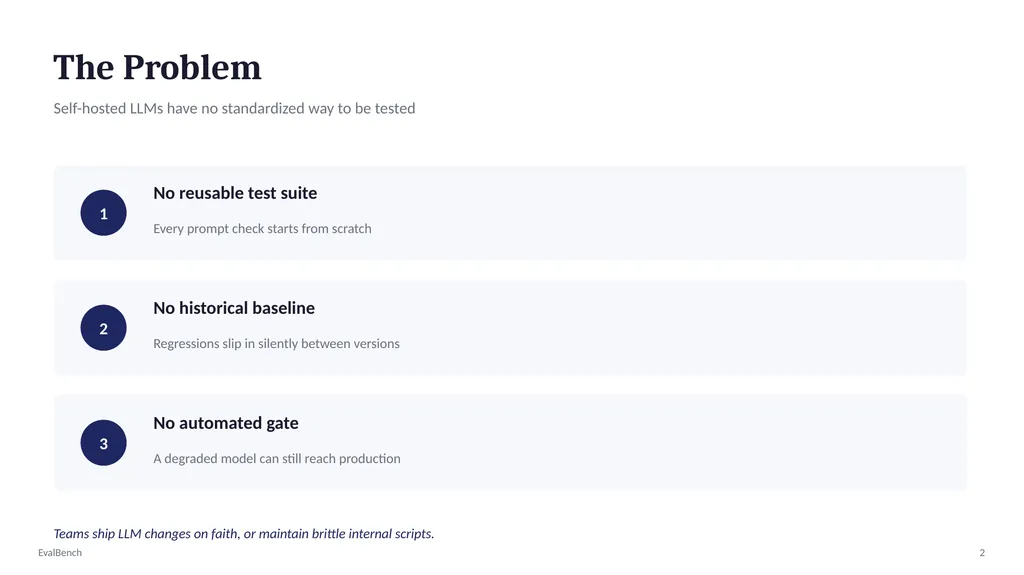
slide2. The Problem Self-hosted LLMs have no standardized way to be tested 1 No reusable test suite Every prompt check starts from scratch 2 No historical baseline Regressions slip in silently between versions 3 No automated gate A degraded model can still reach production Teams ship LLM changes on faith, or maintain brittle internal scripts. EvalBench 2<br>
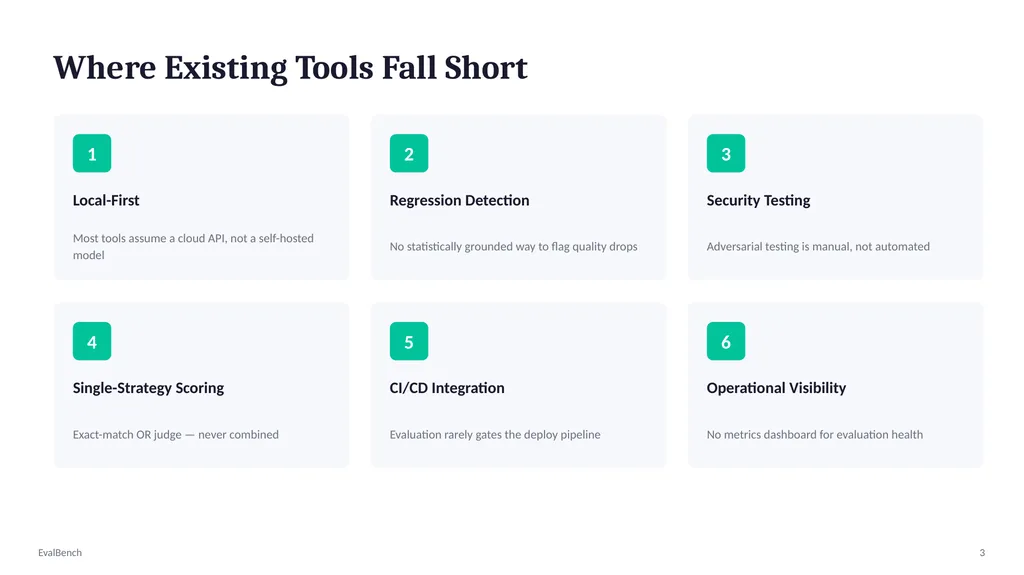
slide3. Where Existing Tools Fall Short 1 Local-First Most tools assume a cloud API, not a self-hosted model 2 Regression Detection No statistically grounded way to flag quality drops 3 Security Testing Adversarial testing is manual, not automated 4 Single-Strategy Scoring Exact-match OR judge — never combined 5 CI/CD Integration Evaluation rarely gates the deploy pipeline 6 Operational Visibility No metrics dashboard for evaluation health EvalBench 3<br>
slide4. The Solution EvalBench A locally-executed, pytest-style evaluation framework purpose-built
for self-hosted LLMs. Test suites authored declaratively in YAML Scored using four evaluator strategies Regressions flagged via paired t-test against a baseline Gates CI/CD pipelines automatically Never leaves the organization's infrastructure EvalBench 4<br>
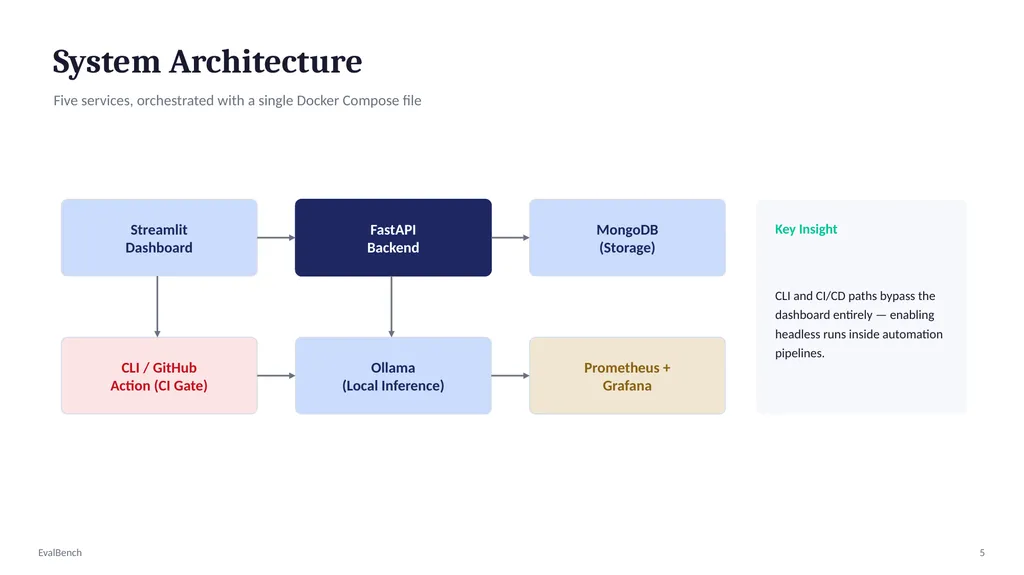
slide5. System Architecture Five services, orchestrated with a single Docker Compose file Streamlit
Dashboard FastAPI
Backend MongoDB
(Storage) CLI / GitHub
Action (CI Gate) Ollama
(Local Inference) Prometheus +
Grafana Key Insight CLI and CI/CD paths bypass the dashboard entirely — enabling headless runs inside automation pipelines. EvalBench 5<br>
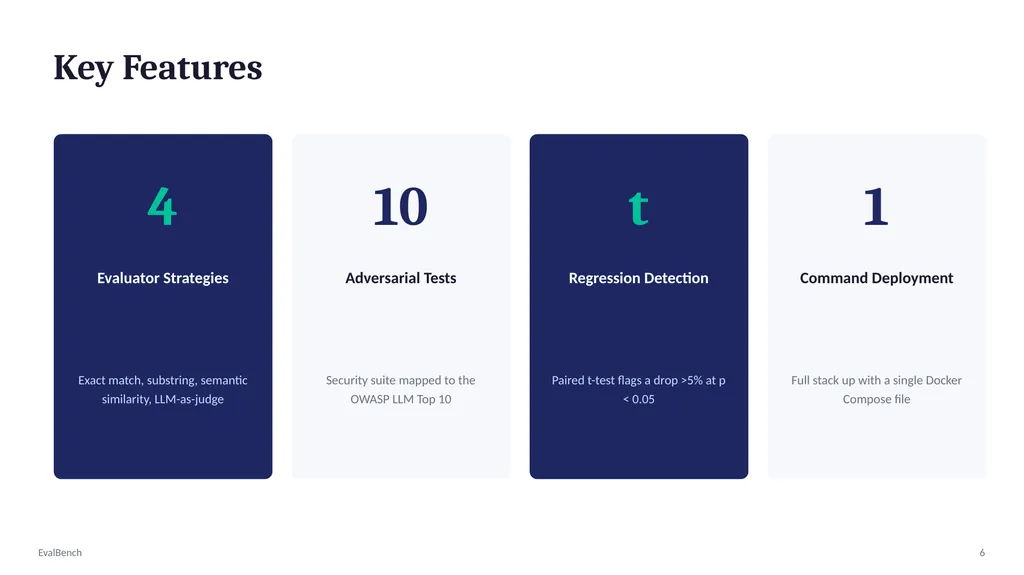
slide6. Key Features 4 Evaluator Strategies Exact match, substring, semantic similarity, LLM-as-judge 10 Adversarial Tests Security suite mapped to the OWASP LLM Top 10 t Regression Detection Paired t-test flags a drop >5% at p < 0.05 1 Command Deployment Full stack up with a single Docker Compose file EvalBench 6<br>
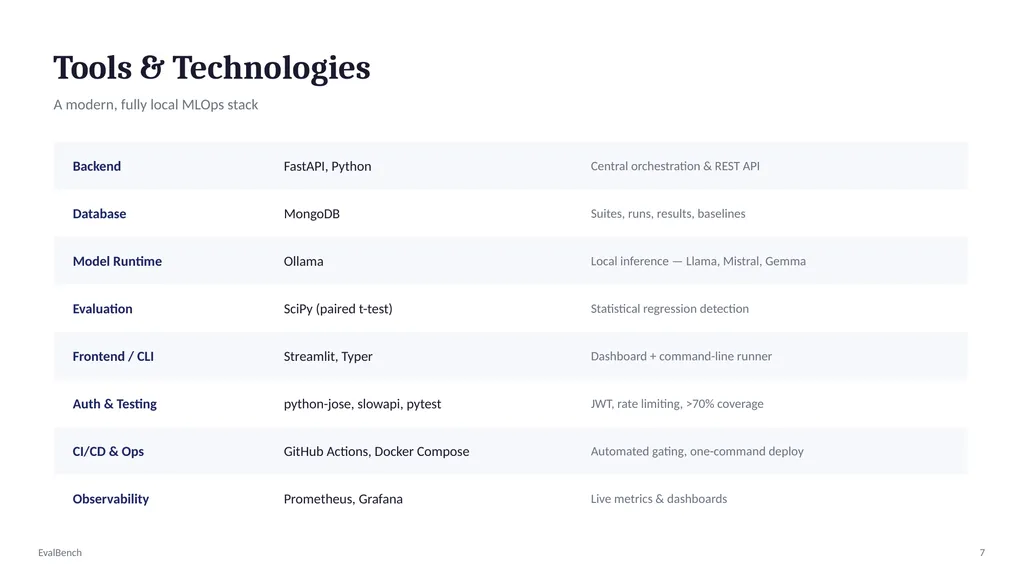
slide7. Tools & Technologies A modern, fully local MLOps stack Backend FastAPI, Python Central orchestration & REST API Database MongoDB Suites, runs, results, baselines Model Runtime Ollama Local inference — Llama, Mistral, Gemma Evaluation SciPy (paired t-test) Statistical regression detection Frontend / CLI Streamlit, Typer Dashboard + command-line runner Auth & Testing python-jose, slowapi, pytest JWT, rate limiting, >70% coverage CI/CD & Ops GitHub Actions, Docker Compose Automated gating, one-command deploy Observability Prometheus, Grafana Live metrics & dashboards EvalBench 7<br>
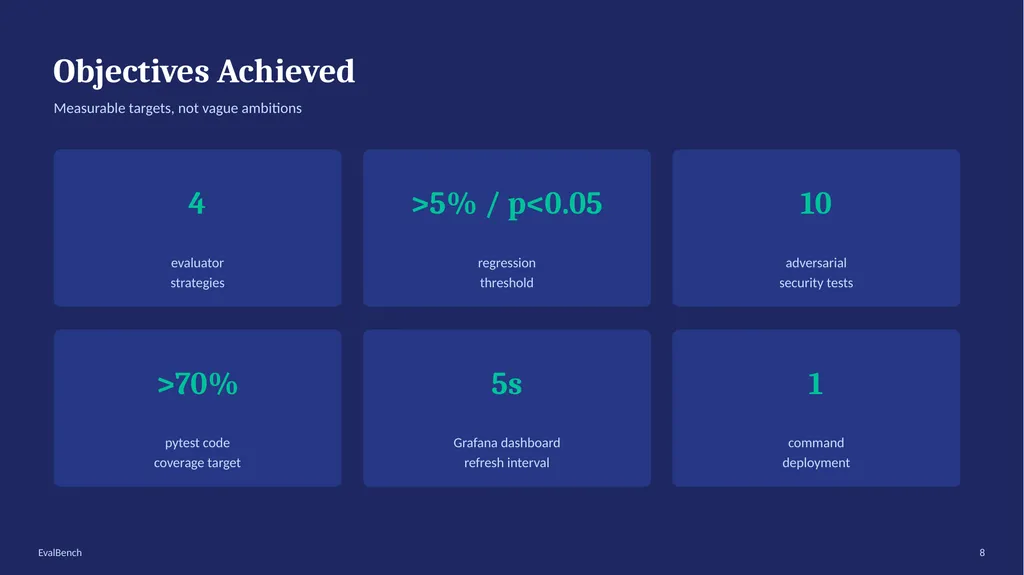
slide8. Objectives Achieved Measurable targets, not vague ambitions 4 evaluator
strategies >5% / p<0.05 regression
threshold 10 adversarial
security tests >70% pytest code
coverage target 5s Grafana dashboard
refresh interval 1 command
deployment EvalBench 8<br>
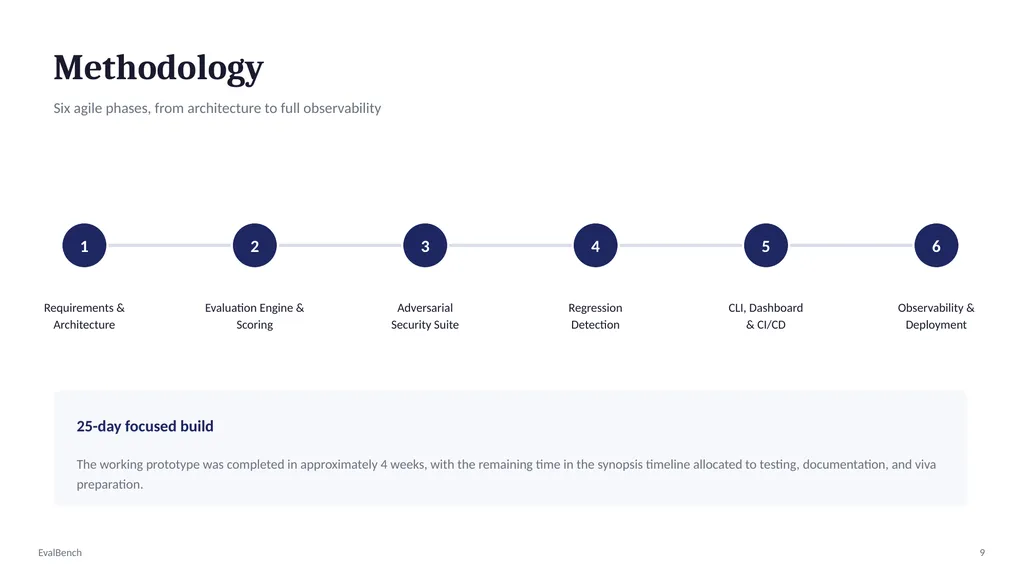
slide9. Methodology Six agile phases, from architecture to full observability 1 Requirements &
Architecture 2 Evaluation Engine &
Scoring 3 Adversarial
Security Suite 4 Regression
Detection 5 CLI, Dashboard
& CI/CD 6 Observability &
Deployment 25-day focused build The working prototype was completed in approximately 4 weeks, with the remaining time in the synopsis timeline allocated to testing, documentation, and viva preparation. EvalBench 9<br>
slide10. Thank You Questions? EvalBench — Aman Kumar Sharma · Suhanee Gupta
K.R Mangalam University<br>
Self-Hosted Large Language Models Aman Kumar Sharma (2501940041)
Suhanee Gupta (2501940025) Under the supervision of Dr. Reenu Sharma K.R Mangalam University · Department of Computer Science and Engineering<br>
slide2. The Problem Self-hosted LLMs have no standardized way to be tested 1 No reusable test suite Every prompt check starts from scratch 2 No historical baseline Regressions slip in silently between versions 3 No automated gate A degraded model can still reach production Teams ship LLM changes on faith, or maintain brittle internal scripts. EvalBench 2<br>
slide3. Where Existing Tools Fall Short 1 Local-First Most tools assume a cloud API, not a self-hosted model 2 Regression Detection No statistically grounded way to flag quality drops 3 Security Testing Adversarial testing is manual, not automated 4 Single-Strategy Scoring Exact-match OR judge — never combined 5 CI/CD Integration Evaluation rarely gates the deploy pipeline 6 Operational Visibility No metrics dashboard for evaluation health EvalBench 3<br>
slide4. The Solution EvalBench A locally-executed, pytest-style evaluation framework purpose-built
for self-hosted LLMs. Test suites authored declaratively in YAML Scored using four evaluator strategies Regressions flagged via paired t-test against a baseline Gates CI/CD pipelines automatically Never leaves the organization's infrastructure EvalBench 4<br>
slide5. System Architecture Five services, orchestrated with a single Docker Compose file Streamlit
Dashboard FastAPI
Backend MongoDB
(Storage) CLI / GitHub
Action (CI Gate) Ollama
(Local Inference) Prometheus +
Grafana Key Insight CLI and CI/CD paths bypass the dashboard entirely — enabling headless runs inside automation pipelines. EvalBench 5<br>
slide6. Key Features 4 Evaluator Strategies Exact match, substring, semantic similarity, LLM-as-judge 10 Adversarial Tests Security suite mapped to the OWASP LLM Top 10 t Regression Detection Paired t-test flags a drop >5% at p < 0.05 1 Command Deployment Full stack up with a single Docker Compose file EvalBench 6<br>
slide7. Tools & Technologies A modern, fully local MLOps stack Backend FastAPI, Python Central orchestration & REST API Database MongoDB Suites, runs, results, baselines Model Runtime Ollama Local inference — Llama, Mistral, Gemma Evaluation SciPy (paired t-test) Statistical regression detection Frontend / CLI Streamlit, Typer Dashboard + command-line runner Auth & Testing python-jose, slowapi, pytest JWT, rate limiting, >70% coverage CI/CD & Ops GitHub Actions, Docker Compose Automated gating, one-command deploy Observability Prometheus, Grafana Live metrics & dashboards EvalBench 7<br>
slide8. Objectives Achieved Measurable targets, not vague ambitions 4 evaluator
strategies >5% / p<0.05 regression
threshold 10 adversarial
security tests >70% pytest code
coverage target 5s Grafana dashboard
refresh interval 1 command
deployment EvalBench 8<br>
slide9. Methodology Six agile phases, from architecture to full observability 1 Requirements &
Architecture 2 Evaluation Engine &
Scoring 3 Adversarial
Security Suite 4 Regression
Detection 5 CLI, Dashboard
& CI/CD 6 Observability &
Deployment 25-day focused build The working prototype was completed in approximately 4 weeks, with the remaining time in the synopsis timeline allocated to testing, documentation, and viva preparation. EvalBench 9<br>
slide10. Thank You Questions? EvalBench — Aman Kumar Sharma · Suhanee Gupta
K.R Mangalam University<br>