
Mathematical Fundamentals: Linear Algebra Jothi
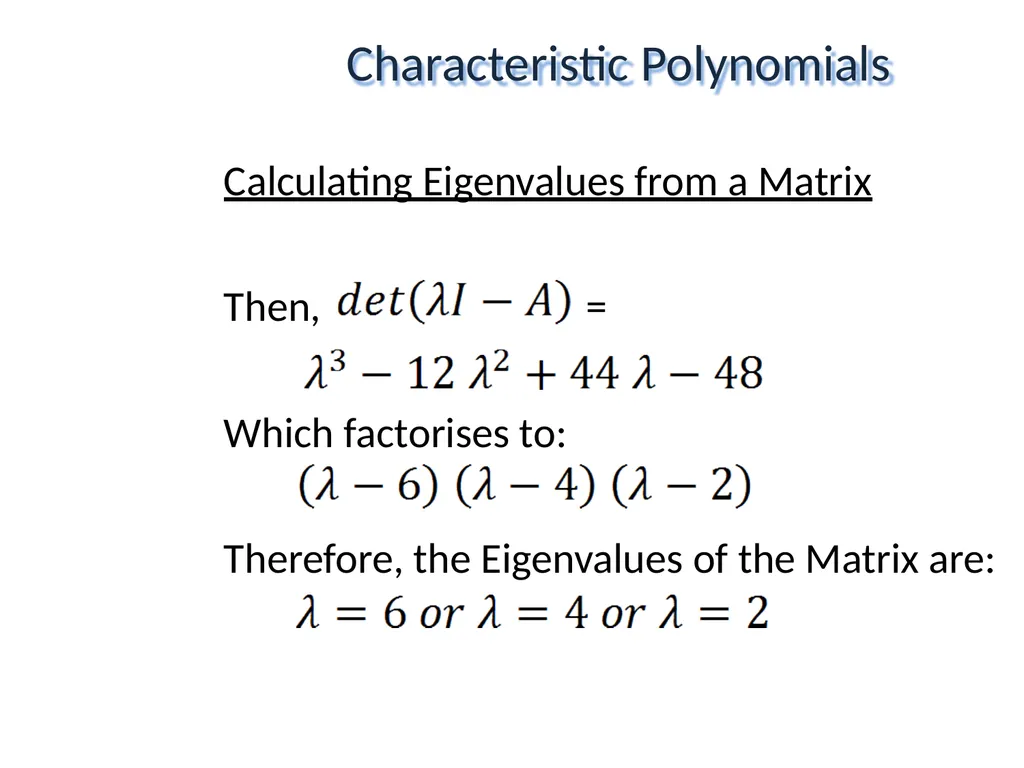
Description: Mathematical Fundamentals: Linear Algebra Jothi Ramalingam jothiramnitk.edu.in Introduction: Diagonal Matrices Before beginning this topic, we must first clarify the definition of a Diagonal Matrix. A Diagonal Matrix is an n by n Matrix
Related Topics
Download Presentation
"Mathematical Fundamentals: Linear Algebra Jothi" is the property of its rightful owner. Permission is granted to download and print the materials on this website for personal, non-commercial use only, and to display it on your personal computer provided you do not modify the materials and that you retain all copyright notices contained in the materials. By downloading content from our website, you accept the terms of this agreement.
Presentation Transcript
slide1. Mathematical Fundamentals: Linear Algebra Jothi Ramalingam
jothiram@nitk.edu.in<br>
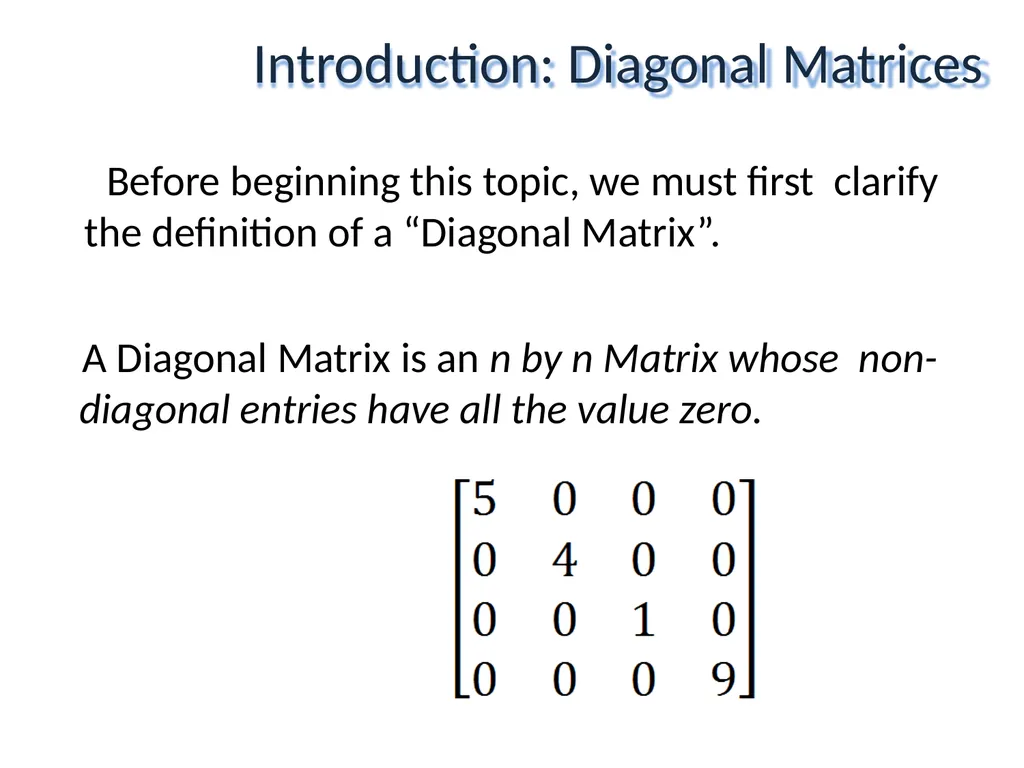
slide2. Introduction: Diagonal Matrices Before beginning this topic, we must first clarify the definition of a “Diagonal Matrix”.
A Diagonal Matrix is an n by n Matrix whose non-diagonal entries have all the value zero.<br>
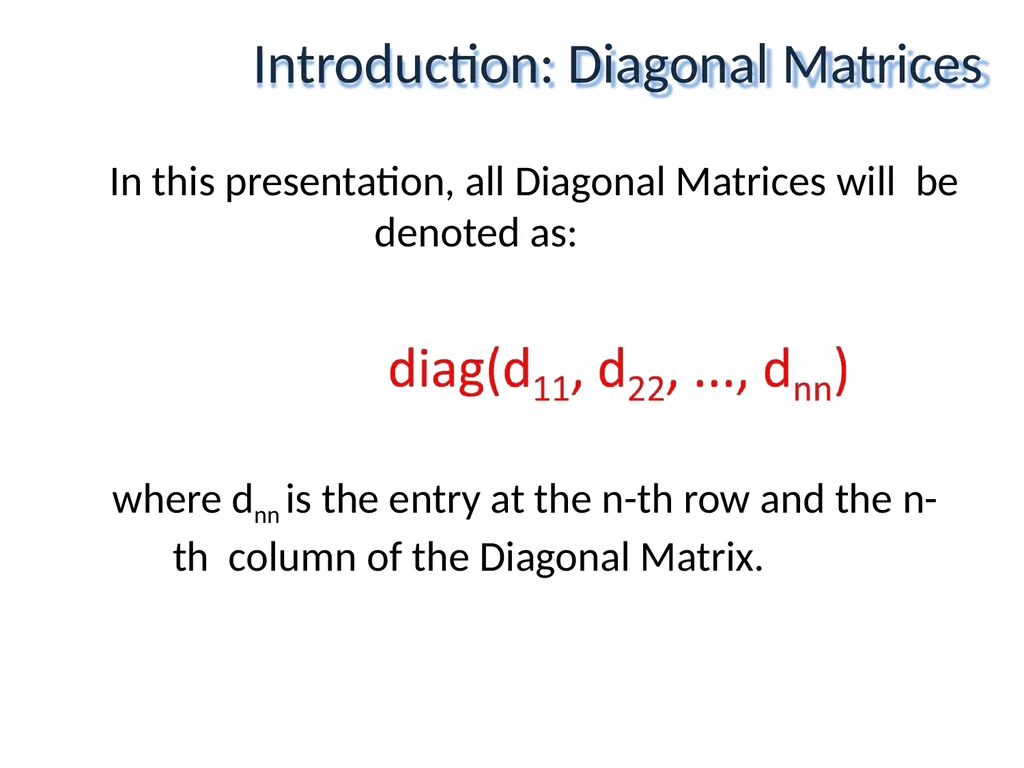
slide3. Introduction: Diagonal Matrices In this presentation, all Diagonal Matrices will be denoted as: where dnn is the entry at the n-th row and the n-th column of the Diagonal Matrix.<br>
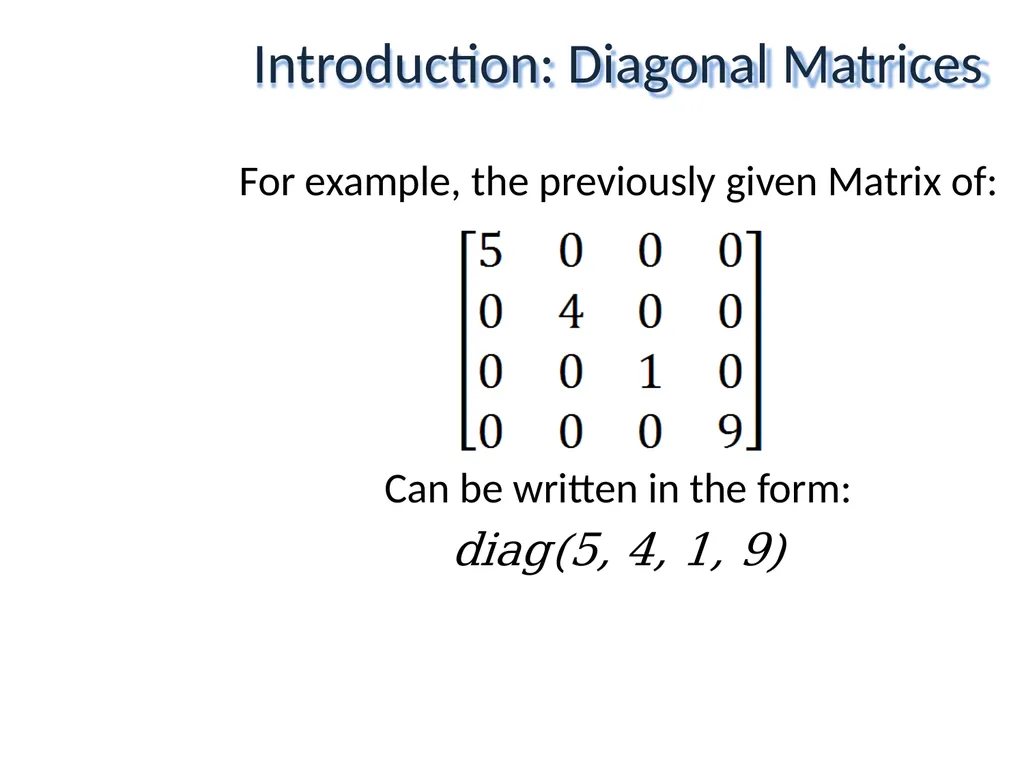
slide4. Introduction: Diagonal Matrices For example, the previously given Matrix of: Can be written in the form:
diag(5, 4, 1, 9)<br>
slide5. Introduction: Diagonal Matrices The Effects of a Diagonal Matrix
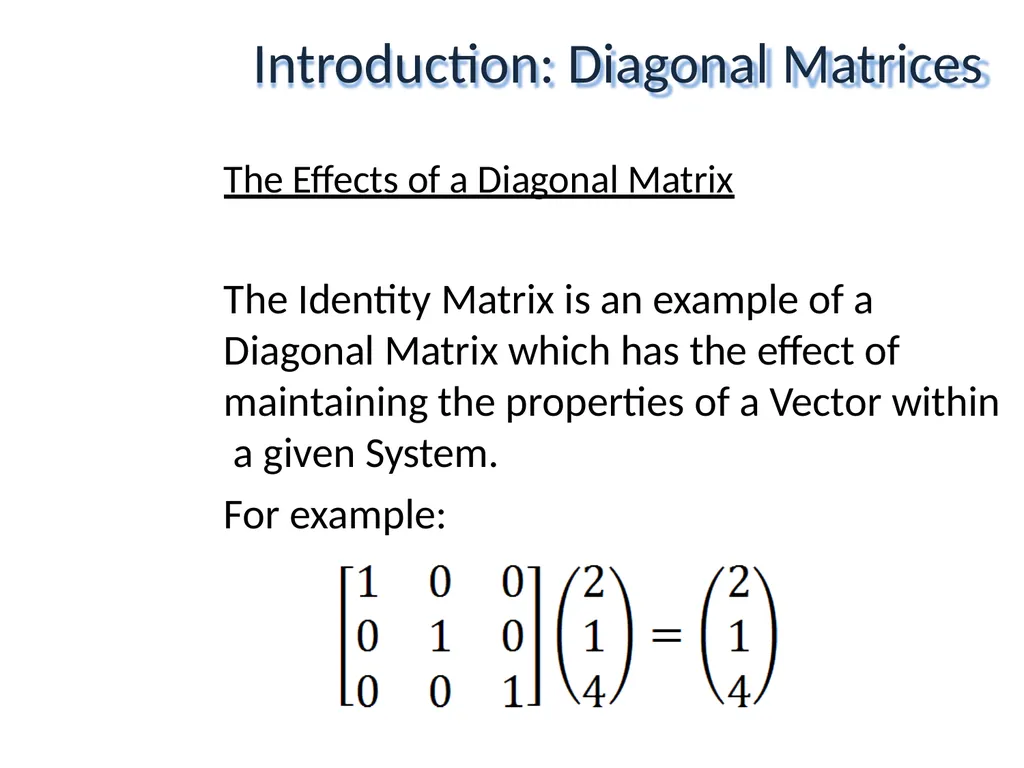
The Identity Matrix is an example of a Diagonal Matrix which has the effect of maintaining the properties of a Vector within a given System.
For example:<br>
slide6. Introduction: Diagonal Matrices The Effects of a Diagonal Matrix
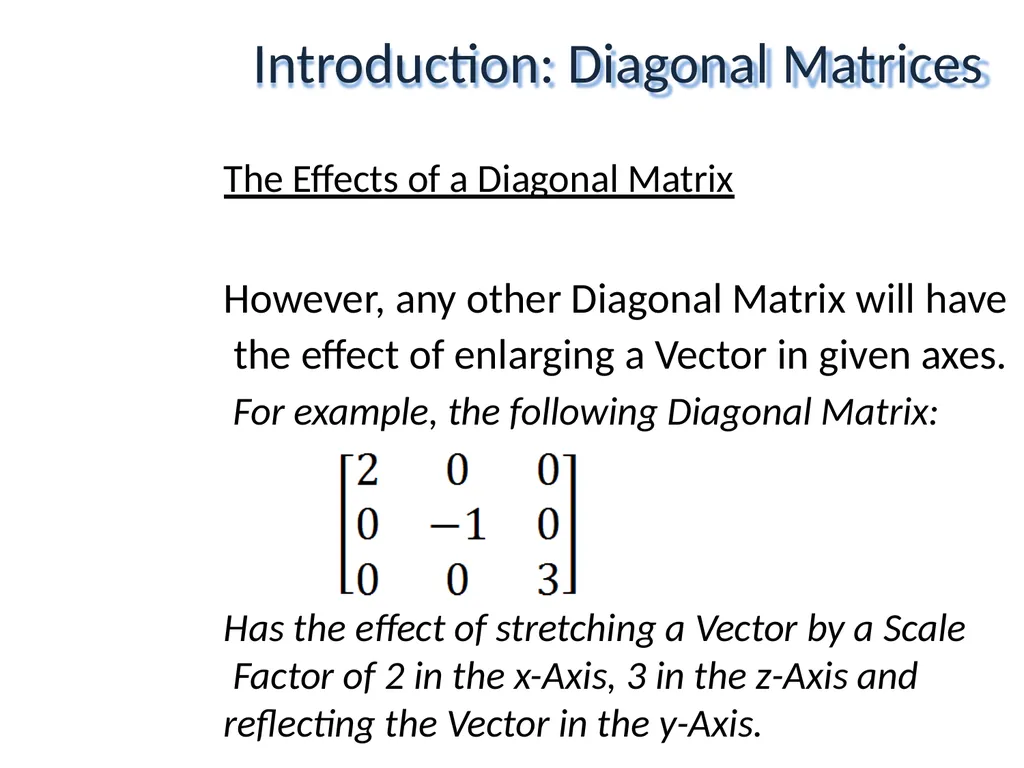
However, any other Diagonal Matrix will have the effect of enlarging a Vector in given axes. For example, the following Diagonal Matrix: Has the effect of stretching a Vector by a Scale Factor of 2 in the x-Axis, 3 in the z-Axis and reflecting the Vector in the y-Axis.<br>
slide7. The Goal By the end of this PowerPoint, we should be able to understand and apply the idea of Diagonalisation, using Eigenvalues and Eigenvectors.<br>
slide8. The Matrix Point of View
By the end, we should be able to understand how, given an n by n Matrix, A, we can say that A is Diagonalisable if and only if there is a Matrix, δ, that allows the following Matrix to be Diagonal:
And why this knowledge is significant. The Goal<br>
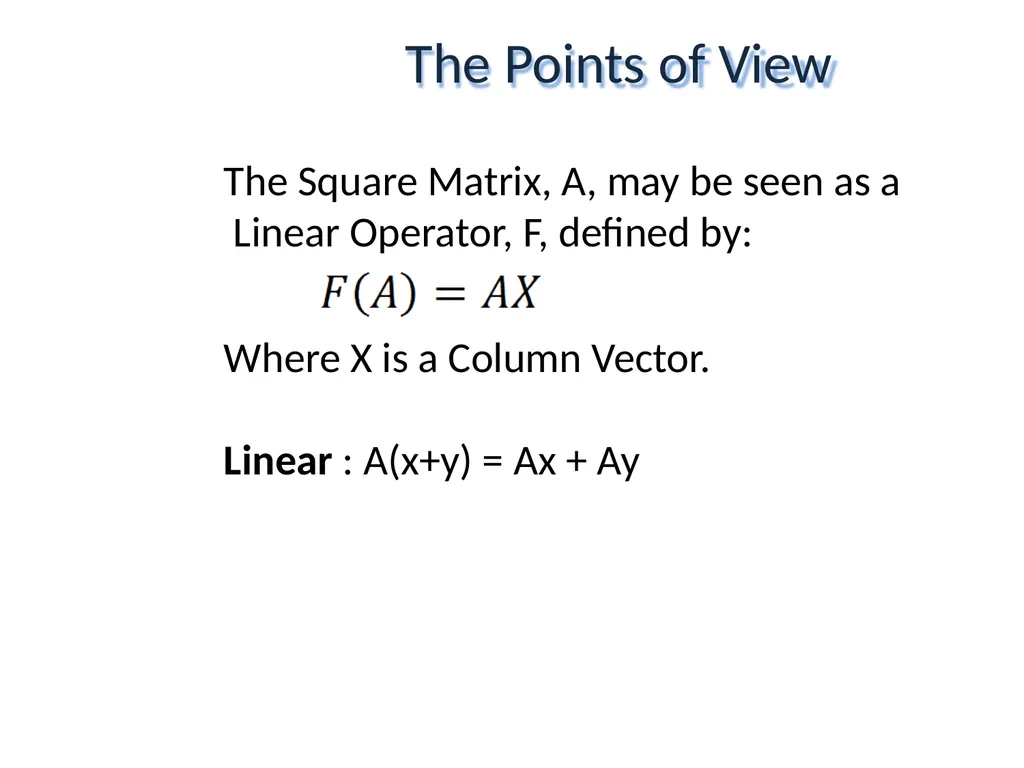
slide9. The Square Matrix, A, may be seen as a Linear Operator, F, defined by:
Where X is a Column Vector.
Linear : A(x+y) = Ax + Ay The Points of View<br>
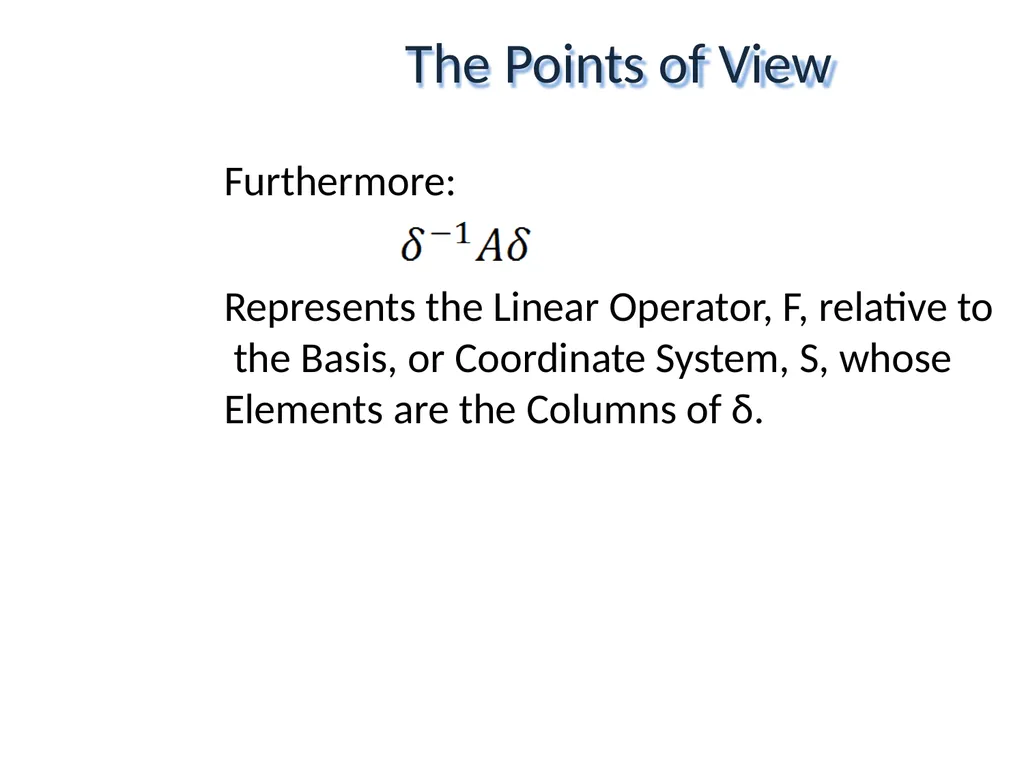
slide10. Furthermore:
Represents the Linear Operator, F, relative to the Basis, or Coordinate System, S, whose Elements are the Columns of δ. The Points of View<br>
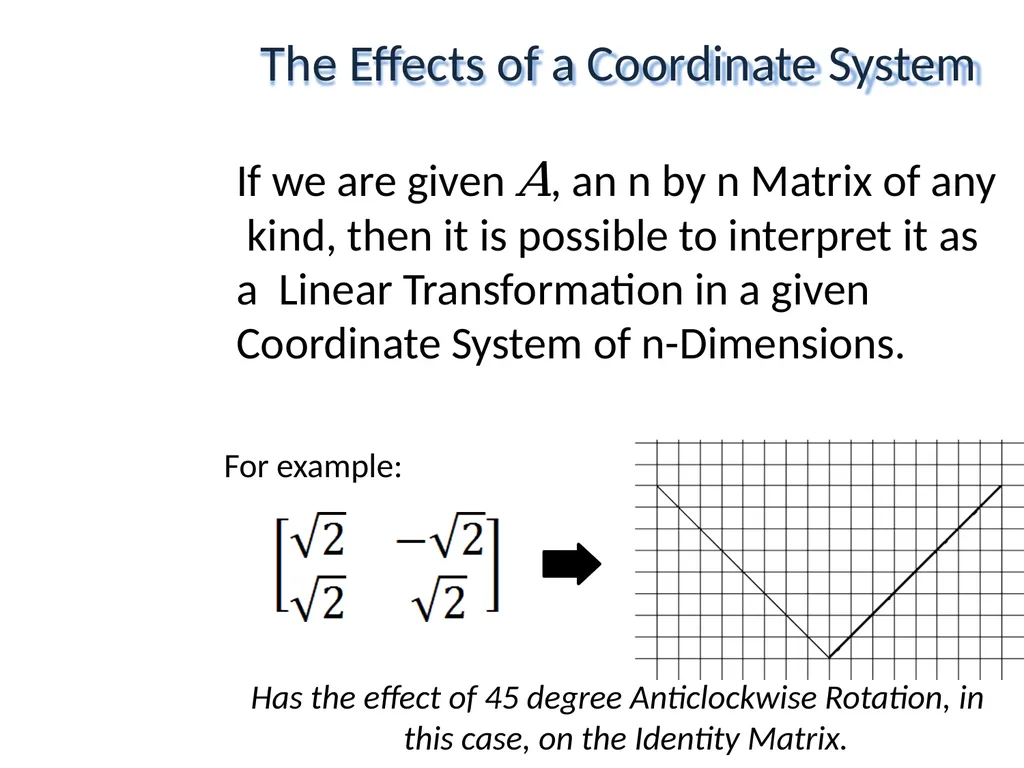
slide11. If we are given A, an n by n Matrix of any kind, then it is possible to interpret it as a Linear Transformation in a given Coordinate System of n-Dimensions.
For example: Has the effect of 45 degree Anticlockwise Rotation, in this case, on the Identity Matrix. The Effects of a Coordinate System<br>
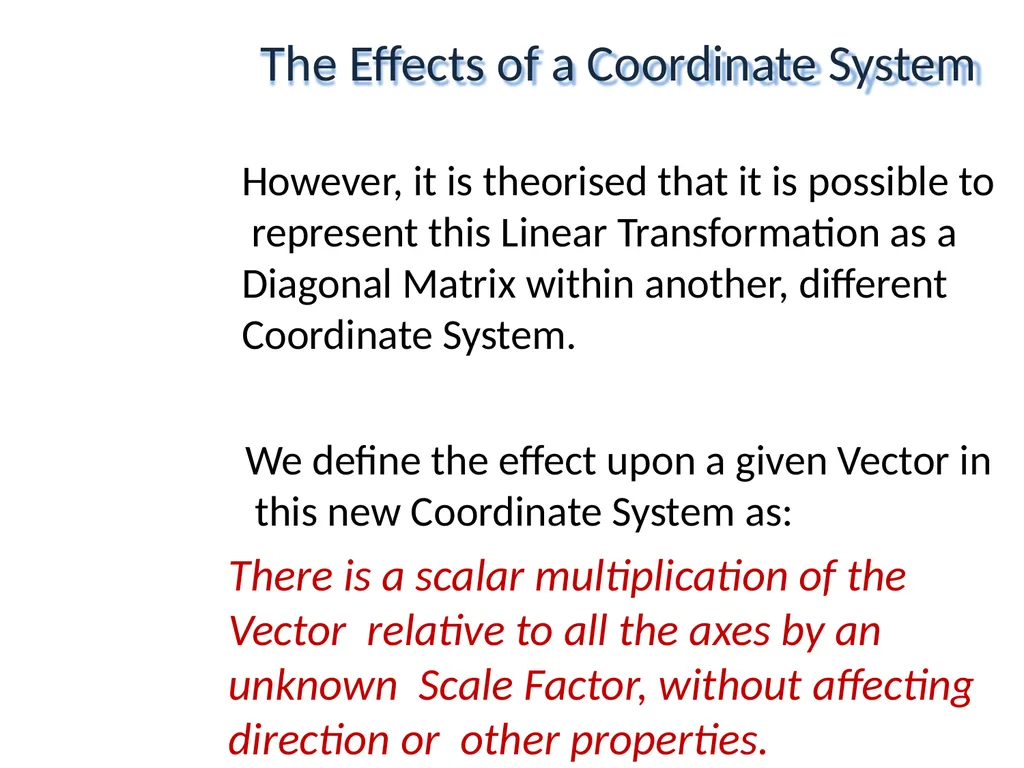
slide12. However, it is theorised that it is possible to represent this Linear Transformation as a Diagonal Matrix within another, different Coordinate System.
We define the effect upon a given Vector in this new Coordinate System as:
There is a scalar multiplication of the Vector relative to all the axes by an unknown Scale Factor, without affecting direction or other properties. The Effects of a Coordinate System<br>
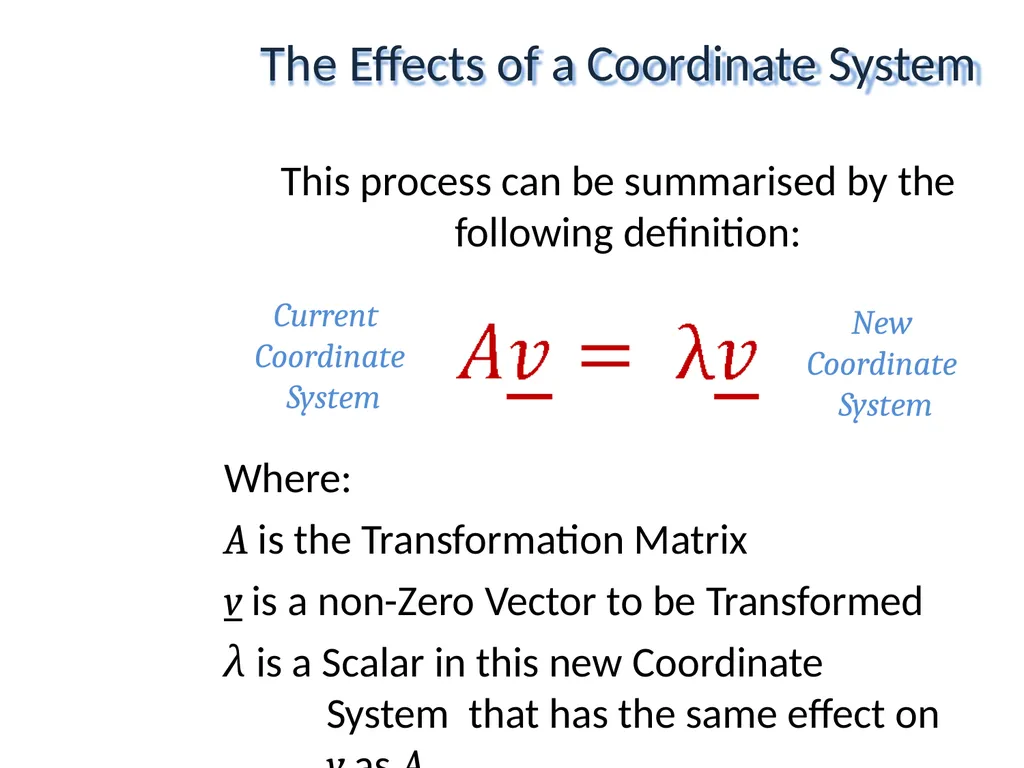
slide13. This process can be summarised by the following definition: Where:
A is the Transformation Matrix
v is a non-Zero Vector to be Transformed
λ is a Scalar in this new Coordinate System that has the same effect on v as A. The Effects of a Coordinate System Current Coordinate System New Coordinate System<br>
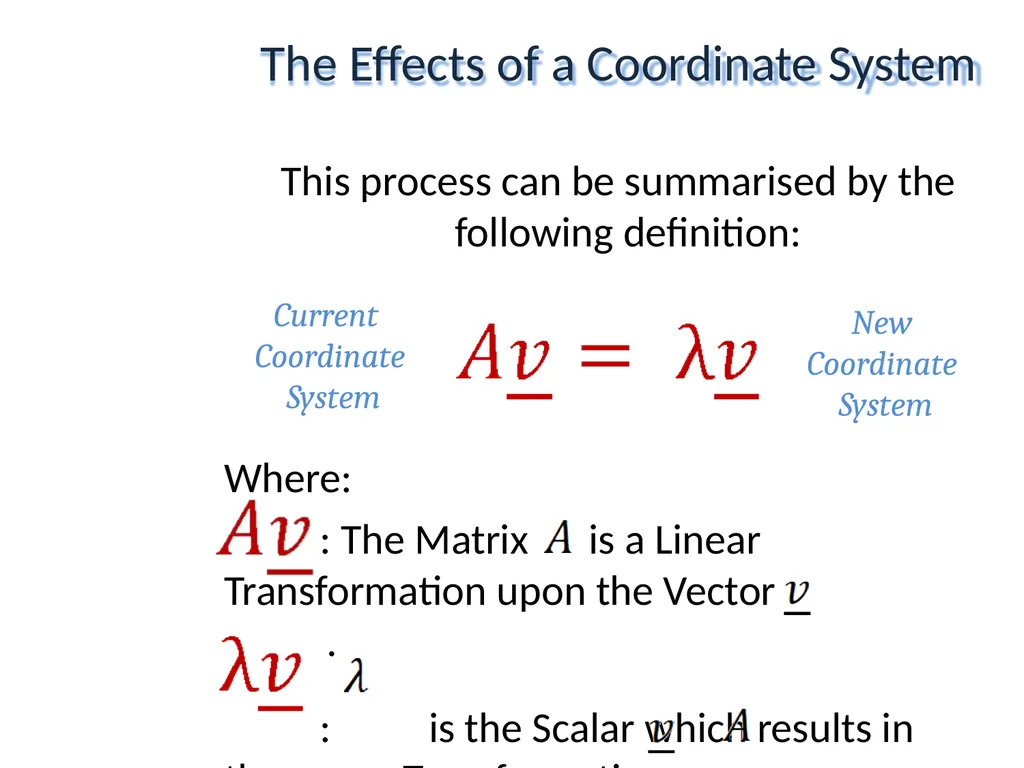
slide14. This process can be summarised by the following definition: Where:
: The Matrix is a Linear Transformation upon the Vector .
: is the Scalar which results in the same Transformation on as . The Effects of a Coordinate System Current Coordinate System New Coordinate System<br>
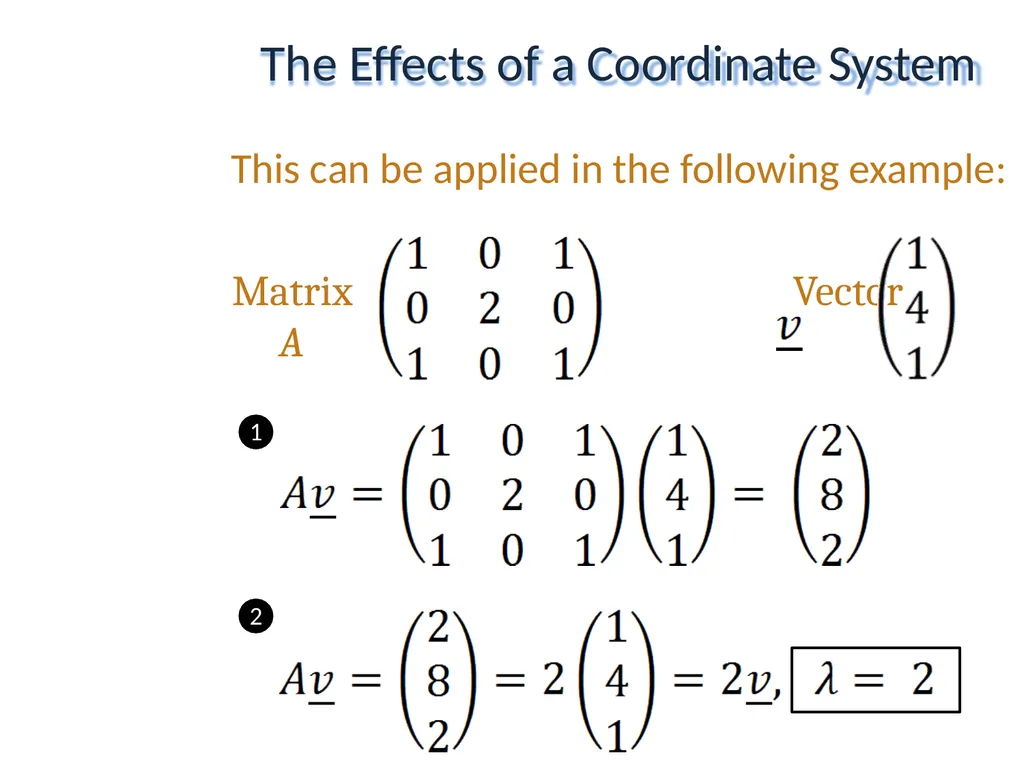
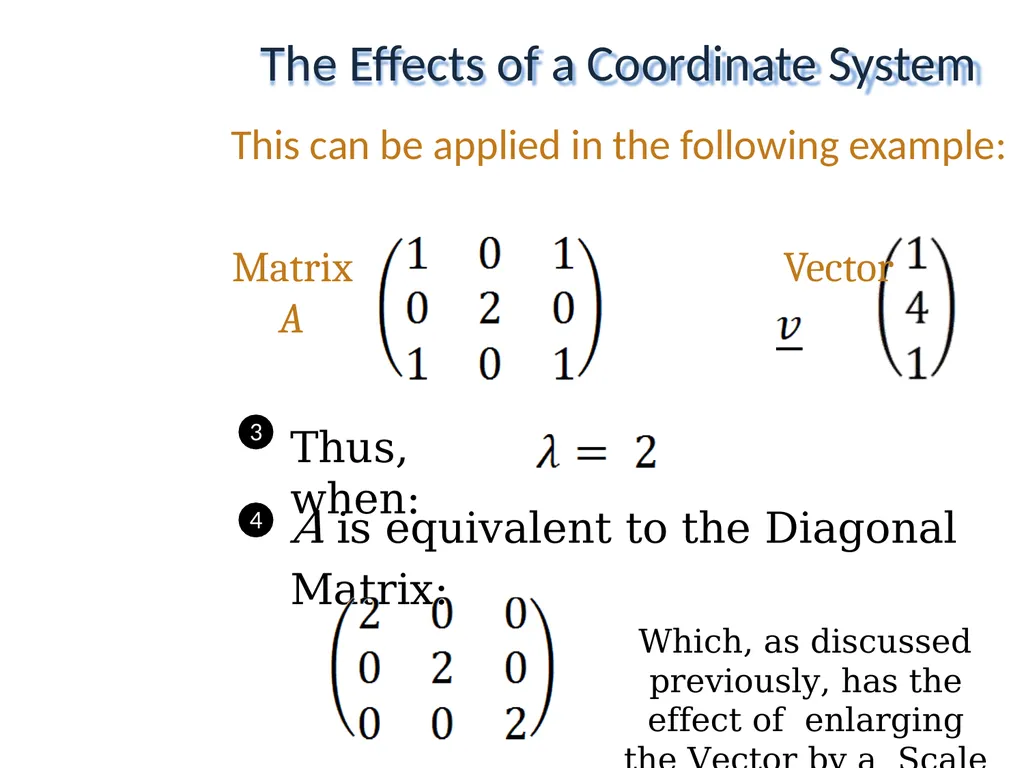
slide15. The Effects of a Coordinate System 1 2 This can be applied in the following example:
Matrix Vector
A<br>
slide16. The Effects of a Coordinate System This can be applied in the following example:
Matrix Vector
A 3 4 Thus, when: A is equivalent to the Diagonal Matrix:
Which, as discussed
previously, has the effect of enlarging the Vector by a Scale Factor of 2 in each Dimension.<br>
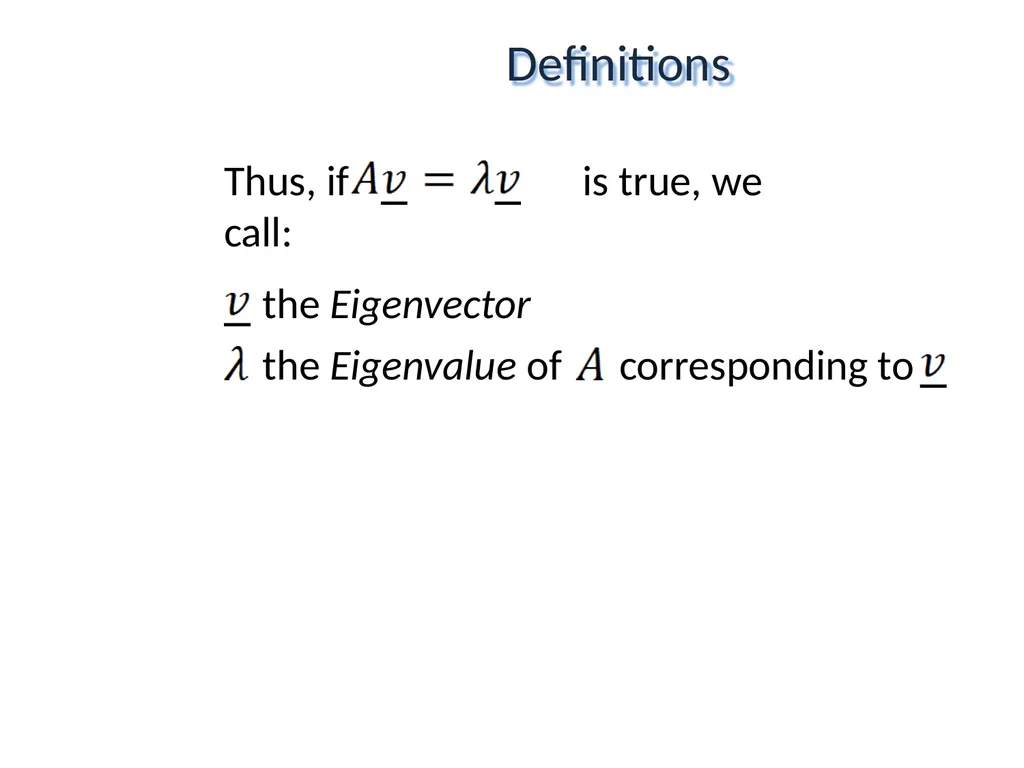
slide17. Thus, if is true, we call: the Eigenvector
the Eigenvalue of corresponding to Definitions<br>
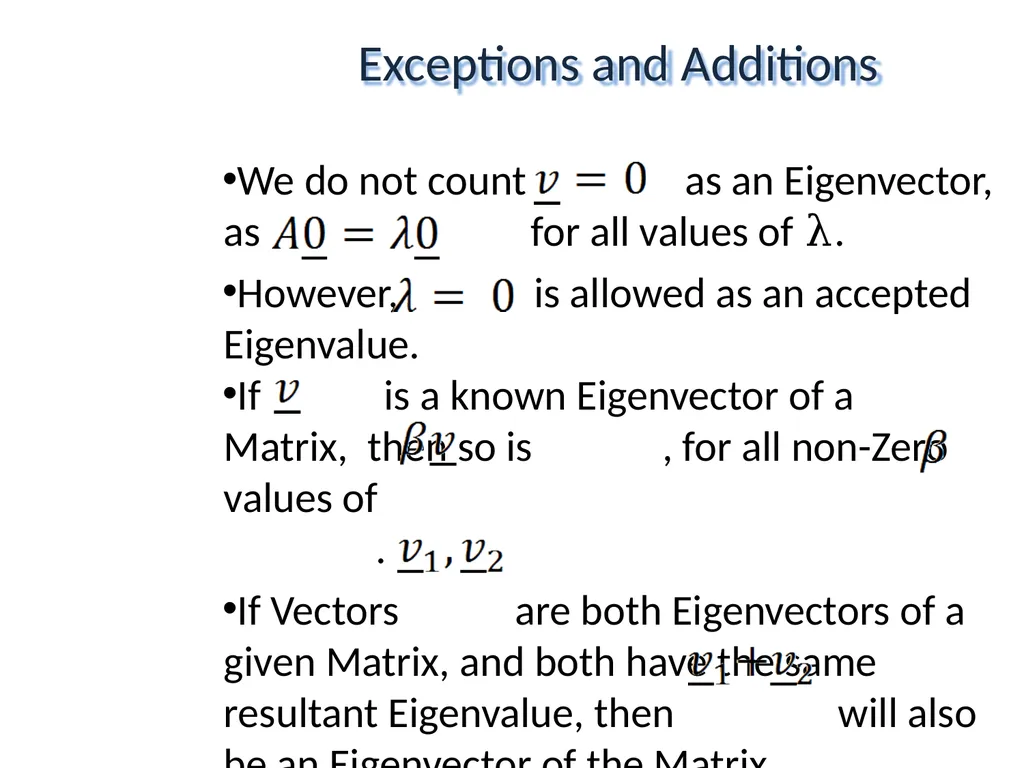
slide18. We do not count as an Eigenvector, as for all values of λ.
However, is allowed as an accepted Eigenvalue.
If is a known Eigenvector of a Matrix, then so is , for all non-Zero values of
.
If Vectors are both Eigenvectors of a given Matrix, and both have the same resultant Eigenvalue, then will also be an Eigenvector of the Matrix. Exceptions and Additions<br>
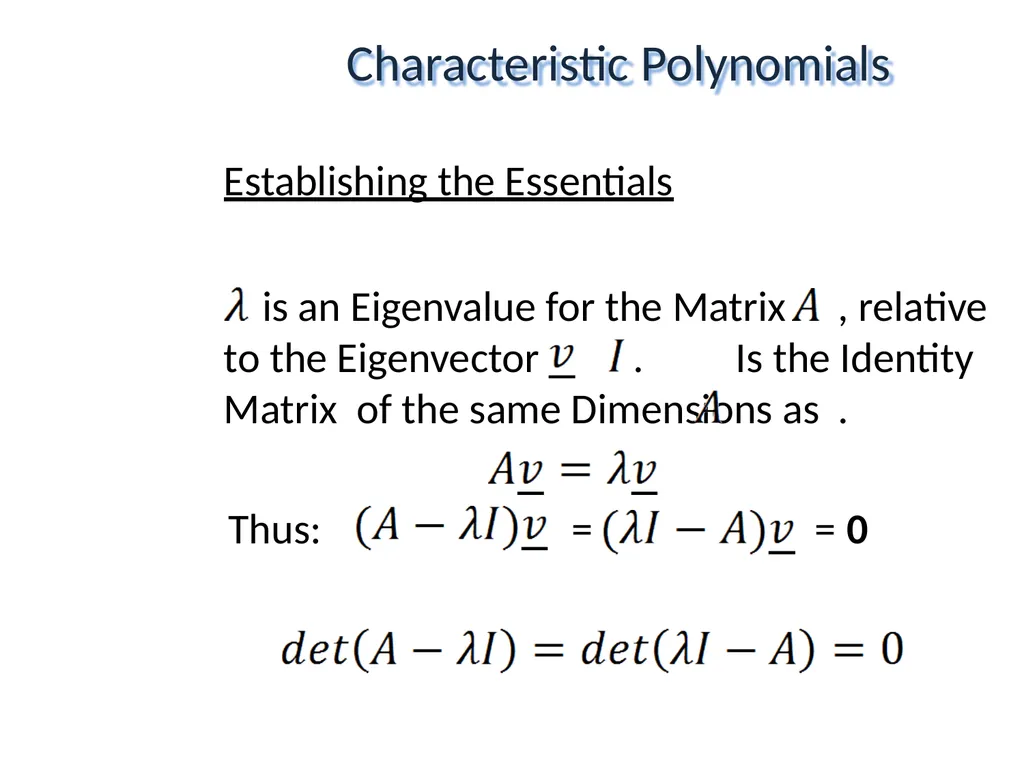
slide19. Establishing the Essentials
is an Eigenvalue for the Matrix , relative to the Eigenvector . Is the Identity Matrix of the same Dimensions as . Thus: = = 0 Characteristic Polynomials<br>
slide20. Application of the Knowledge
What this, essentially, leads to is the finding of all Eigenvalues and Eigenvectors of a specific Matrix.
This is done by considering the Matrix, , in addition to the Identity Matrix, .
We then multiply the Identity Matrix by the unknown quantity, . Characteristic Polynomials<br>
slide21. Application of the Knowledge
Proceeding this, we then take the lots of the Identity Matrix, and subtract the Matrix from it.
We then take the Determinant of the result which ends up as a Polynomial equation, in order to find possible values of , the Eigenvalues.
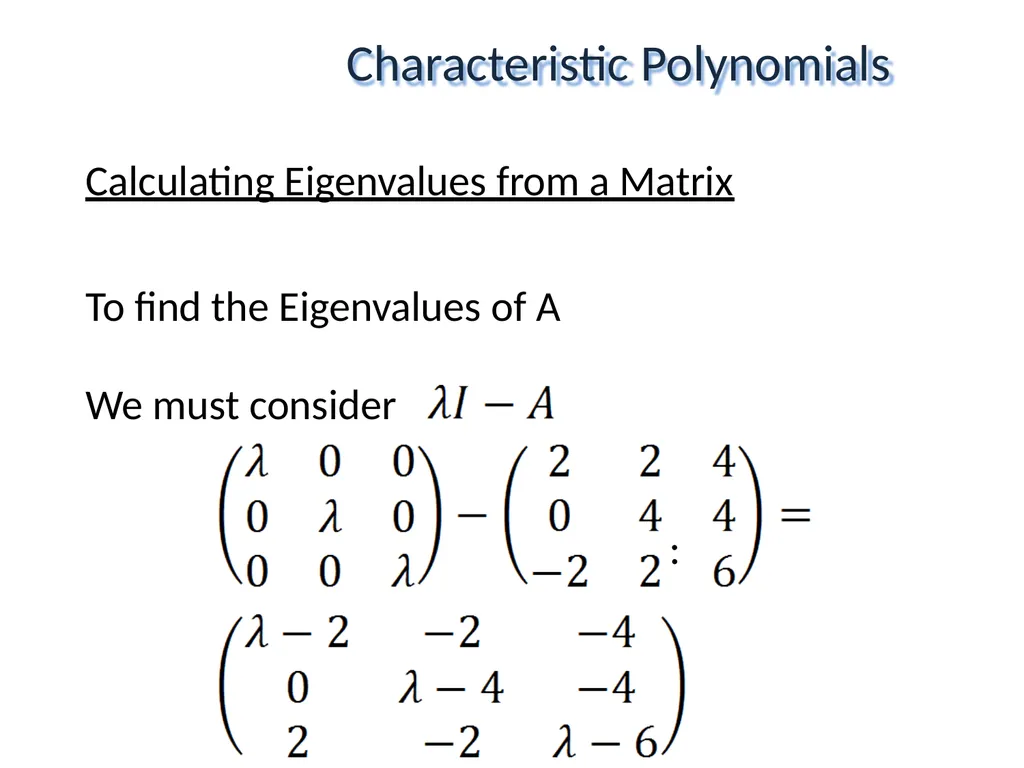
This can be exemplified by the following example: Characteristic Polynomials<br>
slide22. Calculating Eigenvalues from a Matrix
To find the Eigenvalues of A We must consider : Characteristic Polynomials<br>
slide23. Calculating Eigenvalues from a Matrix
Then, =
Which factorises to:
Therefore, the Eigenvalues of the Matrix are: Characteristic Polynomials<br>
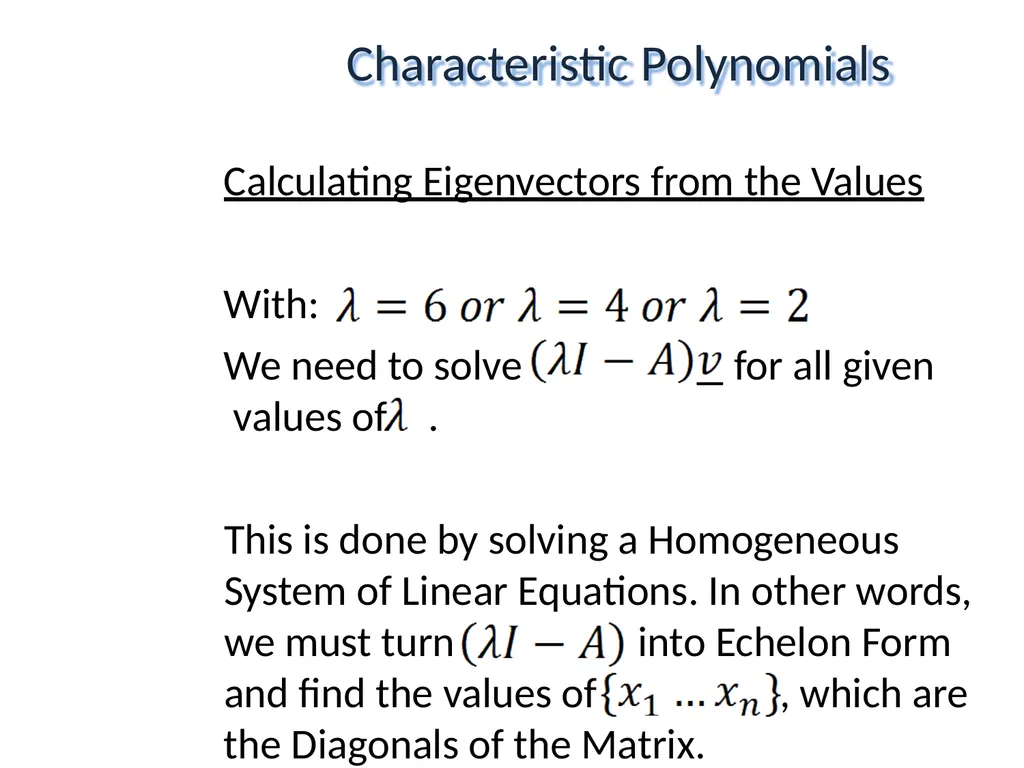
slide24. Calculating Eigenvectors from the Values for all given With:
We need to solve values of . This is done by solving a Homogeneous System of Linear Equations. In other words, we must turn
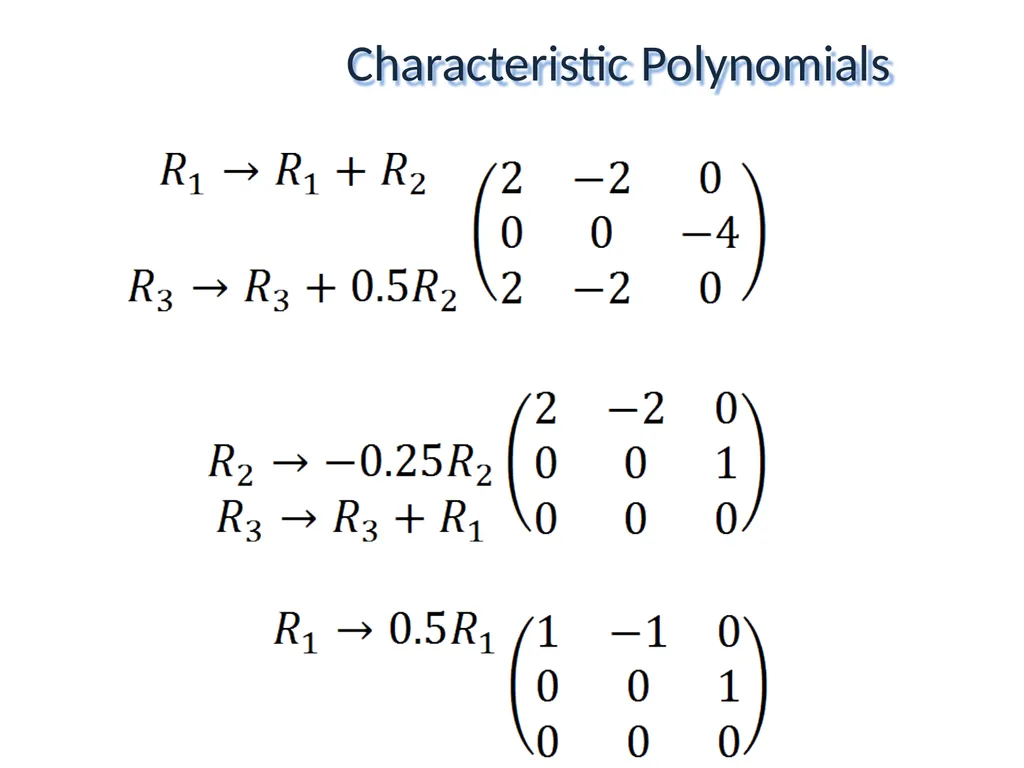
and find the values of into Echelon Form
, which are the Diagonals of the Matrix. Characteristic Polynomials<br>
slide25. Calculating Eigenvectors from the Values
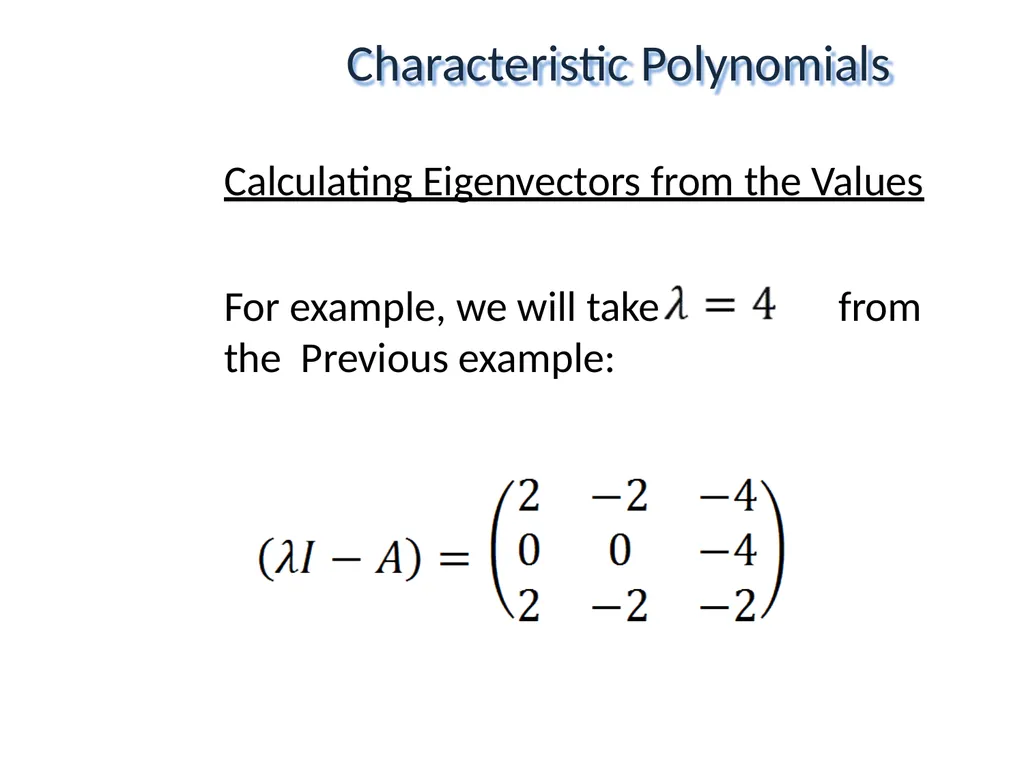
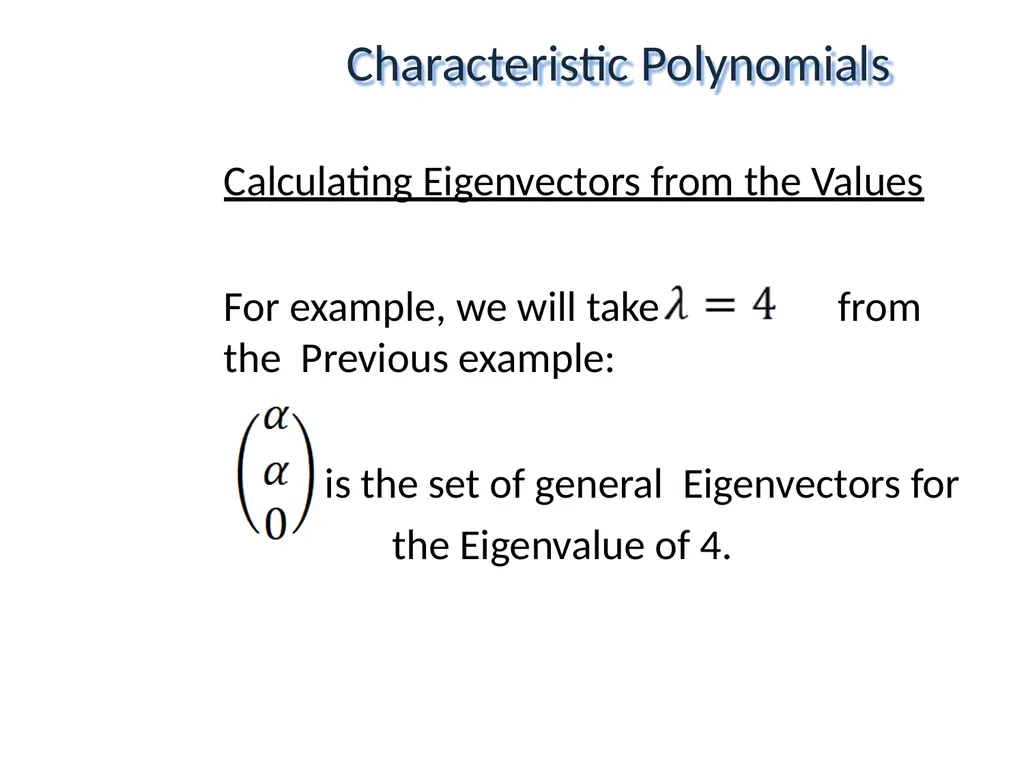
For example, we will take from the Previous example: Characteristic Polynomials<br>
slide26. Characteristic Polynomials<br>
slide27. Calculating Eigenvectors from the Values
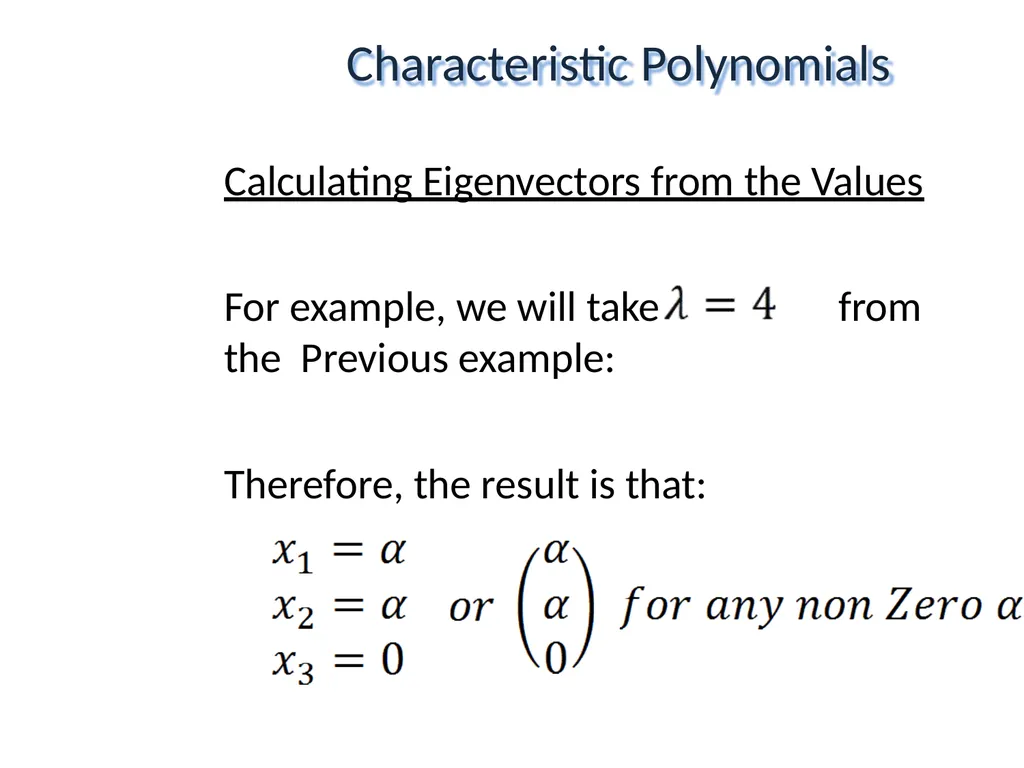
For example, we will take from the Previous example:
Therefore, the result is that: Characteristic Polynomials<br>
slide28. Calculating Eigenvectors from the Values
For example, we will take from the Previous example:
is the set of general Eigenvectors for the Eigenvalue of 4. Characteristic Polynomials<br>
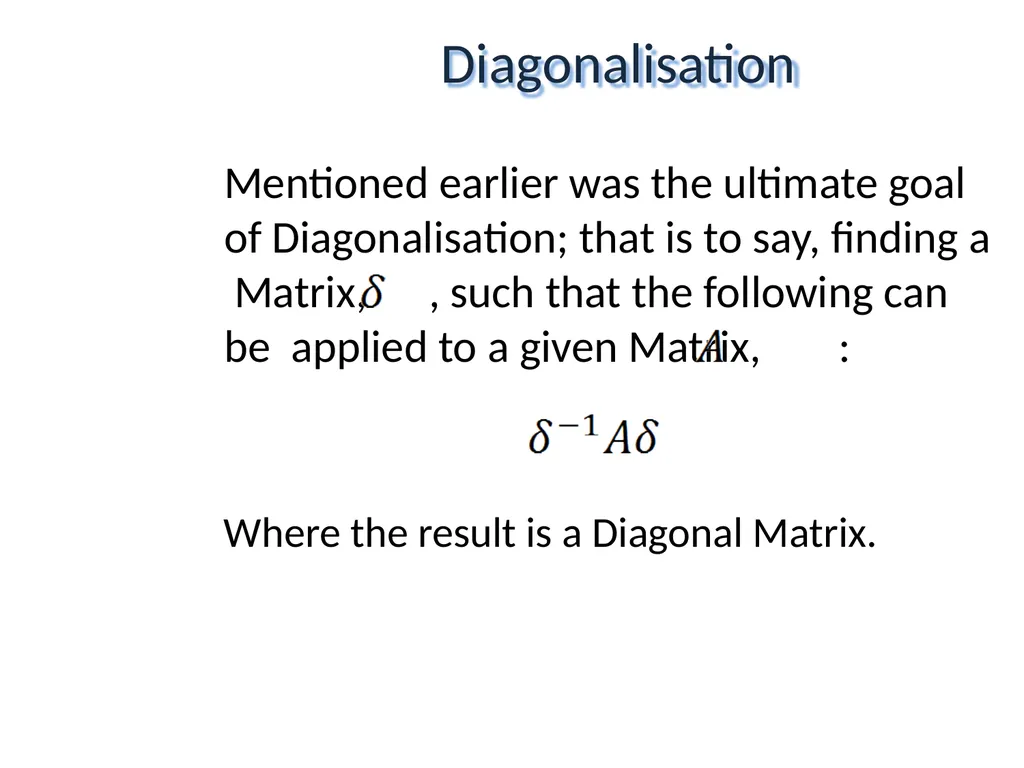
slide29. Mentioned earlier was the ultimate goal of Diagonalisation; that is to say, finding a Matrix, , such that the following can be applied to a given Matrix, : Where the result is a Diagonal Matrix. Diagonalisation<br>
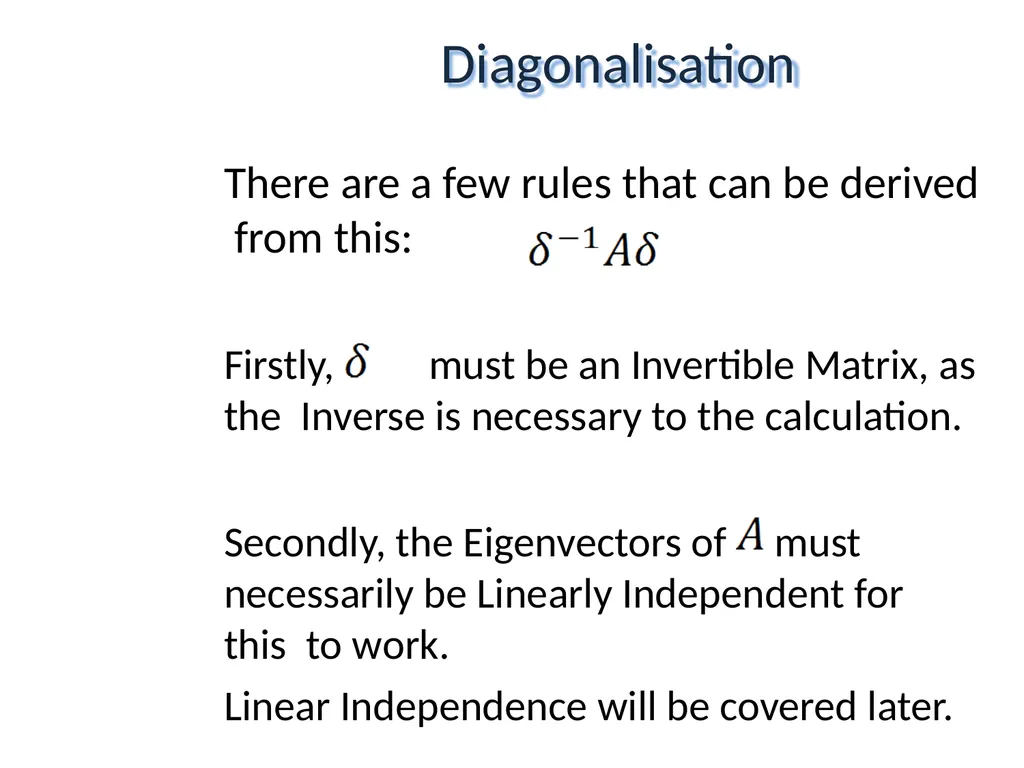
slide30. There are a few rules that can be derived from this:
Firstly, must be an Invertible Matrix, as the Inverse is necessary to the calculation.
Secondly, the Eigenvectors of must necessarily be Linearly Independent for this to work.
Linear Independence will be covered later. Diagonalisation<br>
slide31. Eigenvectors, Eigenvalues & Diagonalisation
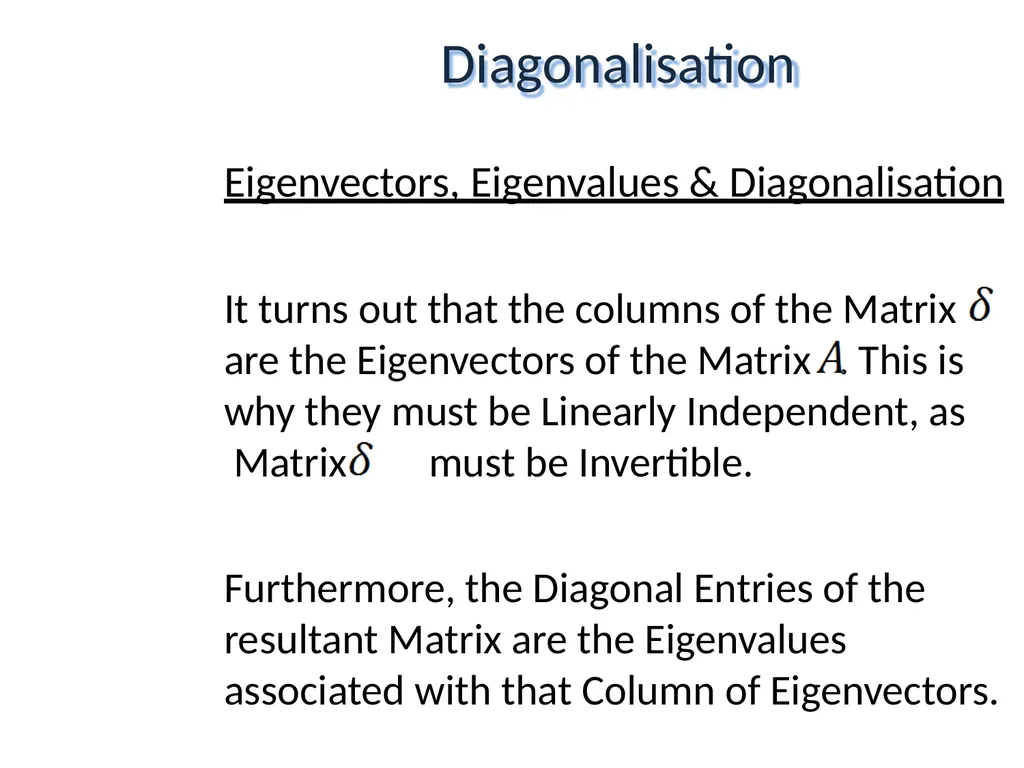
It turns out that the columns of the Matrix are the Eigenvectors of the Matrix . This is why they must be Linearly Independent, as Matrix must be Invertible.
Furthermore, the Diagonal Entries of the resultant Matrix are the Eigenvalues associated with that Column of Eigenvectors. Diagonalisation<br>
slide32. Eigenvectors, Eigenvalues & Diagonalisation
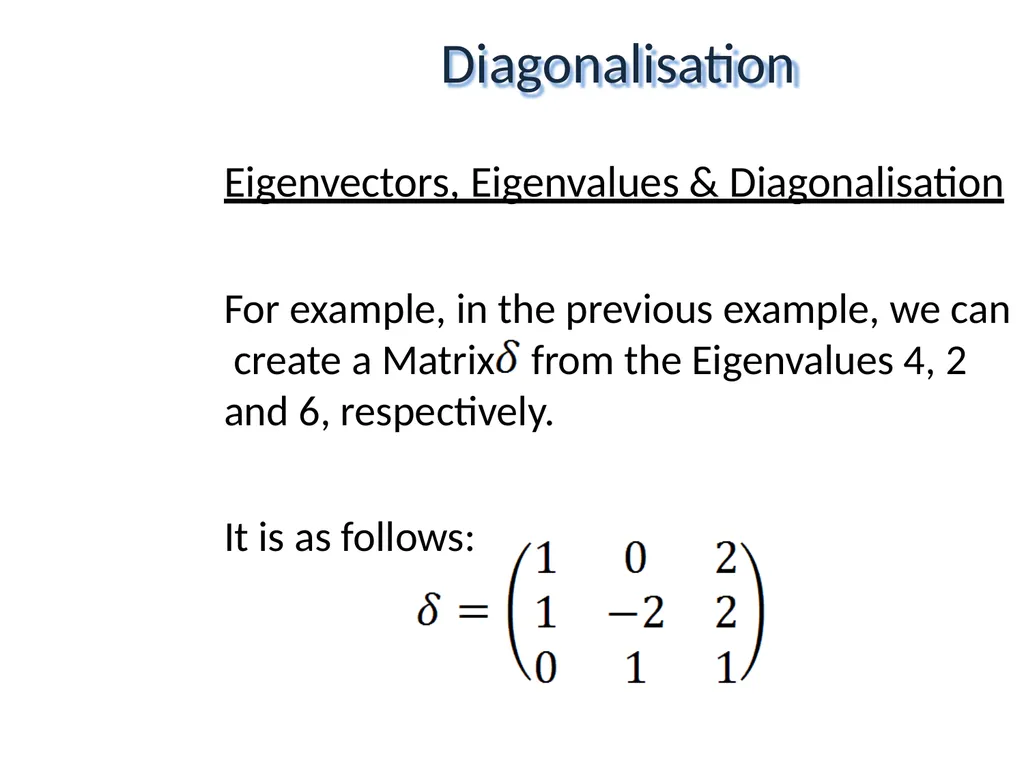
For example, in the previous example, we can create a Matrix from the Eigenvalues 4, 2 and 6, respectively.
It is as follows: Diagonalisation<br>
slide33. Eigenvectors, Eigenvalues & Diagonalisation
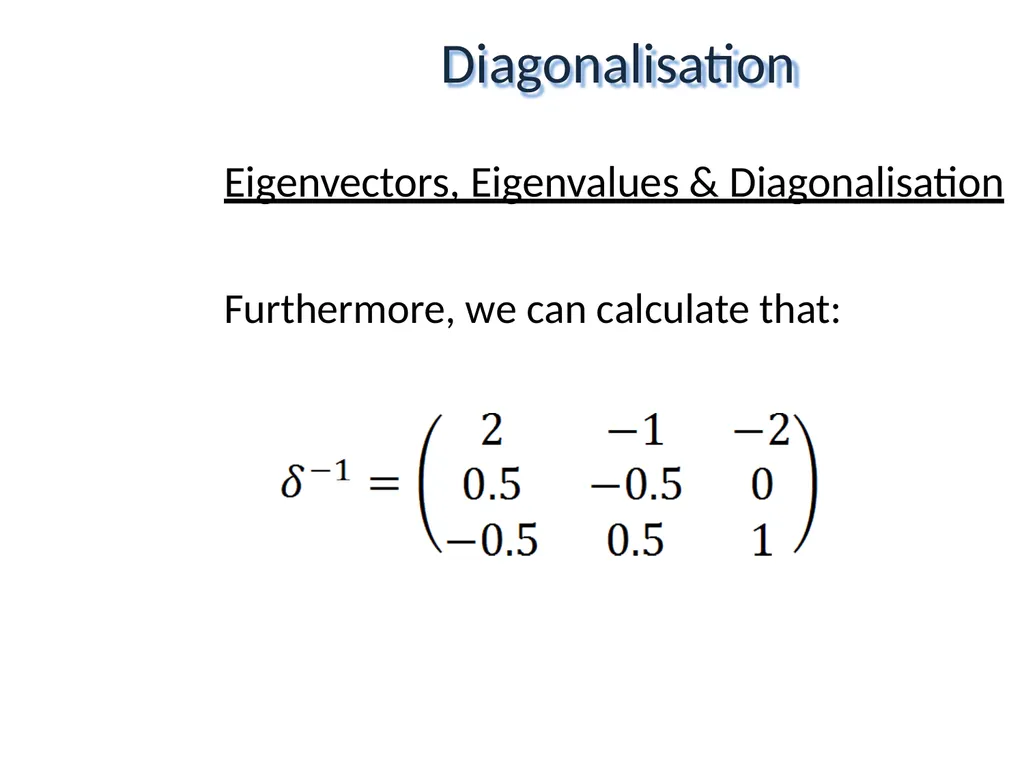
Furthermore, we can calculate that: Diagonalisation<br>
slide34. Eigenvectors, Eigenvalues & Diagonalisation
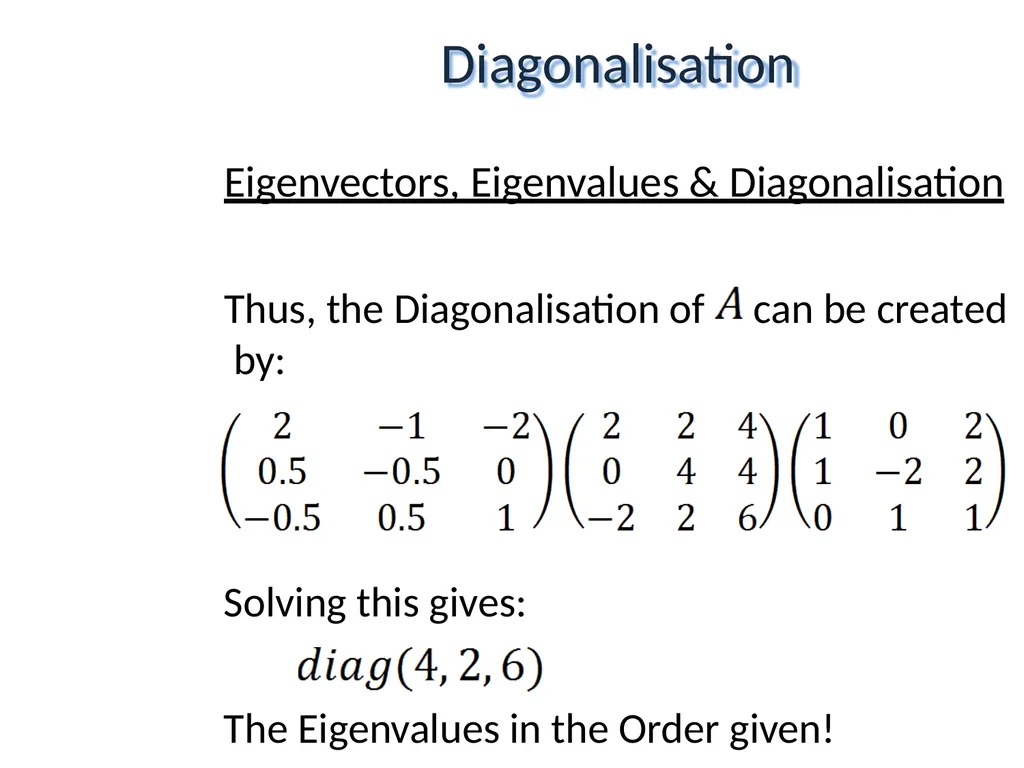
Thus, the Diagonalisation of can be created by: Solving this gives:
The Eigenvalues in the Order given! Diagonalisation<br>
slide35. Eigenvectors, Eigenvalues & Diagonalisation
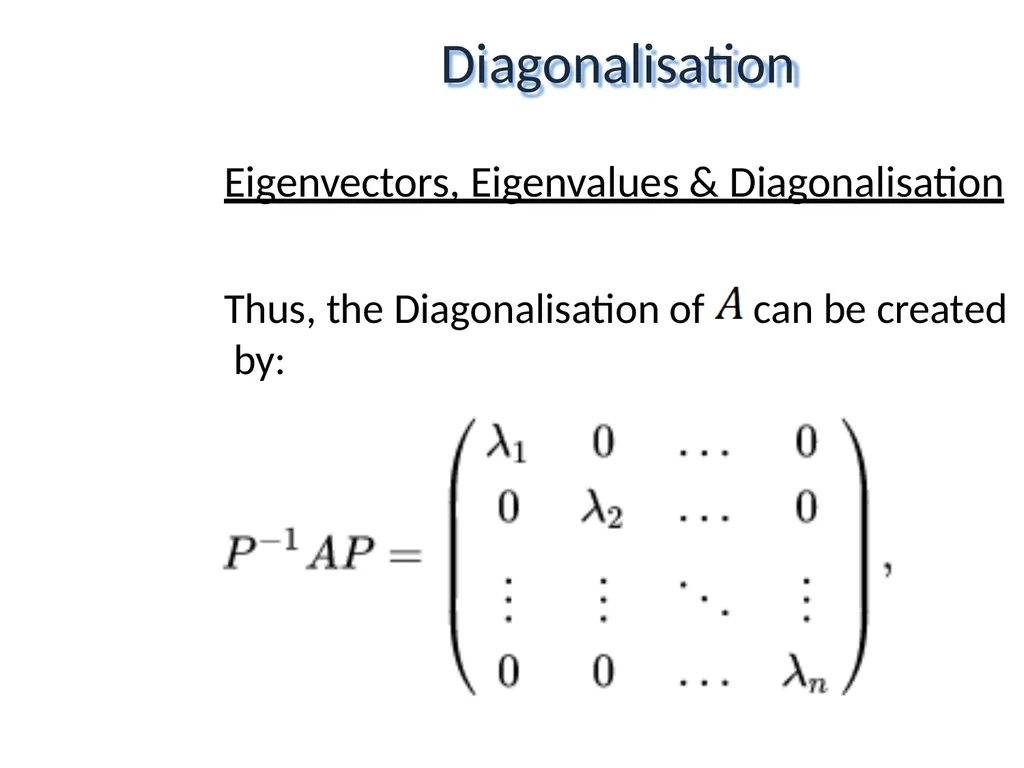
Thus, the Diagonalisation of can be created by: Diagonalisation<br>
slide36. Introduction
This will be a brief section on Linear Independence to enforce that the Eigenvectors of must be Linearly Independent for Diagonalisation to be implemented. Linear Independence<br>
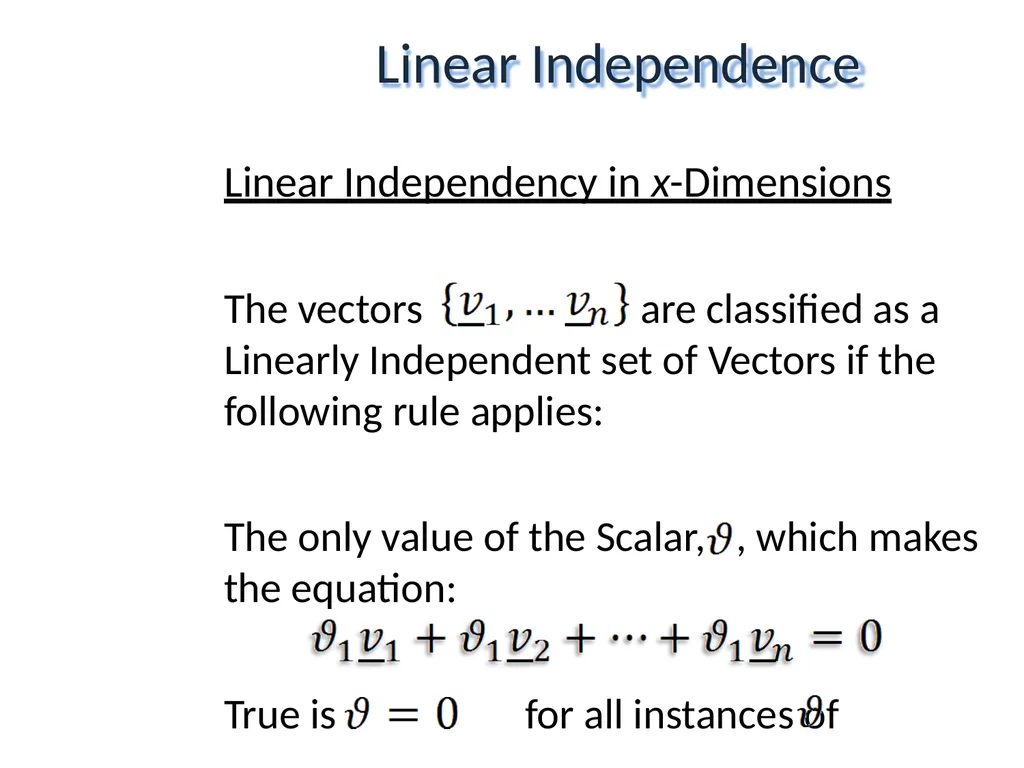
slide37. Linear Independency in x-Dimensions
The vectors are classified as a Linearly Independent set of Vectors if the following rule applies:
The only value of the Scalar, , which makes the equation:
True is for all instances of Linear Independence<br>
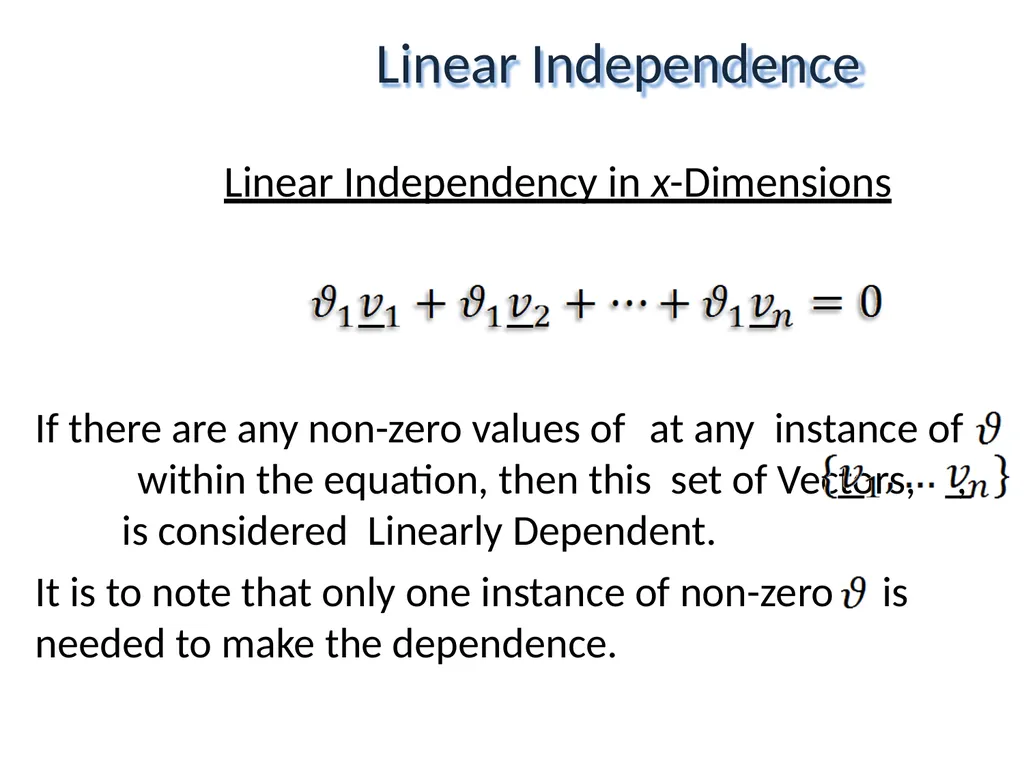
slide38. Linear Independency in x-Dimensions If there are any non-zero values of at any instance of within the equation, then this set of Vectors, , is considered Linearly Dependent.
It is to note that only one instance of non-zero is needed to make the dependence. Linear Independence<br>
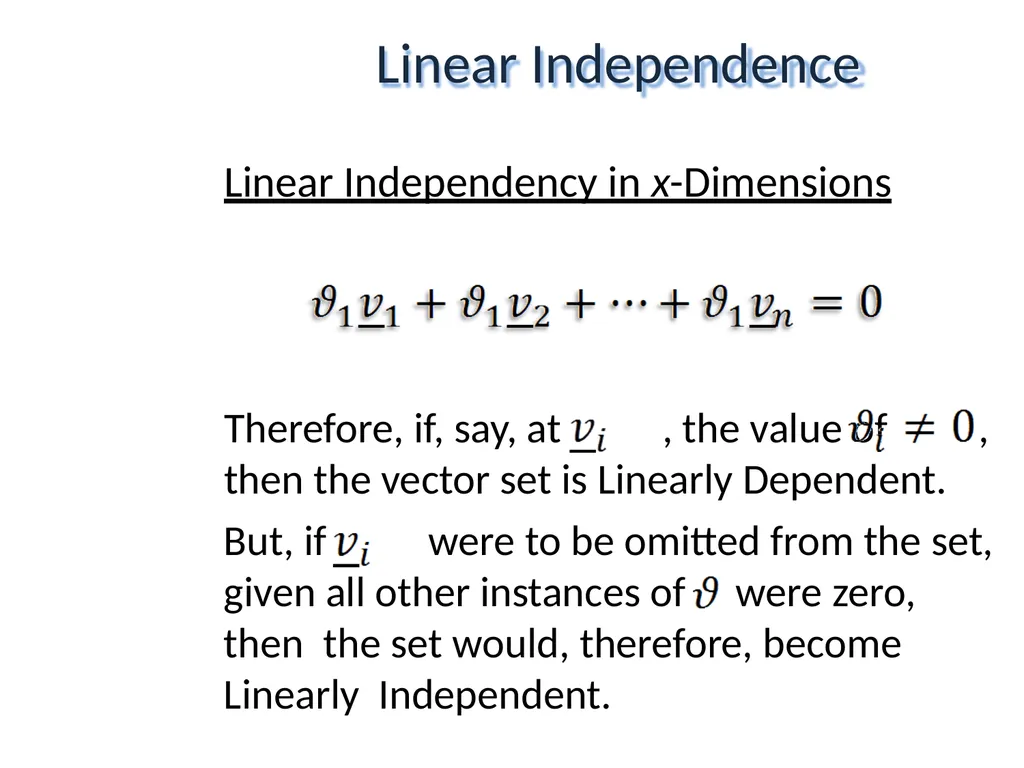
slide39. Linear Independency in x-Dimensions , Therefore, if, say, at , the value of
then the vector set is Linearly Dependent. But, if were to be omitted from the set, given all other instances of were zero, then the set would, therefore, become Linearly Independent. Linear Independence<br>
slide40. Implications of Linear Independence
If the set of Vectors, is Linearly Independent, then it is not possible to write any of the Vectors in the set in terms of any of the other Vectors within the same set.
Conversely, if a set of Vectors is Linearly Dependent, then it is possible to write at least one Vector in terms of at least one other Vector. Linear Independence<br>
slide41. Implications of Linear Independence
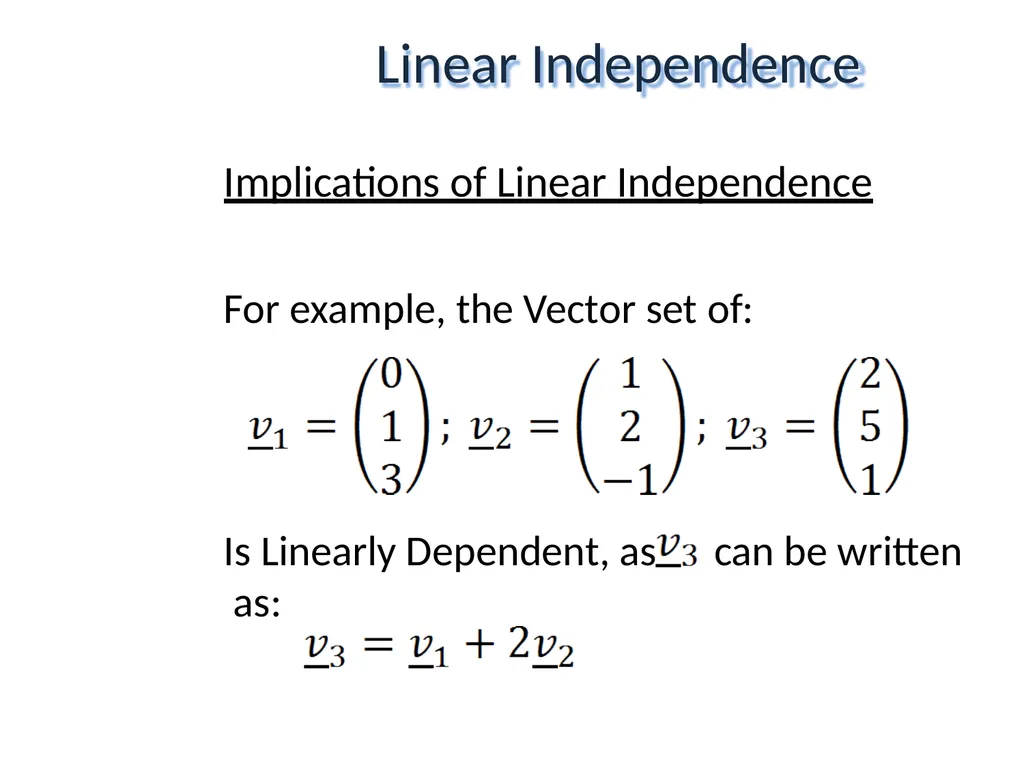
For example, the Vector set of: can be written Is Linearly Dependent, as as: Linear Independence<br>
slide42. Implications of Linear Independence
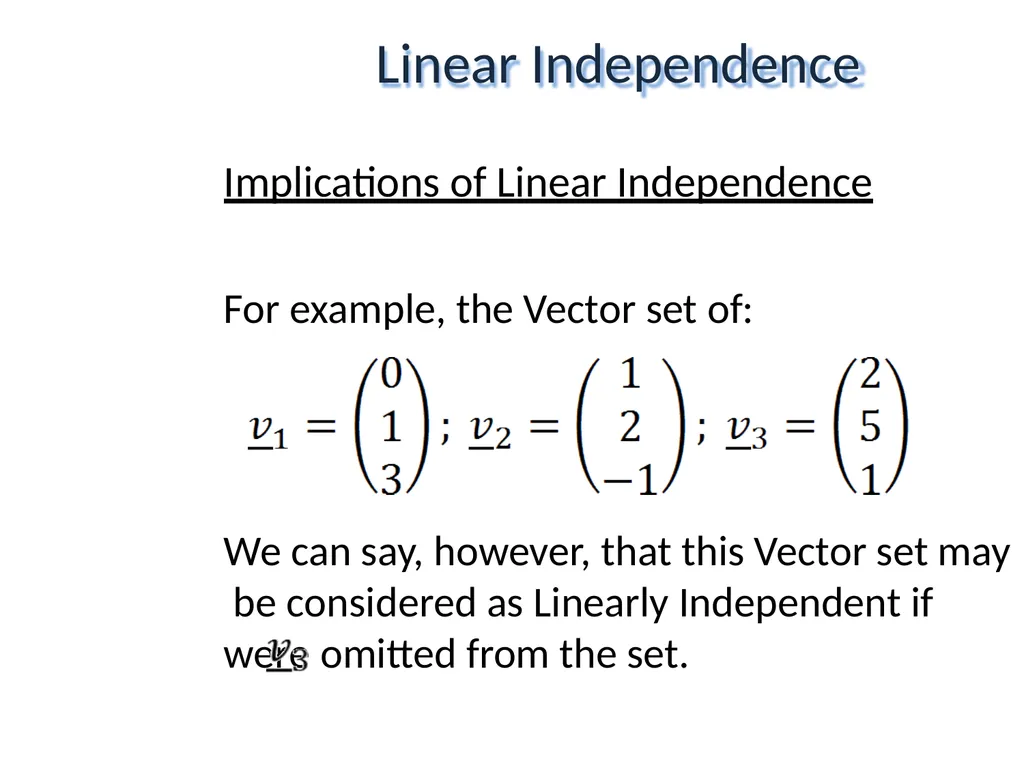
For example, the Vector set of: We can say, however, that this Vector set may be considered as Linearly Independent if were omitted from the set. Linear Independence<br>
slide43. Finding Linear Independency
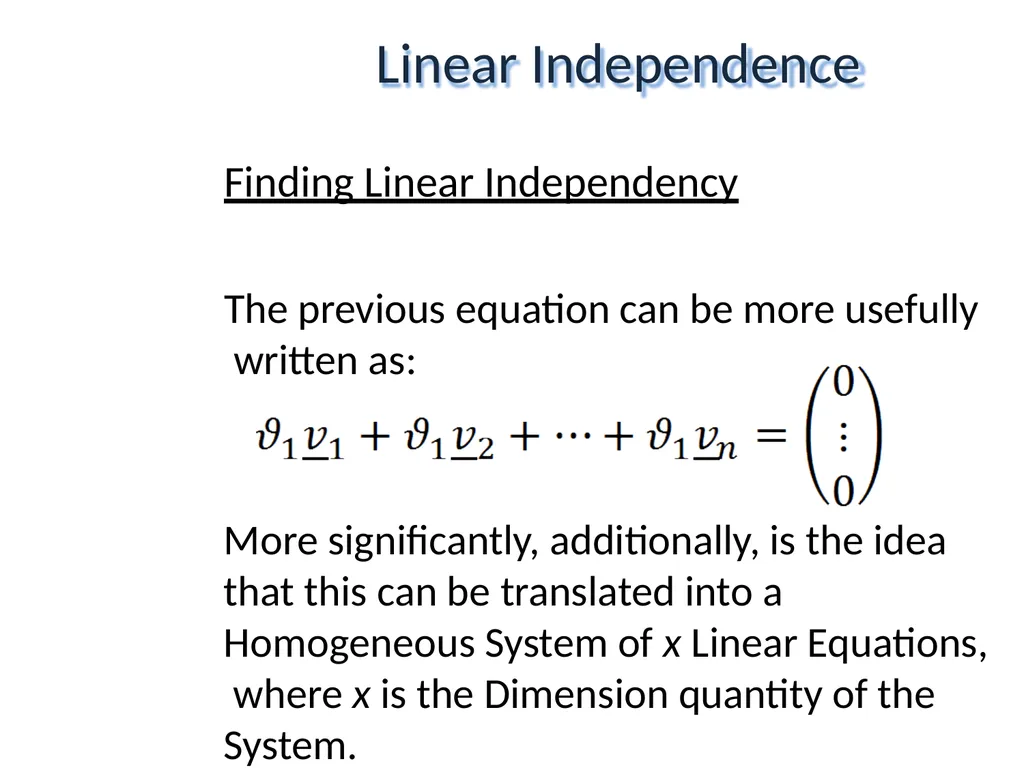
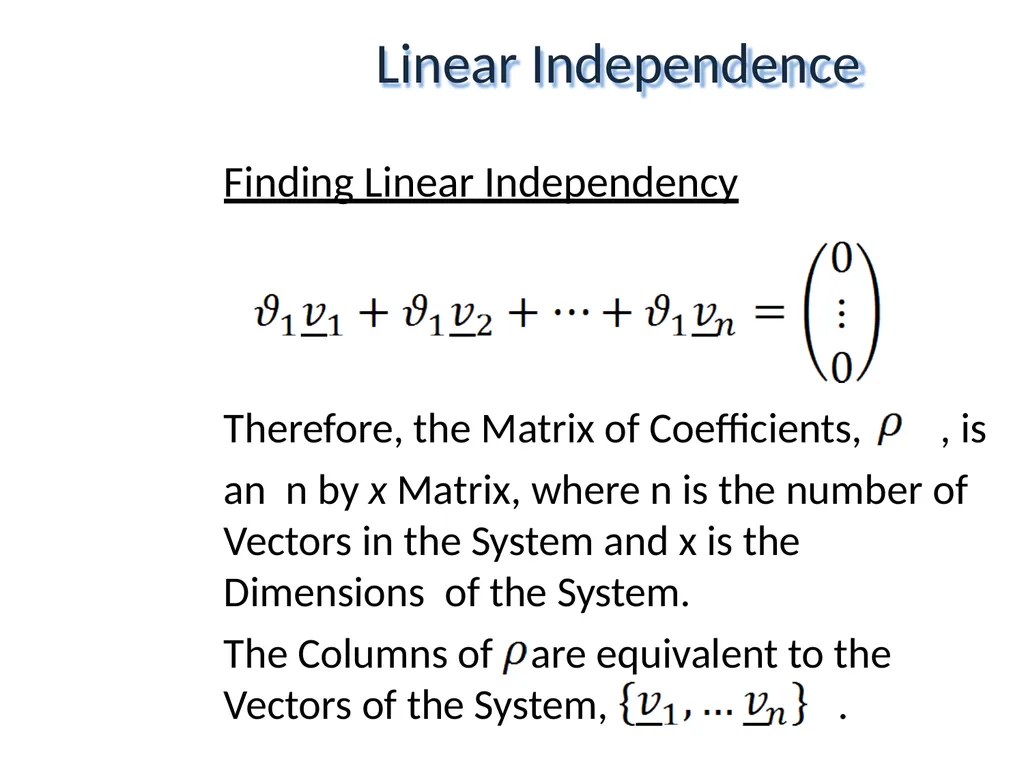
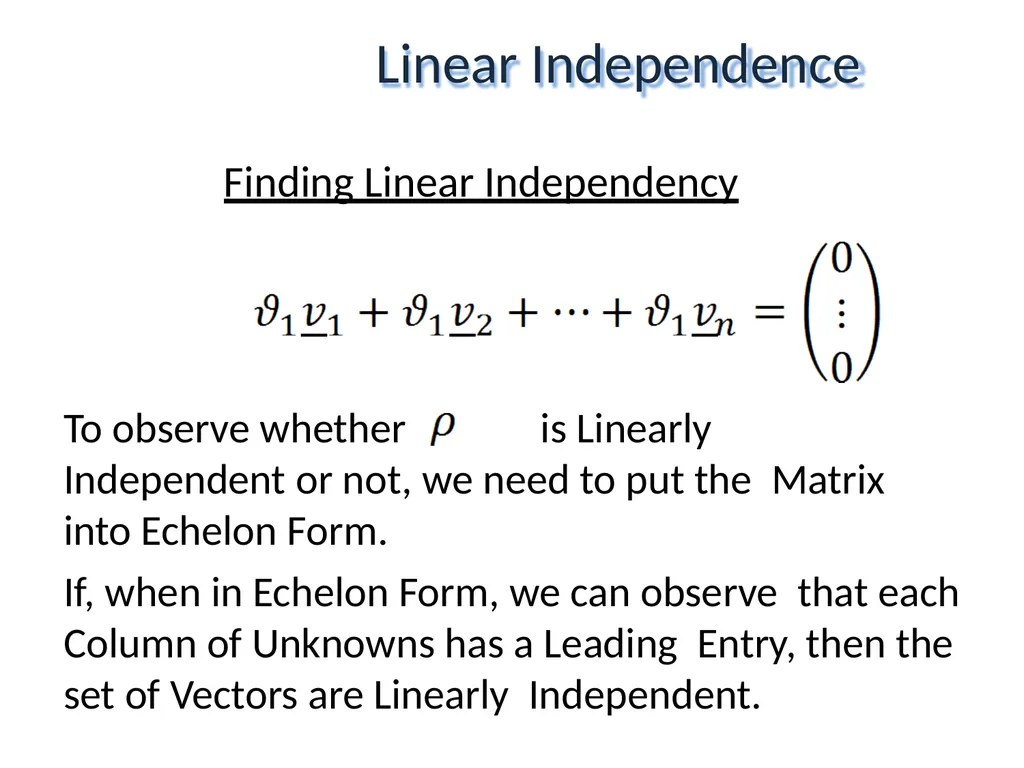
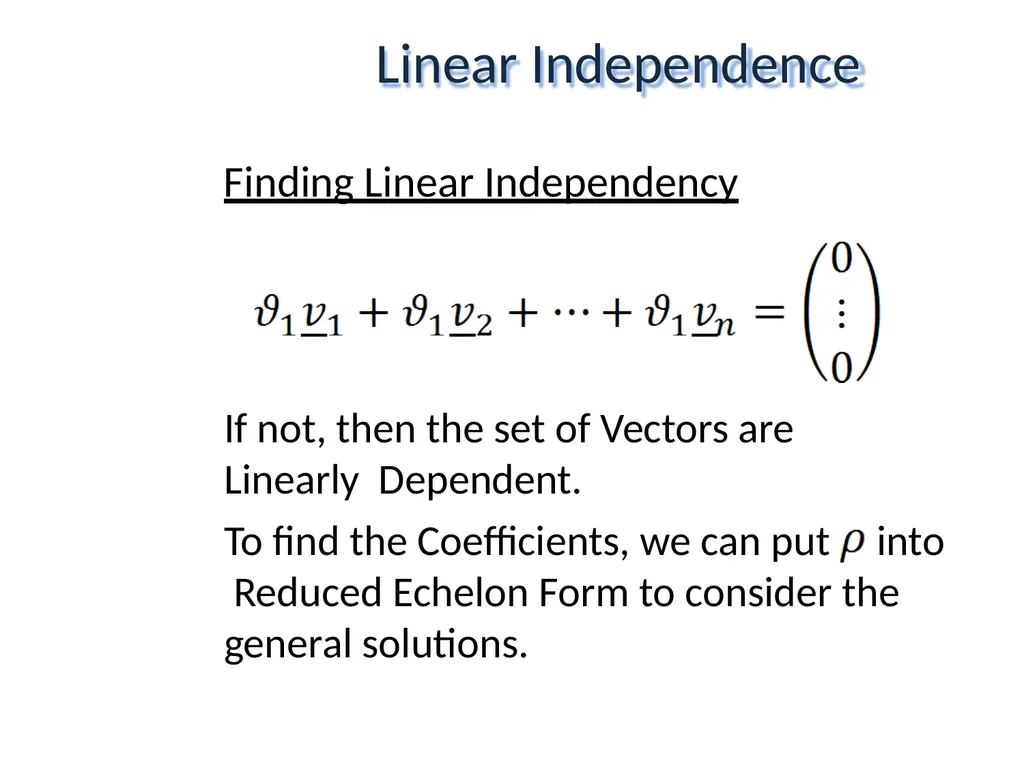
The previous equation can be more usefully written as: More significantly, additionally, is the idea that this can be translated into a Homogeneous System of x Linear Equations, where x is the Dimension quantity of the System. Linear Independence<br>
slide44. Finding Linear Independency Therefore, the Matrix of Coefficients, , is an n by x Matrix, where n is the number of
Vectors in the System and x is the Dimensions of the System.
The Columns of are equivalent to the Vectors of the System, . Linear Independence<br>
slide45. Finding Linear Independency To observe whether is Linearly Independent or not, we need to put the Matrix into Echelon Form.
If, when in Echelon Form, we can observe that each Column of Unknowns has a Leading Entry, then the set of Vectors are Linearly Independent. Linear Independence<br>
slide46. Finding Linear Independency If not, then the set of Vectors are Linearly Dependent.
To find the Coefficients, we can put into Reduced Echelon Form to consider the general solutions. Linear Independence<br>
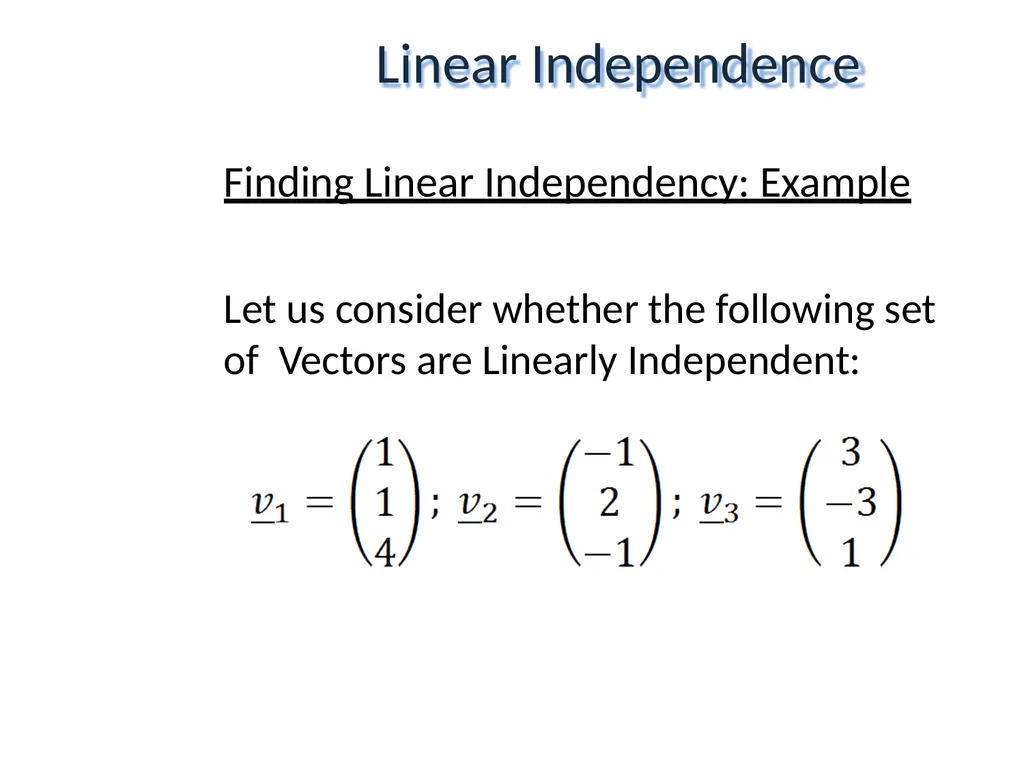
slide47. Finding Linear Independency: Example
Let us consider whether the following set of Vectors are Linearly Independent: Linear Independence<br>
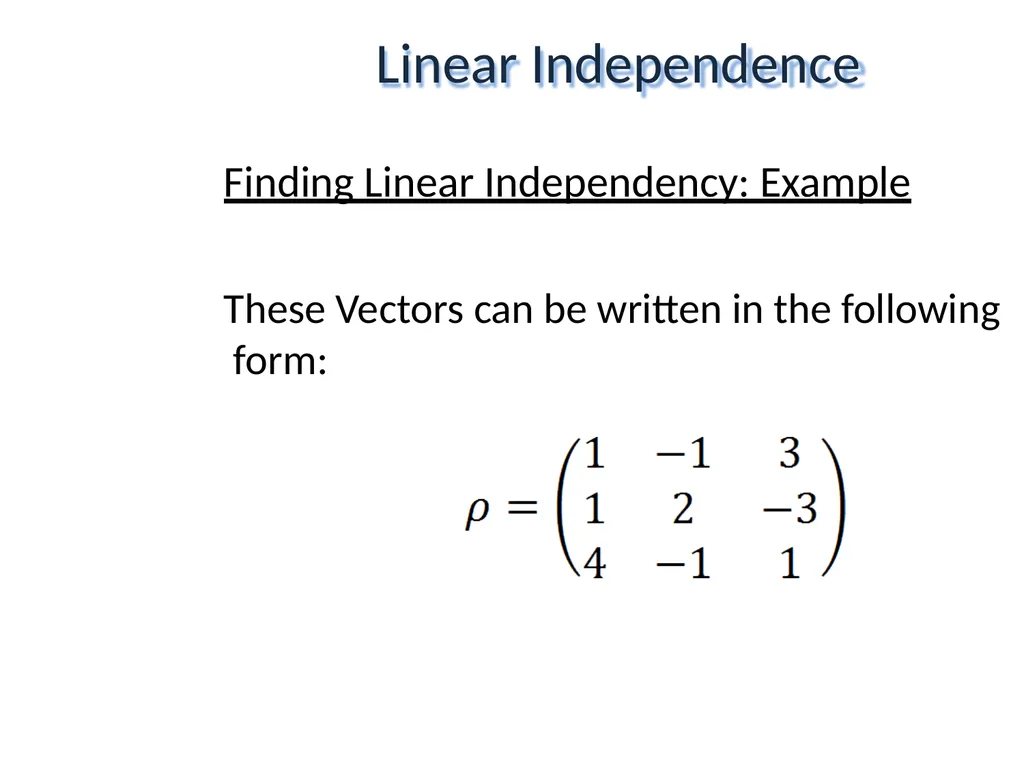
slide48. Finding Linear Independency: Example
These Vectors can be written in the following form: Linear Independence<br>
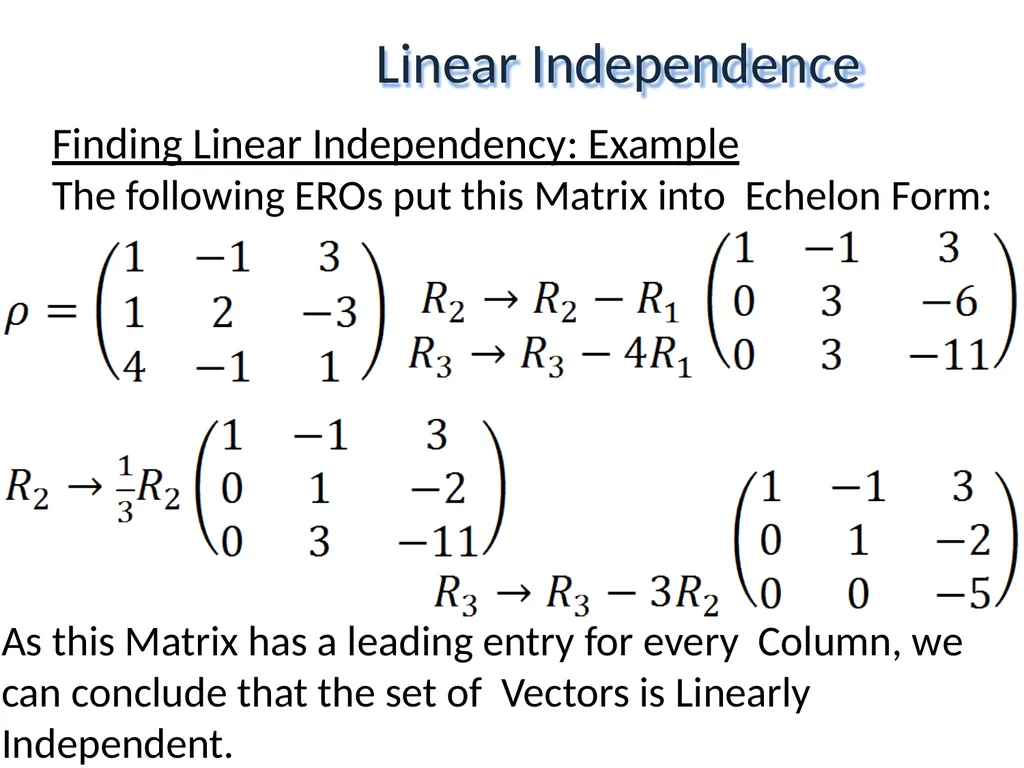
slide49. Finding Linear Independency: Example
The following EROs put this Matrix into Echelon Form: As this Matrix has a leading entry for every Column, we can conclude that the set of Vectors is Linearly Independent. Linear Independence<br>
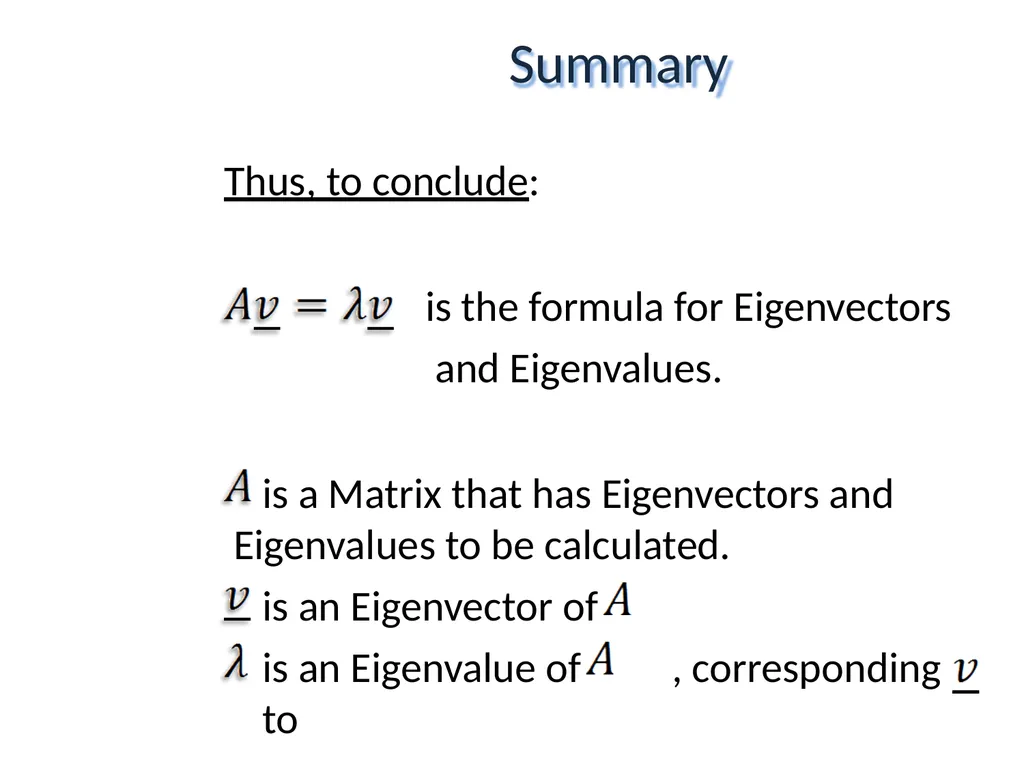
slide50. Thus, to conclude:
is the formula for Eigenvectors and Eigenvalues.
is a Matrix that has Eigenvectors and Eigenvalues to be calculated.
is an Eigenvector of
is an Eigenvalue of , corresponding to Summary<br>
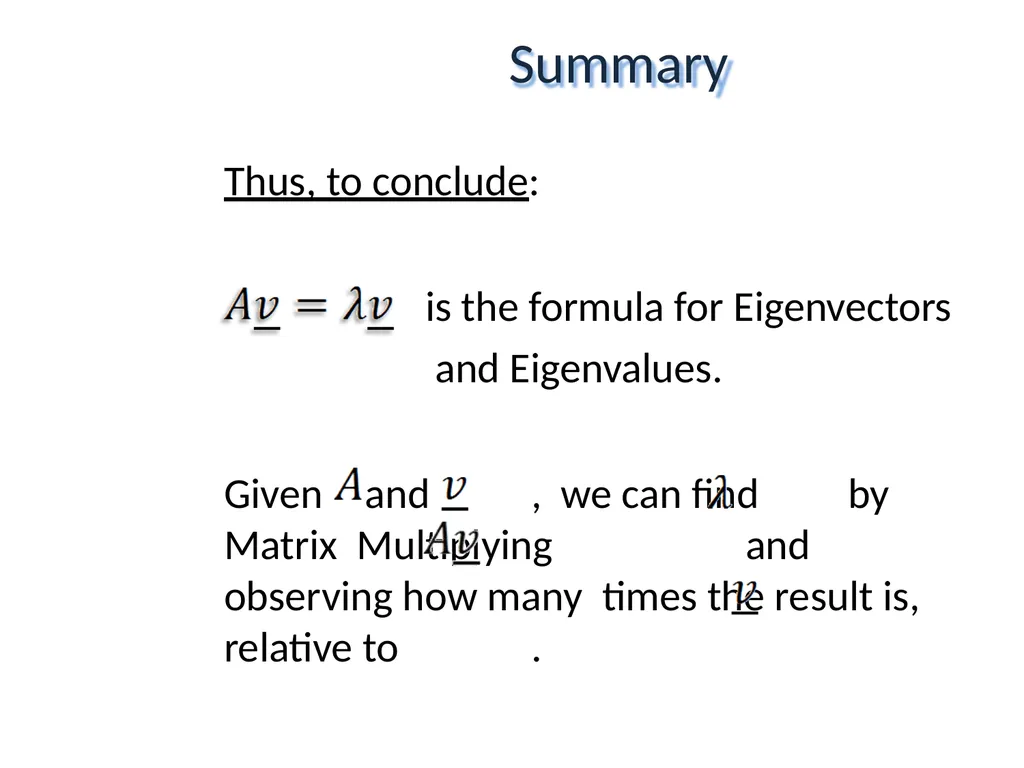
slide51. Thus, to conclude:
is the formula for Eigenvectors and Eigenvalues.
Given and , we can find by Matrix Multiplying and observing how many times the result is, relative to . Summary<br>
slide52. Thus, to conclude:
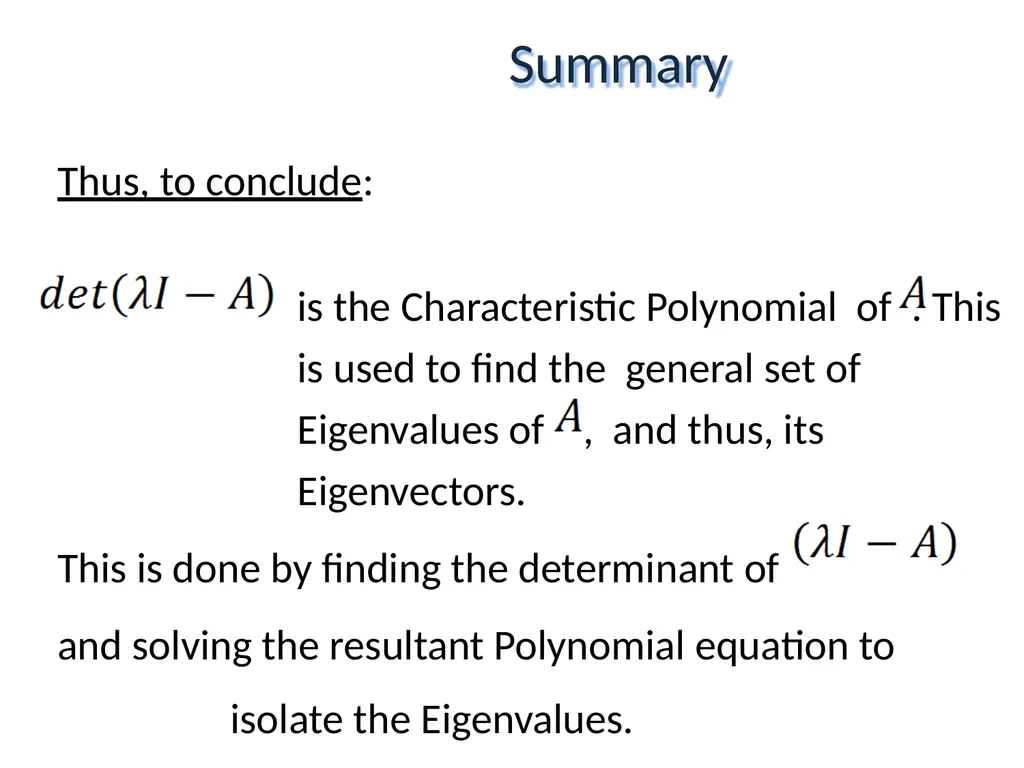
is the Characteristic Polynomial of . This is used to find the general set of Eigenvalues of , and thus, its Eigenvectors.
This is done by finding the determinant of
and solving the resultant Polynomial equation to isolate the Eigenvalues. Summary<br>
slide53. Thus, to conclude:
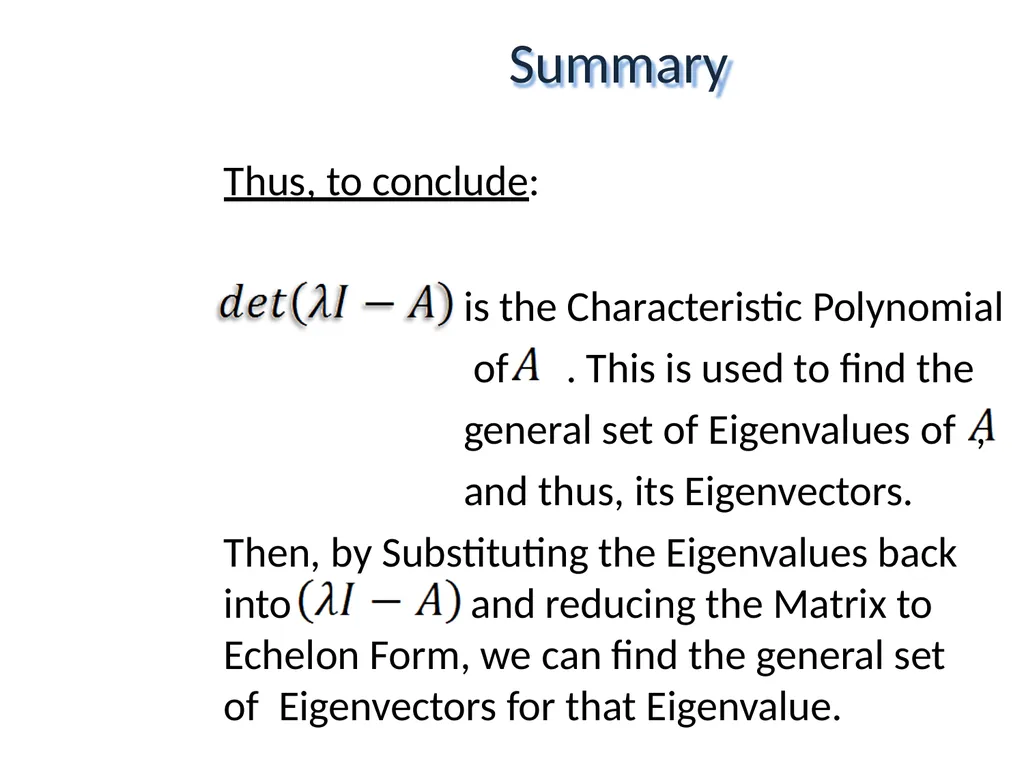
is the Characteristic Polynomial of . This is used to find the general set of Eigenvalues of , and thus, its Eigenvectors.
Then, by Substituting the Eigenvalues back into and reducing the Matrix to Echelon Form, we can find the general set of Eigenvectors for that Eigenvalue. Summary<br>
slide54. Thus, to conclude:
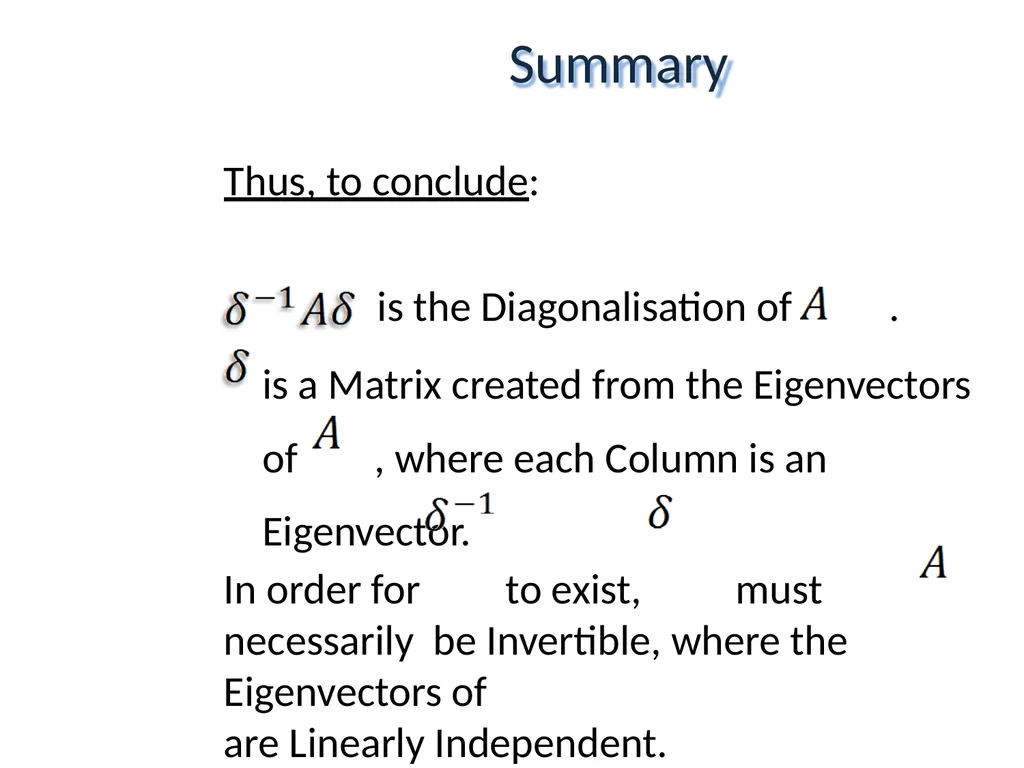
is the Diagonalisation of .
is a Matrix created from the Eigenvectors of , where each Column is an Eigenvector.
In order for to exist, must necessarily be Invertible, where the Eigenvectors of
are Linearly Independent. Summary<br>
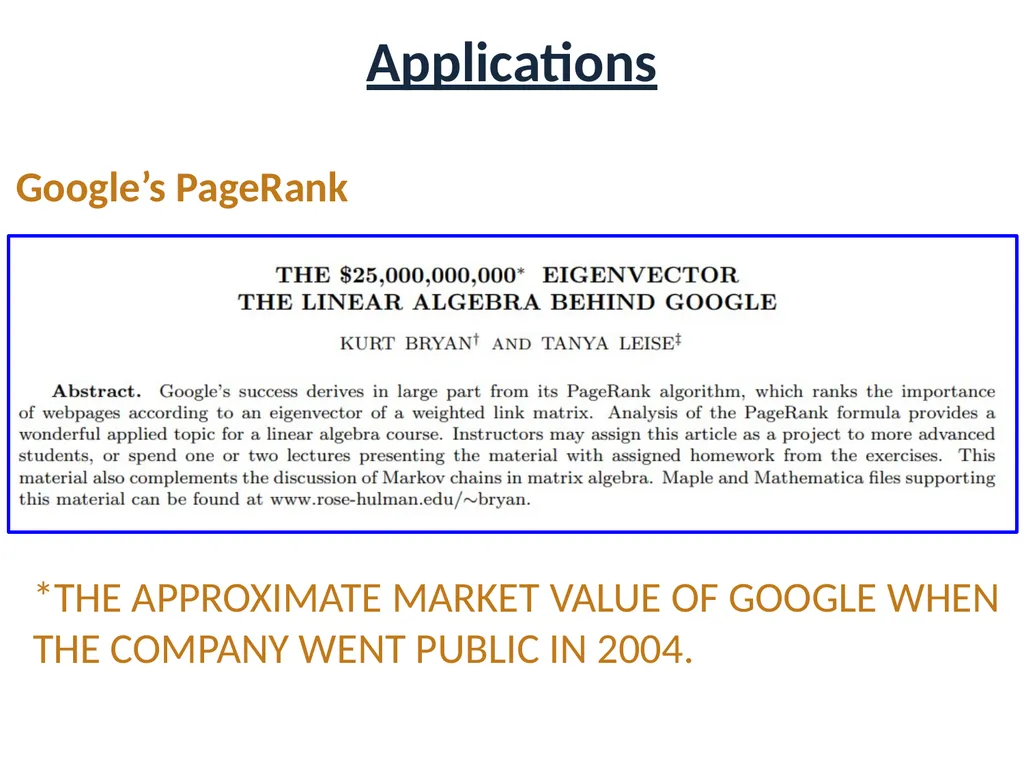
slide55. Applications Google’s PageRank *THE APPROXIMATE MARKET VALUE OF GOOGLE WHEN THE COMPANY WENT PUBLIC IN 2004.<br>
slide56. Applications Digital Image processing
PCA- Principal Component Analysis
SVM-Support Vector Machines
Natural Language Processing<br>
slide57. Time for Demo<br>
jothiram@nitk.edu.in<br>
slide2. Introduction: Diagonal Matrices Before beginning this topic, we must first clarify the definition of a “Diagonal Matrix”.
A Diagonal Matrix is an n by n Matrix whose non-diagonal entries have all the value zero.<br>
slide3. Introduction: Diagonal Matrices In this presentation, all Diagonal Matrices will be denoted as: where dnn is the entry at the n-th row and the n-th column of the Diagonal Matrix.<br>
slide4. Introduction: Diagonal Matrices For example, the previously given Matrix of: Can be written in the form:
diag(5, 4, 1, 9)<br>
slide5. Introduction: Diagonal Matrices The Effects of a Diagonal Matrix
The Identity Matrix is an example of a Diagonal Matrix which has the effect of maintaining the properties of a Vector within a given System.
For example:<br>
slide6. Introduction: Diagonal Matrices The Effects of a Diagonal Matrix
However, any other Diagonal Matrix will have the effect of enlarging a Vector in given axes. For example, the following Diagonal Matrix: Has the effect of stretching a Vector by a Scale Factor of 2 in the x-Axis, 3 in the z-Axis and reflecting the Vector in the y-Axis.<br>
slide7. The Goal By the end of this PowerPoint, we should be able to understand and apply the idea of Diagonalisation, using Eigenvalues and Eigenvectors.<br>
slide8. The Matrix Point of View
By the end, we should be able to understand how, given an n by n Matrix, A, we can say that A is Diagonalisable if and only if there is a Matrix, δ, that allows the following Matrix to be Diagonal:
And why this knowledge is significant. The Goal<br>
slide9. The Square Matrix, A, may be seen as a Linear Operator, F, defined by:
Where X is a Column Vector.
Linear : A(x+y) = Ax + Ay The Points of View<br>
slide10. Furthermore:
Represents the Linear Operator, F, relative to the Basis, or Coordinate System, S, whose Elements are the Columns of δ. The Points of View<br>
slide11. If we are given A, an n by n Matrix of any kind, then it is possible to interpret it as a Linear Transformation in a given Coordinate System of n-Dimensions.
For example: Has the effect of 45 degree Anticlockwise Rotation, in this case, on the Identity Matrix. The Effects of a Coordinate System<br>
slide12. However, it is theorised that it is possible to represent this Linear Transformation as a Diagonal Matrix within another, different Coordinate System.
We define the effect upon a given Vector in this new Coordinate System as:
There is a scalar multiplication of the Vector relative to all the axes by an unknown Scale Factor, without affecting direction or other properties. The Effects of a Coordinate System<br>
slide13. This process can be summarised by the following definition: Where:
A is the Transformation Matrix
v is a non-Zero Vector to be Transformed
λ is a Scalar in this new Coordinate System that has the same effect on v as A. The Effects of a Coordinate System Current Coordinate System New Coordinate System<br>
slide14. This process can be summarised by the following definition: Where:
: The Matrix is a Linear Transformation upon the Vector .
: is the Scalar which results in the same Transformation on as . The Effects of a Coordinate System Current Coordinate System New Coordinate System<br>
slide15. The Effects of a Coordinate System 1 2 This can be applied in the following example:
Matrix Vector
A<br>
slide16. The Effects of a Coordinate System This can be applied in the following example:
Matrix Vector
A 3 4 Thus, when: A is equivalent to the Diagonal Matrix:
Which, as discussed
previously, has the effect of enlarging the Vector by a Scale Factor of 2 in each Dimension.<br>
slide17. Thus, if is true, we call: the Eigenvector
the Eigenvalue of corresponding to Definitions<br>
slide18. We do not count as an Eigenvector, as for all values of λ.
However, is allowed as an accepted Eigenvalue.
If is a known Eigenvector of a Matrix, then so is , for all non-Zero values of
.
If Vectors are both Eigenvectors of a given Matrix, and both have the same resultant Eigenvalue, then will also be an Eigenvector of the Matrix. Exceptions and Additions<br>
slide19. Establishing the Essentials
is an Eigenvalue for the Matrix , relative to the Eigenvector . Is the Identity Matrix of the same Dimensions as . Thus: = = 0 Characteristic Polynomials<br>
slide20. Application of the Knowledge
What this, essentially, leads to is the finding of all Eigenvalues and Eigenvectors of a specific Matrix.
This is done by considering the Matrix, , in addition to the Identity Matrix, .
We then multiply the Identity Matrix by the unknown quantity, . Characteristic Polynomials<br>
slide21. Application of the Knowledge
Proceeding this, we then take the lots of the Identity Matrix, and subtract the Matrix from it.
We then take the Determinant of the result which ends up as a Polynomial equation, in order to find possible values of , the Eigenvalues.
This can be exemplified by the following example: Characteristic Polynomials<br>
slide22. Calculating Eigenvalues from a Matrix
To find the Eigenvalues of A We must consider : Characteristic Polynomials<br>
slide23. Calculating Eigenvalues from a Matrix
Then, =
Which factorises to:
Therefore, the Eigenvalues of the Matrix are: Characteristic Polynomials<br>
slide24. Calculating Eigenvectors from the Values for all given With:
We need to solve values of . This is done by solving a Homogeneous System of Linear Equations. In other words, we must turn
and find the values of into Echelon Form
, which are the Diagonals of the Matrix. Characteristic Polynomials<br>
slide25. Calculating Eigenvectors from the Values
For example, we will take from the Previous example: Characteristic Polynomials<br>
slide26. Characteristic Polynomials<br>
slide27. Calculating Eigenvectors from the Values
For example, we will take from the Previous example:
Therefore, the result is that: Characteristic Polynomials<br>
slide28. Calculating Eigenvectors from the Values
For example, we will take from the Previous example:
is the set of general Eigenvectors for the Eigenvalue of 4. Characteristic Polynomials<br>
slide29. Mentioned earlier was the ultimate goal of Diagonalisation; that is to say, finding a Matrix, , such that the following can be applied to a given Matrix, : Where the result is a Diagonal Matrix. Diagonalisation<br>
slide30. There are a few rules that can be derived from this:
Firstly, must be an Invertible Matrix, as the Inverse is necessary to the calculation.
Secondly, the Eigenvectors of must necessarily be Linearly Independent for this to work.
Linear Independence will be covered later. Diagonalisation<br>
slide31. Eigenvectors, Eigenvalues & Diagonalisation
It turns out that the columns of the Matrix are the Eigenvectors of the Matrix . This is why they must be Linearly Independent, as Matrix must be Invertible.
Furthermore, the Diagonal Entries of the resultant Matrix are the Eigenvalues associated with that Column of Eigenvectors. Diagonalisation<br>
slide32. Eigenvectors, Eigenvalues & Diagonalisation
For example, in the previous example, we can create a Matrix from the Eigenvalues 4, 2 and 6, respectively.
It is as follows: Diagonalisation<br>
slide33. Eigenvectors, Eigenvalues & Diagonalisation
Furthermore, we can calculate that: Diagonalisation<br>
slide34. Eigenvectors, Eigenvalues & Diagonalisation
Thus, the Diagonalisation of can be created by: Solving this gives:
The Eigenvalues in the Order given! Diagonalisation<br>
slide35. Eigenvectors, Eigenvalues & Diagonalisation
Thus, the Diagonalisation of can be created by: Diagonalisation<br>
slide36. Introduction
This will be a brief section on Linear Independence to enforce that the Eigenvectors of must be Linearly Independent for Diagonalisation to be implemented. Linear Independence<br>
slide37. Linear Independency in x-Dimensions
The vectors are classified as a Linearly Independent set of Vectors if the following rule applies:
The only value of the Scalar, , which makes the equation:
True is for all instances of Linear Independence<br>
slide38. Linear Independency in x-Dimensions If there are any non-zero values of at any instance of within the equation, then this set of Vectors, , is considered Linearly Dependent.
It is to note that only one instance of non-zero is needed to make the dependence. Linear Independence<br>
slide39. Linear Independency in x-Dimensions , Therefore, if, say, at , the value of
then the vector set is Linearly Dependent. But, if were to be omitted from the set, given all other instances of were zero, then the set would, therefore, become Linearly Independent. Linear Independence<br>
slide40. Implications of Linear Independence
If the set of Vectors, is Linearly Independent, then it is not possible to write any of the Vectors in the set in terms of any of the other Vectors within the same set.
Conversely, if a set of Vectors is Linearly Dependent, then it is possible to write at least one Vector in terms of at least one other Vector. Linear Independence<br>
slide41. Implications of Linear Independence
For example, the Vector set of: can be written Is Linearly Dependent, as as: Linear Independence<br>
slide42. Implications of Linear Independence
For example, the Vector set of: We can say, however, that this Vector set may be considered as Linearly Independent if were omitted from the set. Linear Independence<br>
slide43. Finding Linear Independency
The previous equation can be more usefully written as: More significantly, additionally, is the idea that this can be translated into a Homogeneous System of x Linear Equations, where x is the Dimension quantity of the System. Linear Independence<br>
slide44. Finding Linear Independency Therefore, the Matrix of Coefficients, , is an n by x Matrix, where n is the number of
Vectors in the System and x is the Dimensions of the System.
The Columns of are equivalent to the Vectors of the System, . Linear Independence<br>
slide45. Finding Linear Independency To observe whether is Linearly Independent or not, we need to put the Matrix into Echelon Form.
If, when in Echelon Form, we can observe that each Column of Unknowns has a Leading Entry, then the set of Vectors are Linearly Independent. Linear Independence<br>
slide46. Finding Linear Independency If not, then the set of Vectors are Linearly Dependent.
To find the Coefficients, we can put into Reduced Echelon Form to consider the general solutions. Linear Independence<br>
slide47. Finding Linear Independency: Example
Let us consider whether the following set of Vectors are Linearly Independent: Linear Independence<br>
slide48. Finding Linear Independency: Example
These Vectors can be written in the following form: Linear Independence<br>
slide49. Finding Linear Independency: Example
The following EROs put this Matrix into Echelon Form: As this Matrix has a leading entry for every Column, we can conclude that the set of Vectors is Linearly Independent. Linear Independence<br>
slide50. Thus, to conclude:
is the formula for Eigenvectors and Eigenvalues.
is a Matrix that has Eigenvectors and Eigenvalues to be calculated.
is an Eigenvector of
is an Eigenvalue of , corresponding to Summary<br>
slide51. Thus, to conclude:
is the formula for Eigenvectors and Eigenvalues.
Given and , we can find by Matrix Multiplying and observing how many times the result is, relative to . Summary<br>
slide52. Thus, to conclude:
is the Characteristic Polynomial of . This is used to find the general set of Eigenvalues of , and thus, its Eigenvectors.
This is done by finding the determinant of
and solving the resultant Polynomial equation to isolate the Eigenvalues. Summary<br>
slide53. Thus, to conclude:
is the Characteristic Polynomial of . This is used to find the general set of Eigenvalues of , and thus, its Eigenvectors.
Then, by Substituting the Eigenvalues back into and reducing the Matrix to Echelon Form, we can find the general set of Eigenvectors for that Eigenvalue. Summary<br>
slide54. Thus, to conclude:
is the Diagonalisation of .
is a Matrix created from the Eigenvectors of , where each Column is an Eigenvector.
In order for to exist, must necessarily be Invertible, where the Eigenvectors of
are Linearly Independent. Summary<br>
slide55. Applications Google’s PageRank *THE APPROXIMATE MARKET VALUE OF GOOGLE WHEN THE COMPANY WENT PUBLIC IN 2004.<br>
slide56. Applications Digital Image processing
PCA- Principal Component Analysis
SVM-Support Vector Machines
Natural Language Processing<br>
slide57. Time for Demo<br>