02
Outline Performance Migration to Open Solutions
What’s open, what is the cost?
Opportunities for a smooth migration
Migration example: ICS/DX to MPI over sRIO
OFED sRIO Performance Data / Analysis
Message passing and RDMA patterns, benchmarking approach
Varied approaches within sRIO (MPI, OFED, ICS/DX, etc.)
Common approaches across fabrics (sRIO, IB, iWARP)
Conclusions<br>
04
4 Performance Migration to Open Solutions © 2010 Mercury Computer Systems, Inc. www.mc.com High Level Perspective<br>
05
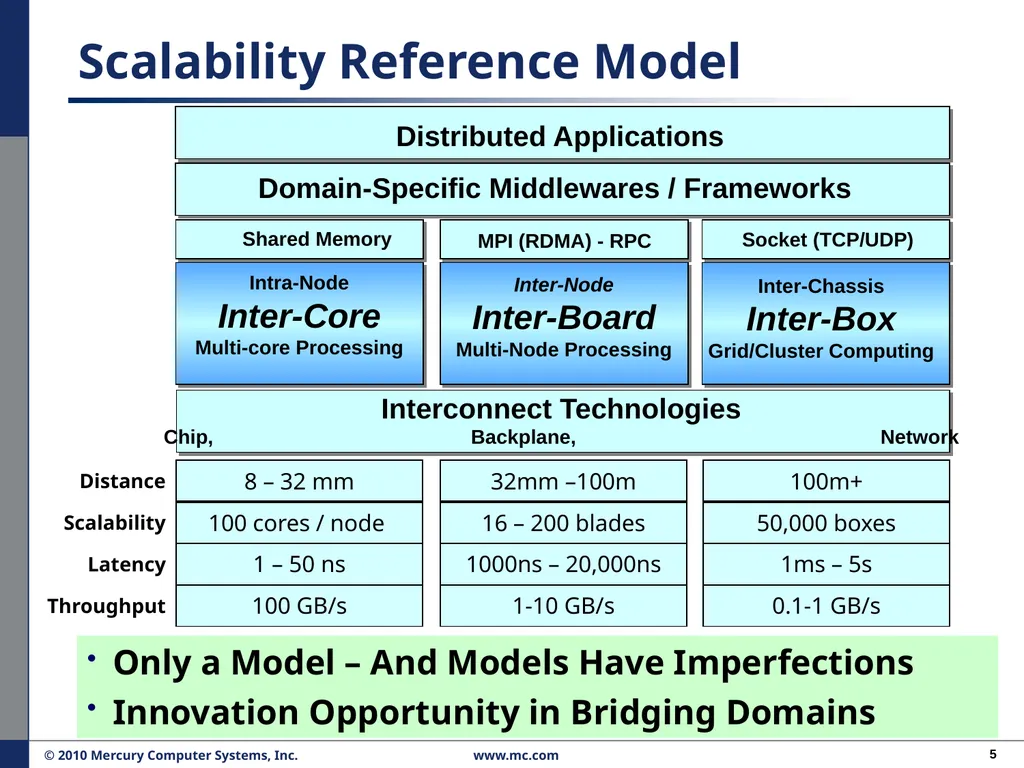
Scalability Reference Model Inter-Node
Inter-Board
Multi-Node Processing Intra-Node
Inter-Core
Multi-core Processing Inter-Chassis
Inter-Box
Grid/Cluster Computing Domain-Specific Middlewares / Frameworks Distributed Applications Interconnect Technologies
Chip, Backplane, Network Shared Memory MPI (RDMA) - RPC Socket (TCP/UDP) Only a Model – And Models Have Imperfections
Innovation Opportunity in Bridging Domains<br>
06
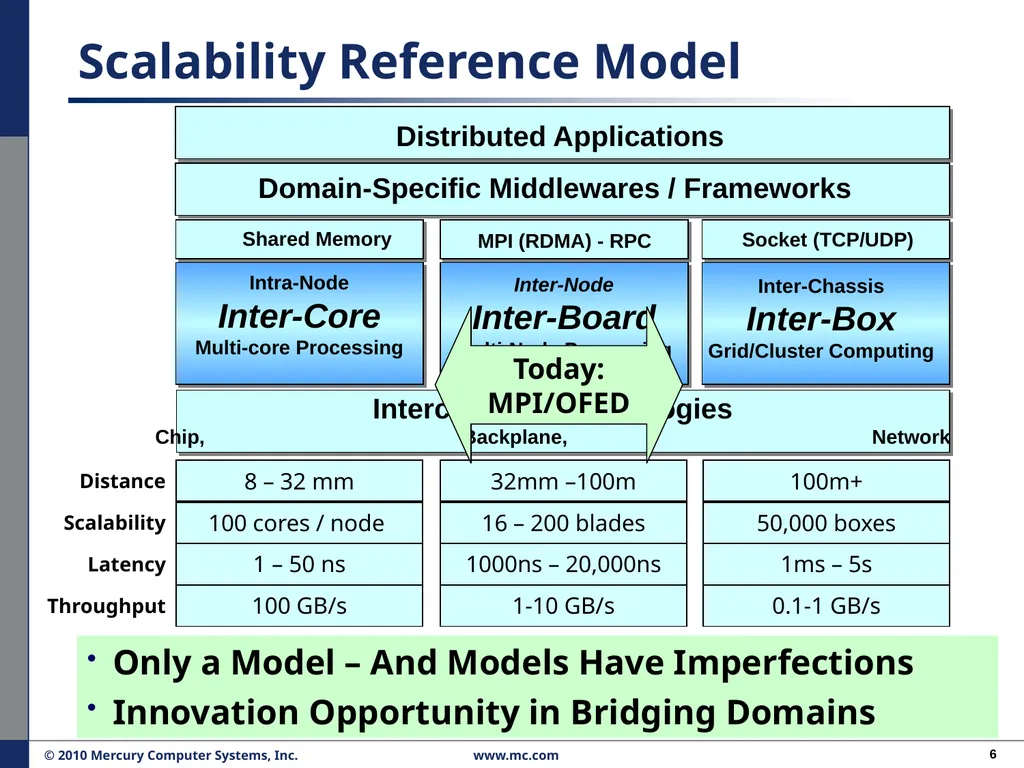
Scalability Reference Model Inter-Node
Inter-Board
Multi-Node Processing Intra-Node
Inter-Core
Multi-core Processing Inter-Chassis
Inter-Box
Grid/Cluster Computing Domain-Specific Middlewares / Frameworks Distributed Applications Interconnect Technologies
Chip, Backplane, Network Shared Memory MPI (RDMA) - RPC Socket (TCP/UDP) Only a Model – And Models Have Imperfections
Innovation Opportunity in Bridging Domains Today:
MPI/OFED<br>
07
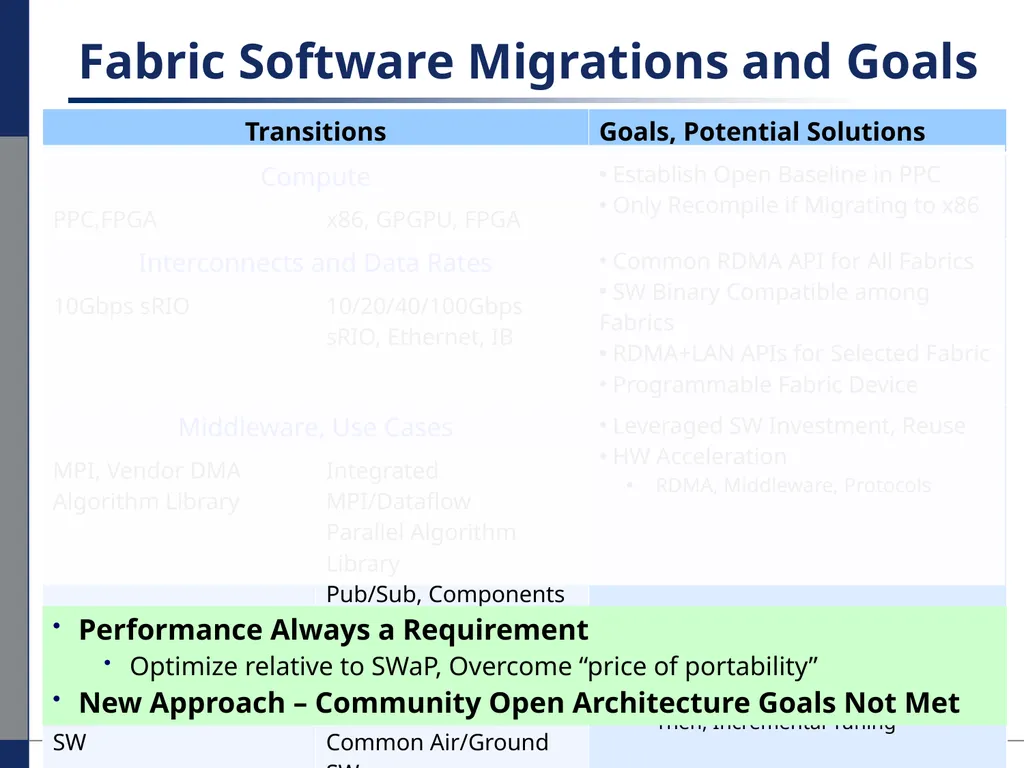
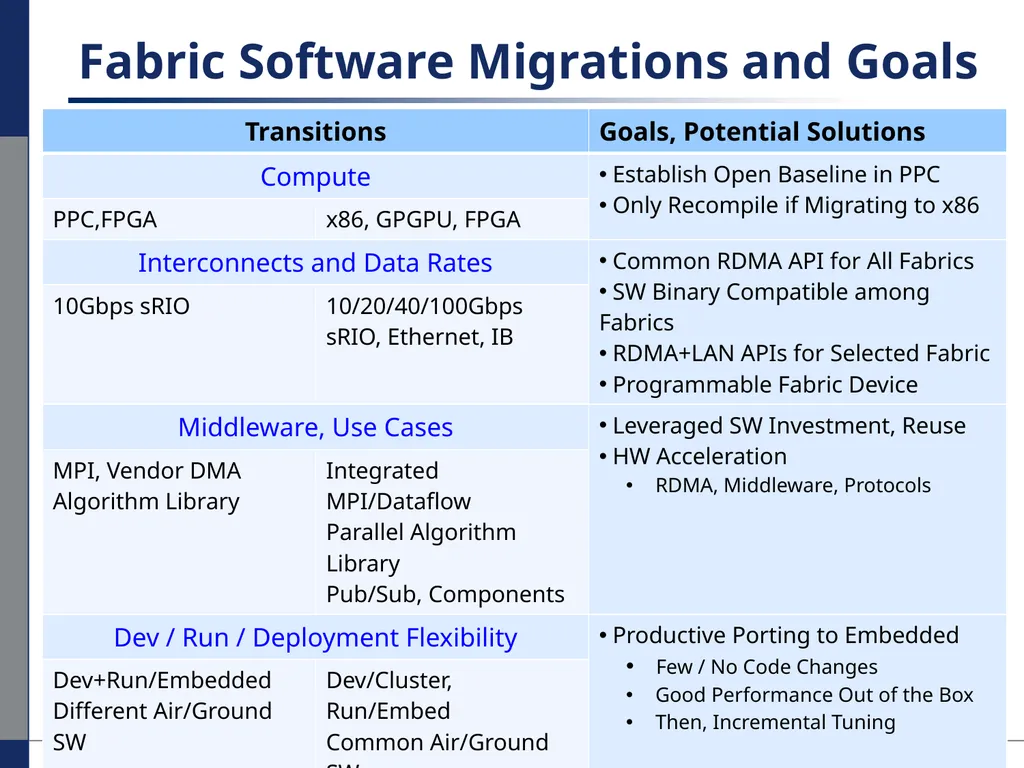
Fabric Software Migrations and Goals<br>
08
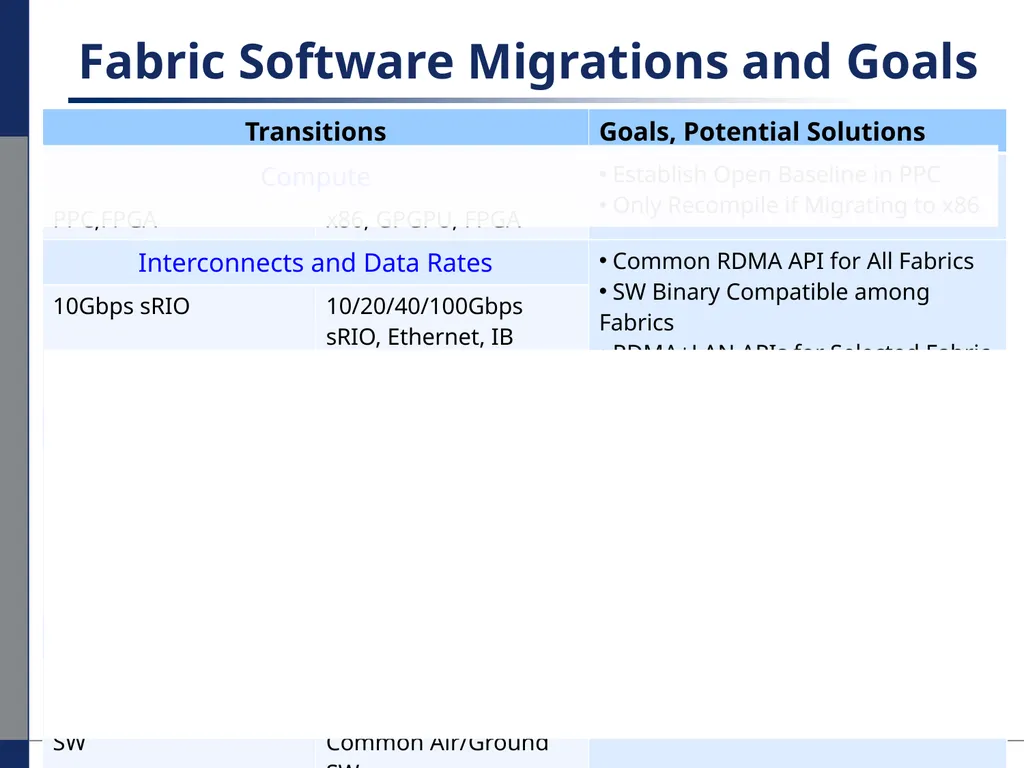
Fabric Software Migrations and Goals<br>
09
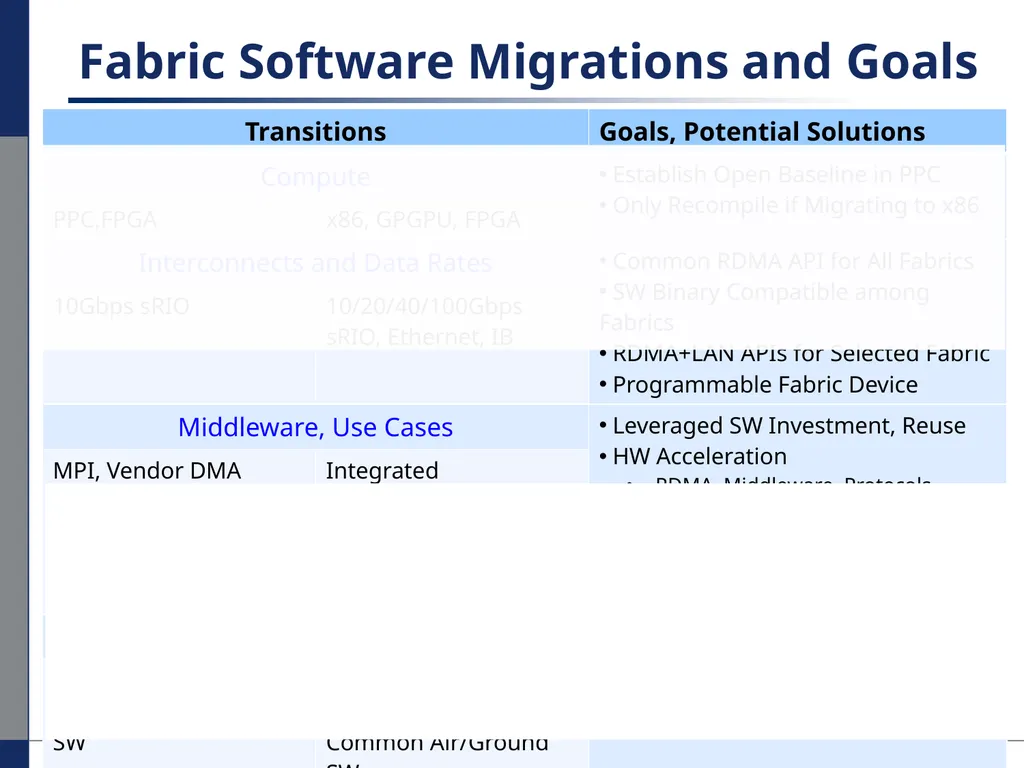
Fabric Software Migrations and Goals<br>
10
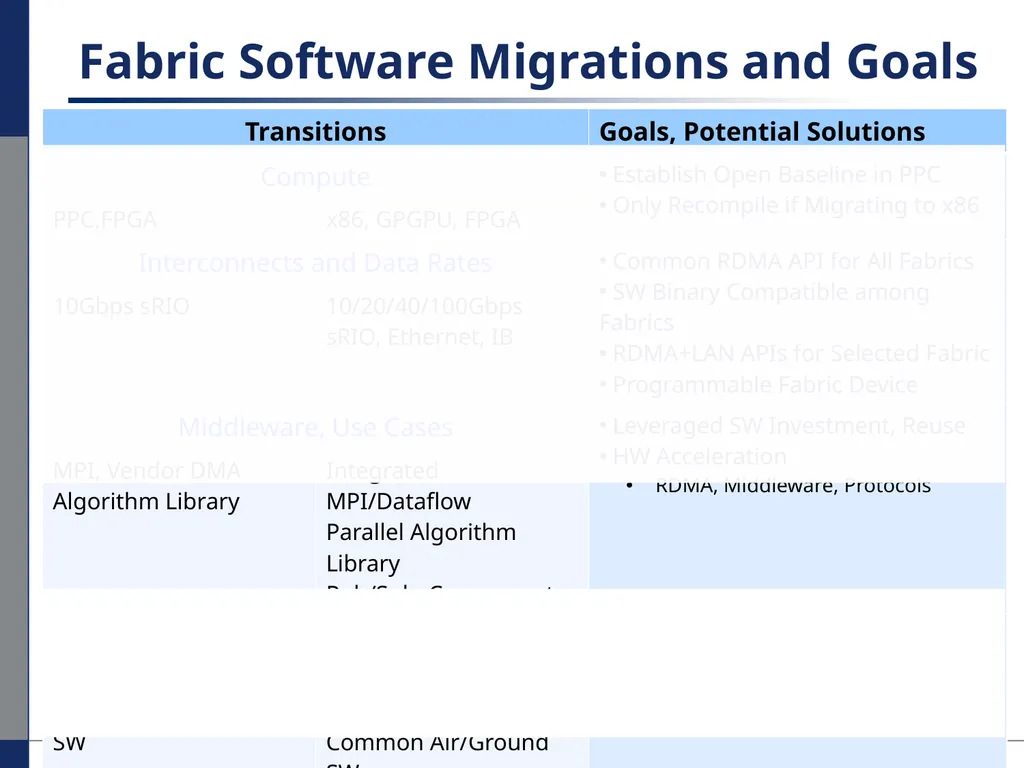
Fabric Software Migrations and Goals<br>
11
Fabric Software Migrations and Goals Performance Always a Requirement
Optimize relative to SWaP, Overcome “price of portability”
New Approach – Community Open Architecture Goals Not Met<br>
12
Fabric Software Migrations and Goals Performance Always a Requirement
Optimize relative to SWaP, Overcome “price of portability”
New Approach – Community Open Architecture Goals Not Met<br>
13
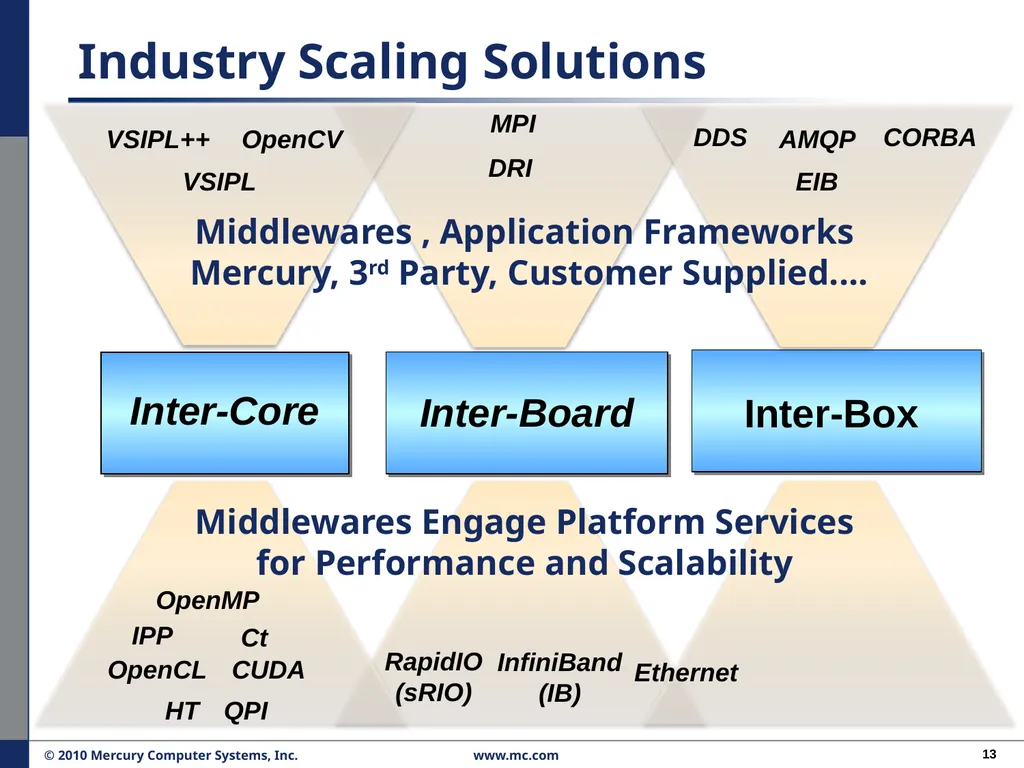
Industry Scaling Solutions Middlewares , Application Frameworks
Mercury, 3rd Party, Customer Supplied....<br>
14
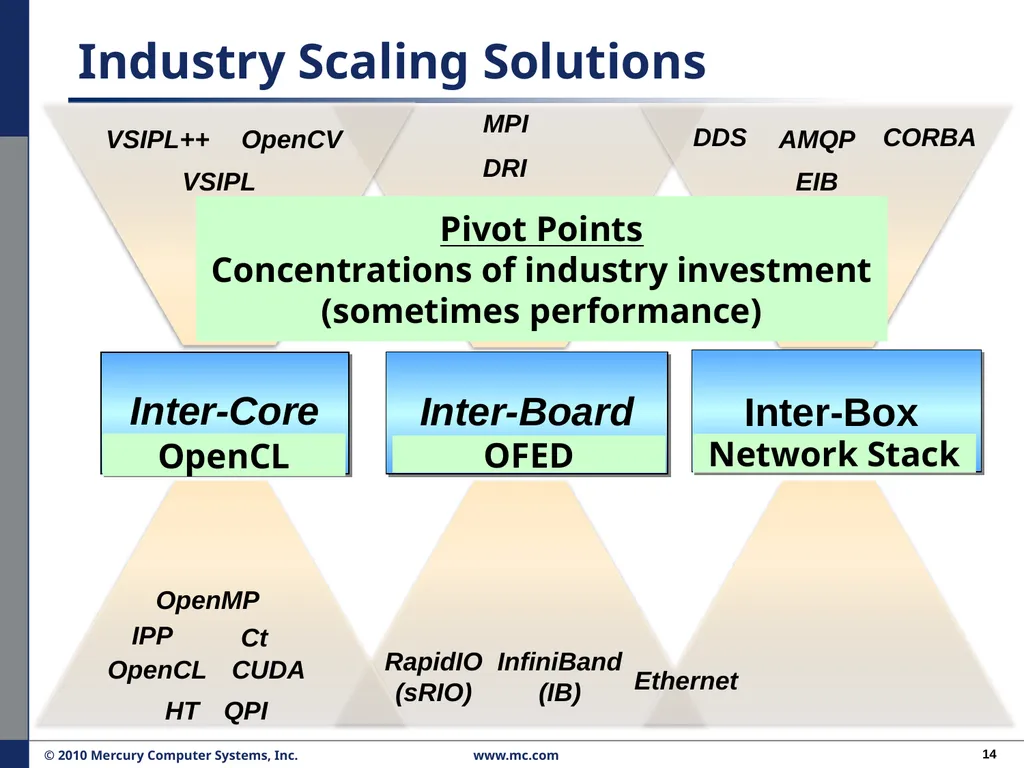
Industry Scaling Solutions EIB Pivot Points
Concentrations of industry investment
(sometimes performance) OpenCL OFED Network Stack DRI<br>
15
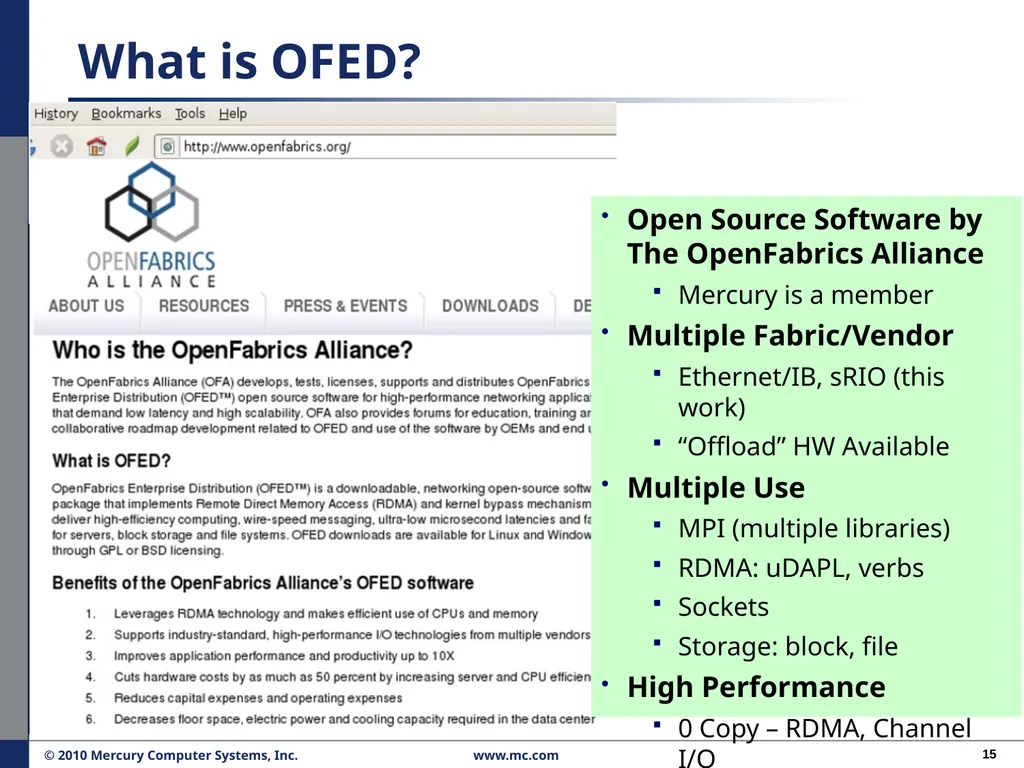
What is OFED? Open Source Software by The OpenFabrics Alliance
Mercury is a member
Multiple Fabric/Vendor
Ethernet/IB, sRIO (this work)
“Offload” HW Available
Multiple Use
MPI (multiple libraries)
RDMA: uDAPL, verbs
Sockets
Storage: block, file
High Performance
0 Copy – RDMA, Channel I/O<br>
16
OFA – Significant Membership Roster See http://www.openfabrics.org for the list
HPC, System Integrators including “Tier 1”
Microprocessor Providers
Networking Providers (NIC/HCA, Switch)
Server/Enterprise Software + Systems Providers
NAS / SAN Providers
Switched Fabric Industry Trade Associations
Financial Services / Technology Providers
National Laboratories
Universities
Software Consulting Organizations<br>
17
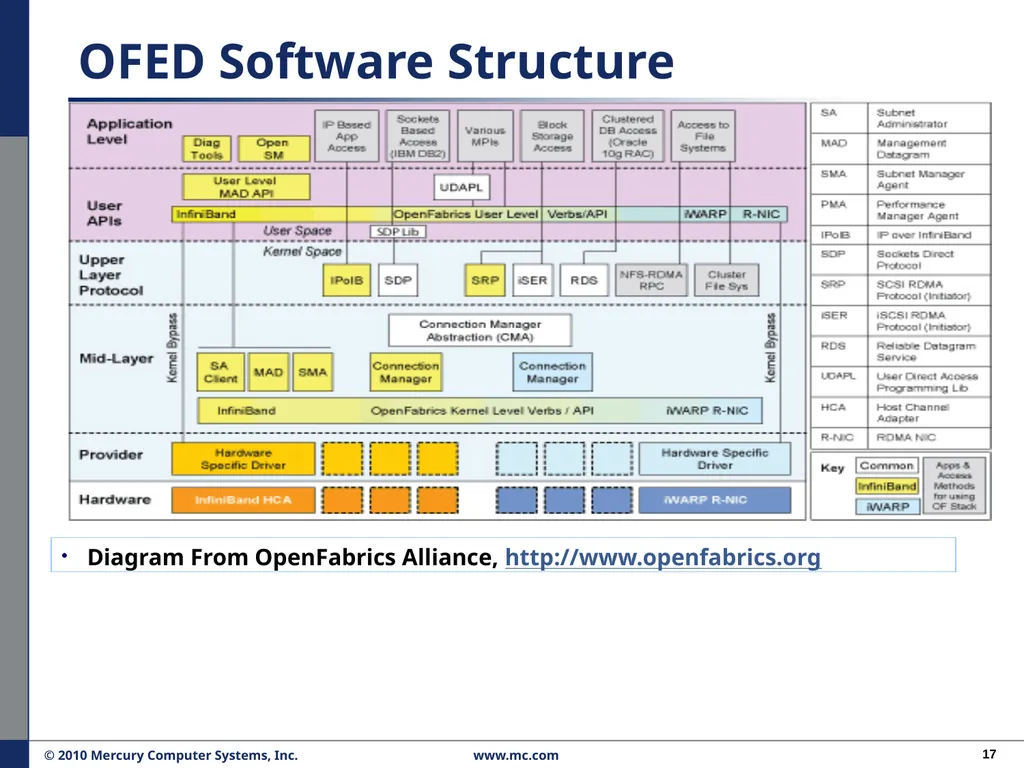
OFED Software Structure<br>
18
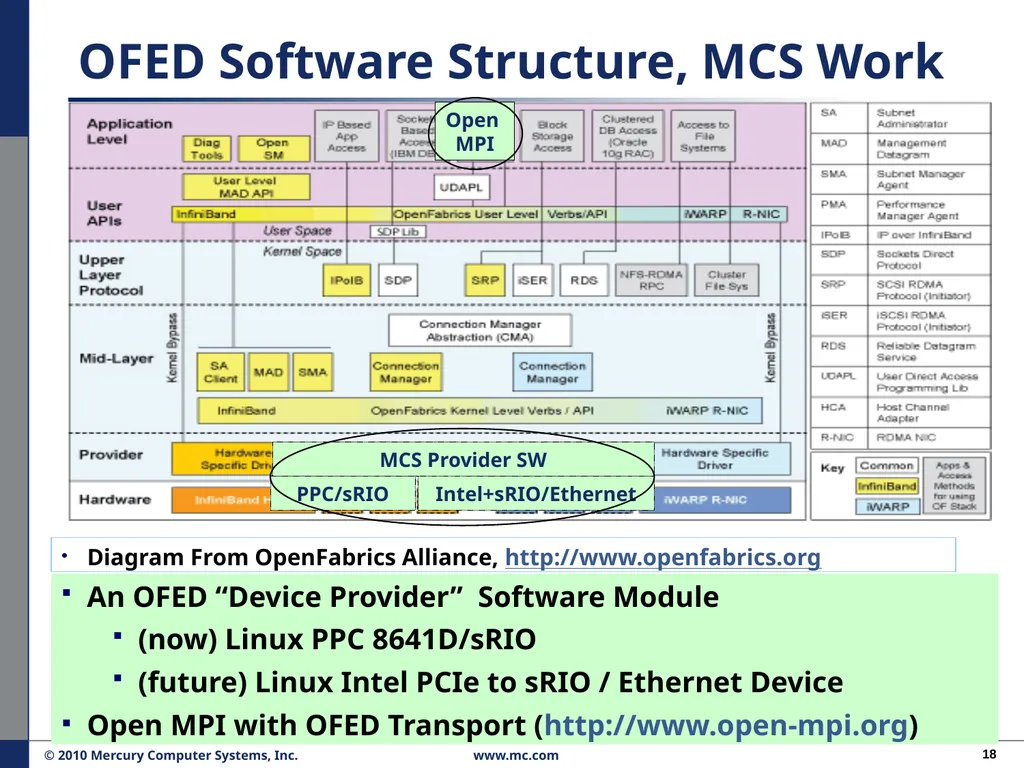
OFED Software Structure, MCS Work An OFED “Device Provider” Software Module
(now) Linux PPC 8641D/sRIO
(future) Linux Intel PCIe to sRIO / Ethernet Device
Open MPI with OFED Transport (http://www.open-mpi.org) Open
MPI<br>
19
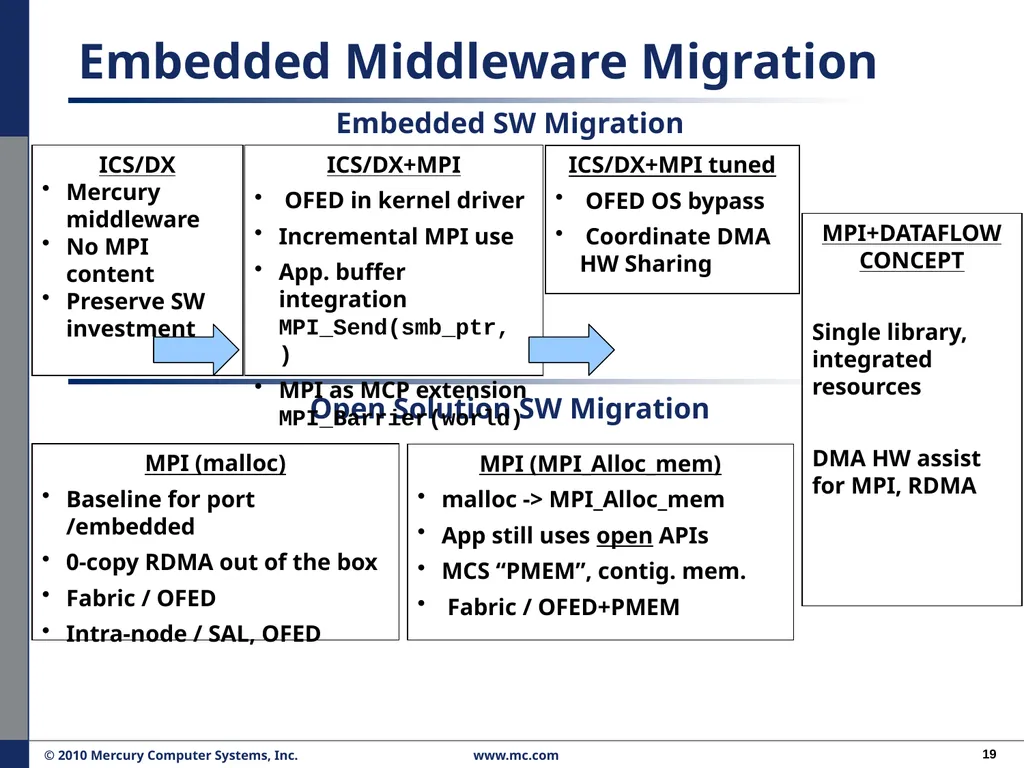
Embedded Middleware Migration Embedded SW Migration Open Solution SW Migration MPI+DATAFLOW CONCEPT
Single library, integrated resources
DMA HW assist for MPI, RDMA<br>
20
20 Motivating Example:�ICS/DX vs. MPI © 2010 Mercury Computer Systems, Inc. www.mc.com Data Rate Performance<br>
21
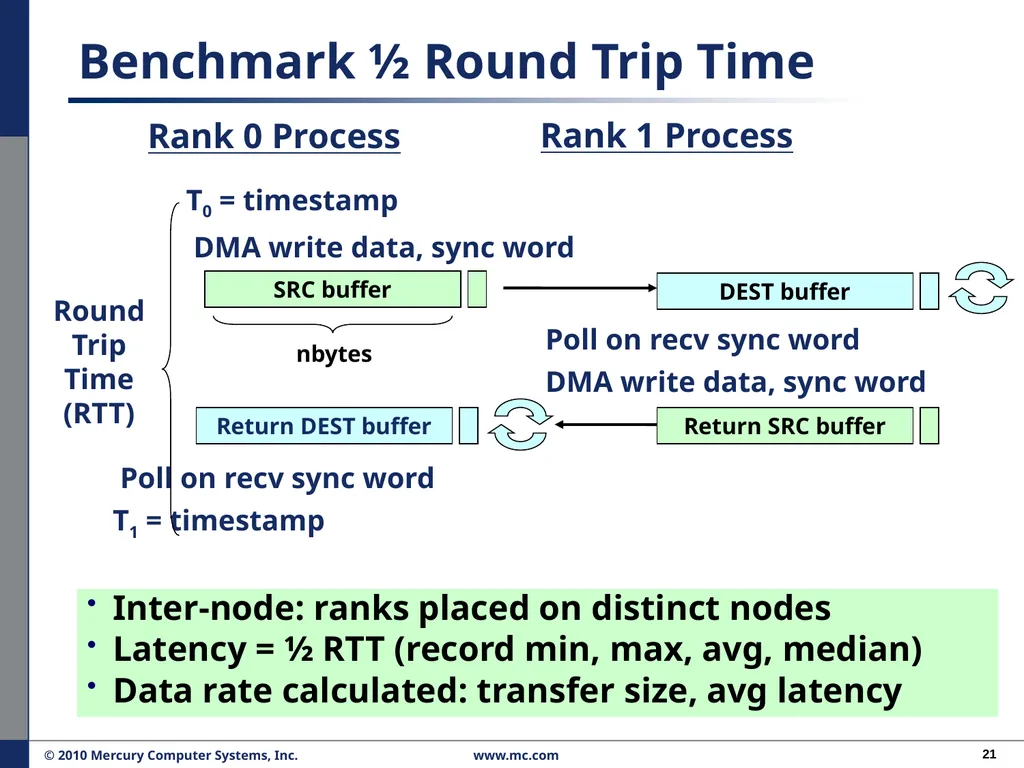
Benchmark ½ Round Trip Time Rank 0 Process Rank 1 Process Inter-node: ranks placed on distinct nodes
Latency = ½ RTT (record min, max, avg, median)
Data rate calculated: transfer size, avg latency T0 = timestamp
DMA write data, sync word Poll on recv sync word
T1 = timestamp Poll on recv sync word
DMA write data, sync word Round
Trip
Time
(RTT) nbytes<br>
22
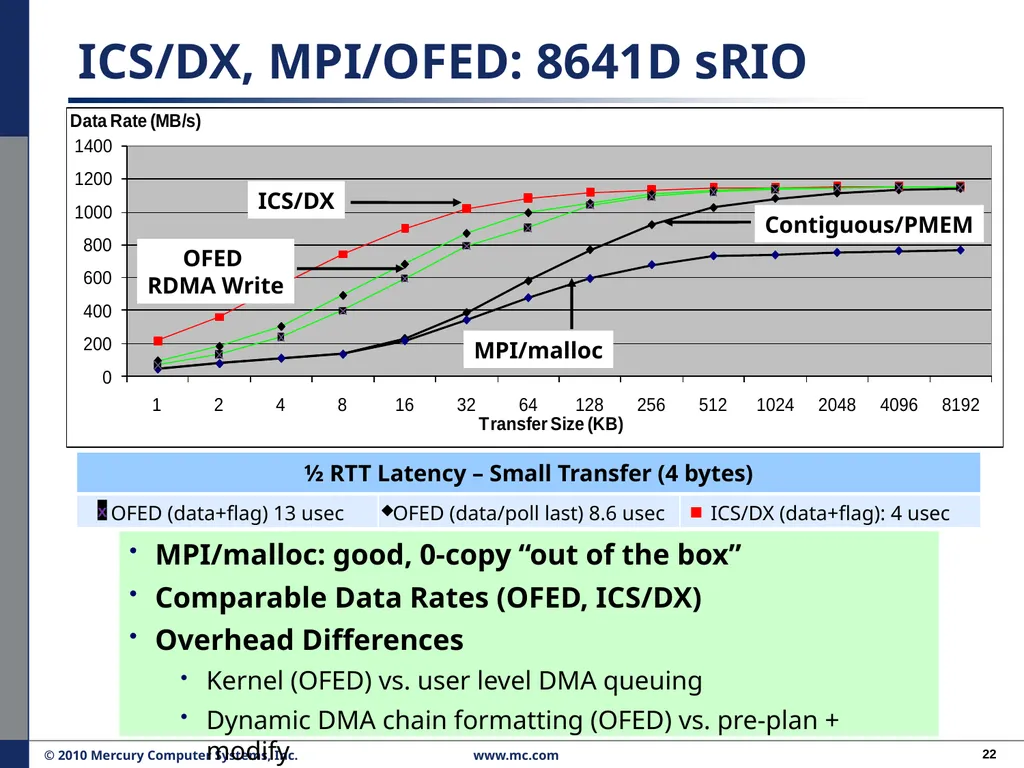
ICS/DX, MPI/OFED: 8641D sRIO MPI/malloc: good, 0-copy “out of the box”
Comparable Data Rates (OFED, ICS/DX)
Overhead Differences
Kernel (OFED) vs. user level DMA queuing
Dynamic DMA chain formatting (OFED) vs. pre-plan + modify x<br>
23
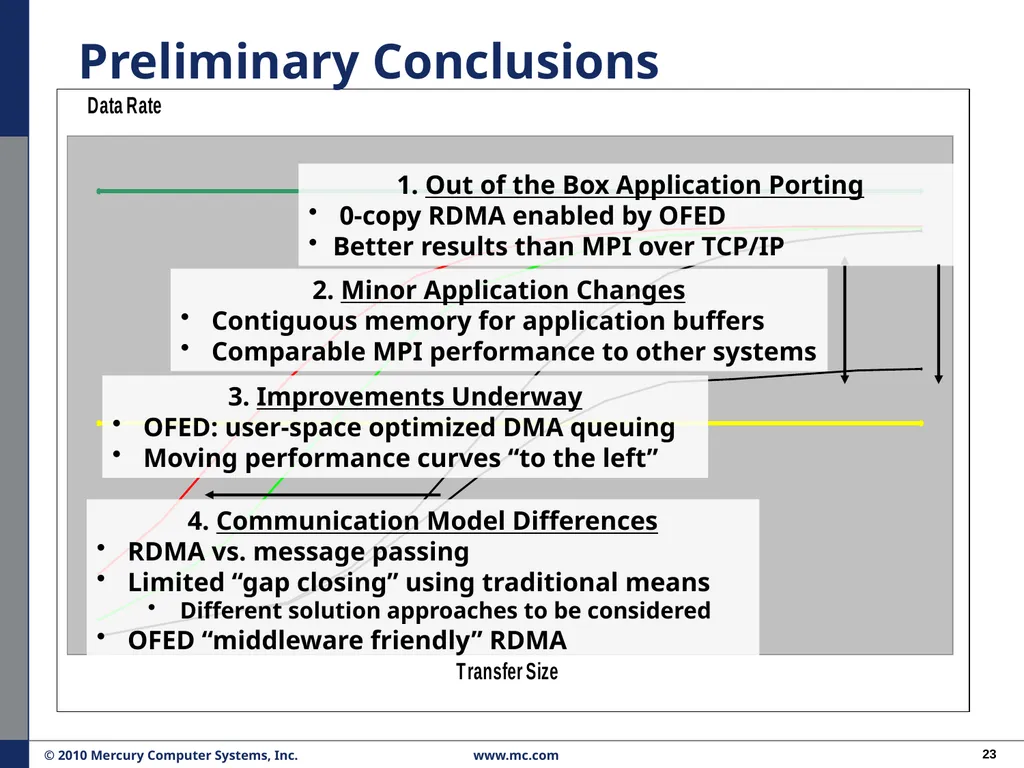
Preliminary Conclusions 3. Improvements Underway
OFED: user-space optimized DMA queuing
Moving performance curves “to the left”<br>
24
24 Communication Model Comparison © 2010 Mercury Computer Systems, Inc. www.mc.com Message Passing and RDMA<br>
25
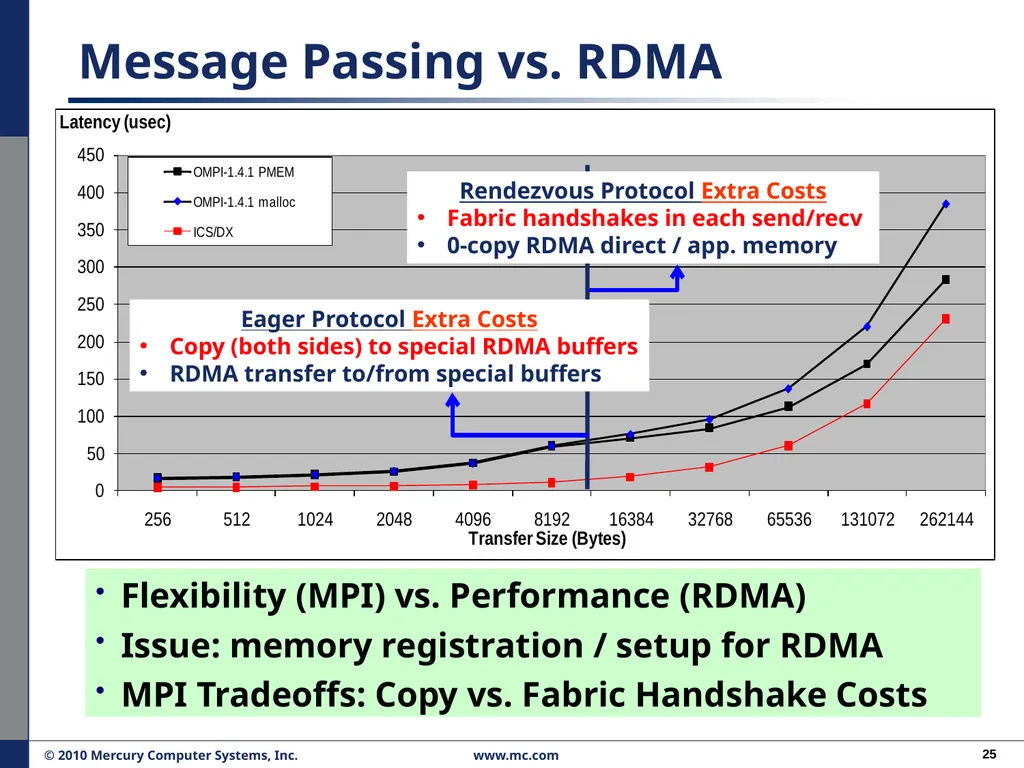
Message Passing vs. RDMA Rendezvous Protocol Extra Costs
Fabric handshakes in each send/recv
0-copy RDMA direct / app. memory Flexibility (MPI) vs. Performance (RDMA)
Issue: memory registration / setup for RDMA
MPI Tradeoffs: Copy vs. Fabric Handshake Costs Eager Protocol Extra Costs
Copy (both sides) to special RDMA buffers
RDMA transfer to/from special buffers<br>
26
26 MPI and RDMA Performance © 2010 Mercury Computer Systems, Inc. www.mc.com Server/HPC
Platform Comparisons<br>
27
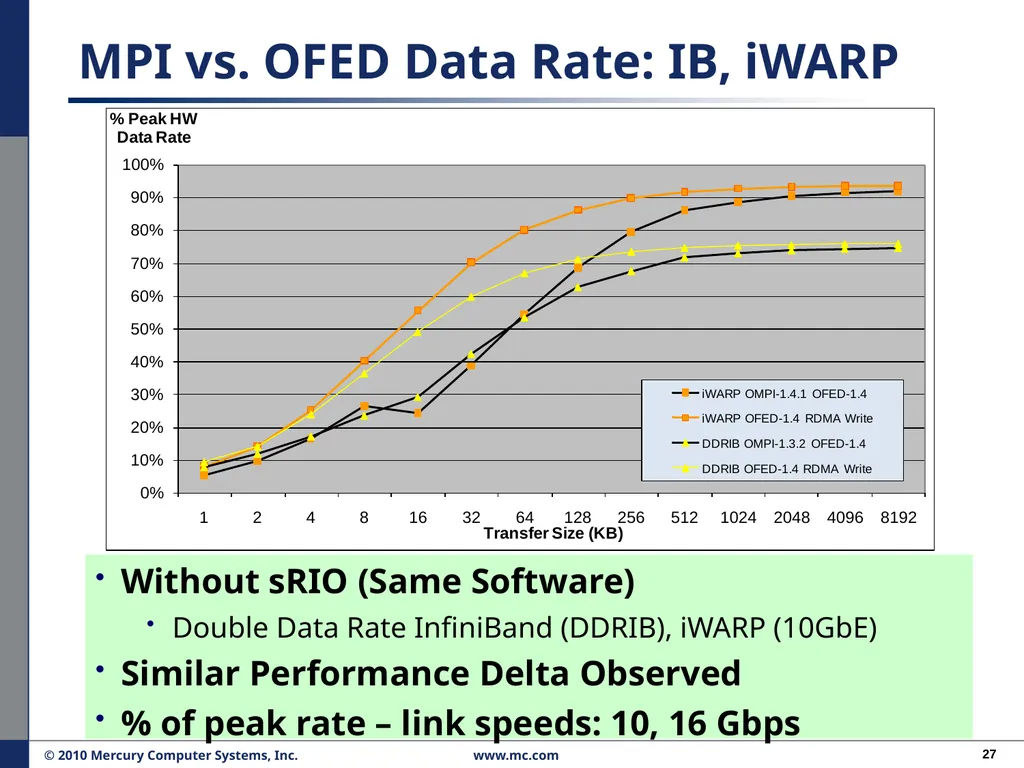
MPI vs. OFED Data Rate: IB, iWARP Without sRIO (Same Software)
Double Data Rate InfiniBand (DDRIB), iWARP (10GbE)
Similar Performance Delta Observed
% of peak rate – link speeds: 10, 16 Gbps<br>
28
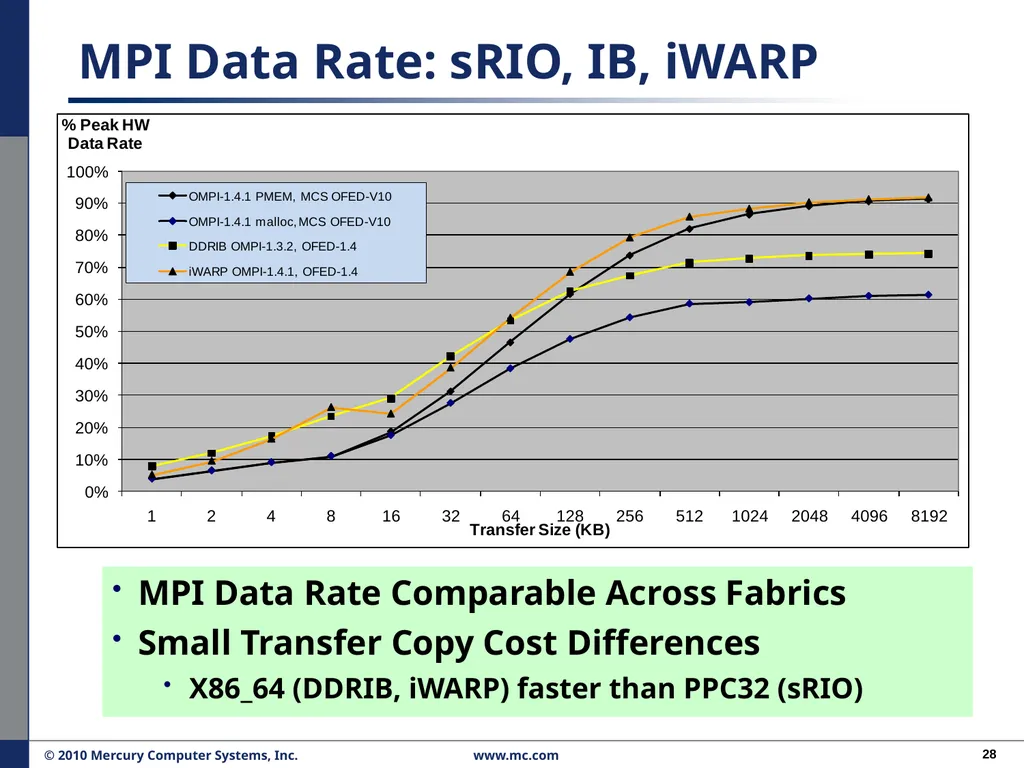
MPI Data Rate: sRIO, IB, iWARP MPI Data Rate Comparable Across Fabrics
Small Transfer Copy Cost Differences
X86_64 (DDRIB, iWARP) faster than PPC32 (sRIO)<br>
29
29 Mercury MPI/OFED Intra-Node Performance © 2010 Mercury Computer Systems, Inc. www.mc.com<br>
30
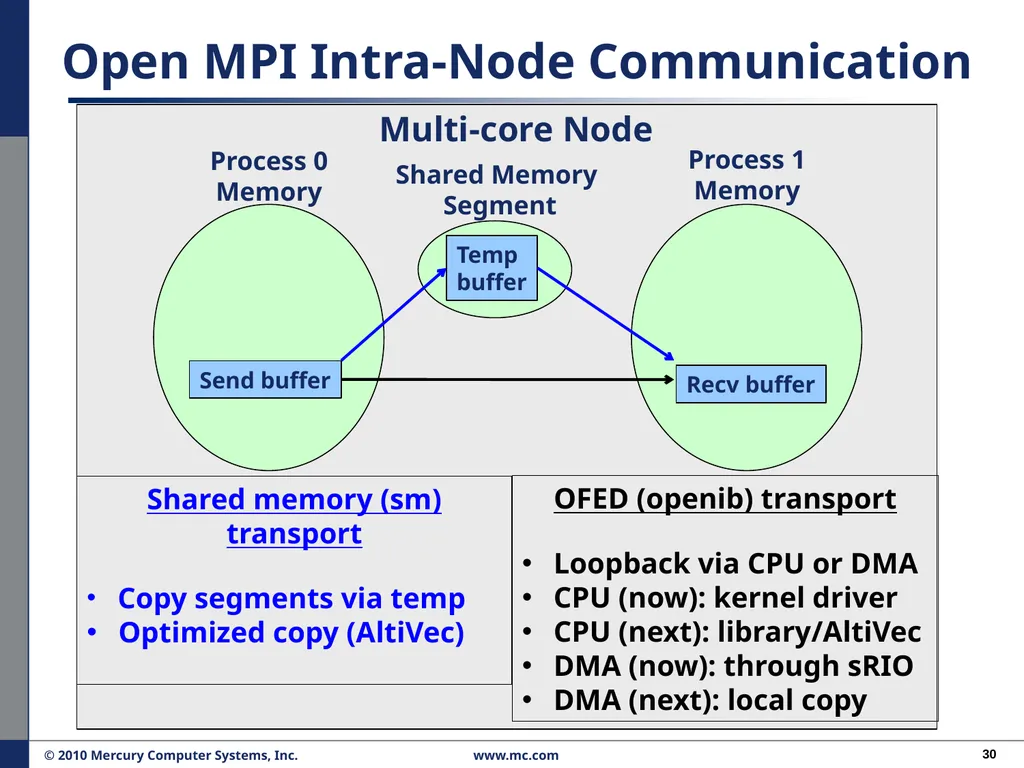
Open MPI Intra-Node Communication Multi-core Node Process 0
Memory Process 1
Memory Shared Memory
Segment Send buffer Recv buffer Shared memory (sm) transport�
Copy segments via temp
Optimized copy (AltiVec) OFED (openib) transport
Loopback via CPU or DMA
CPU (now): kernel driver
CPU (next): library/AltiVec
DMA (now): through sRIO
DMA (next): local copy<br>
31
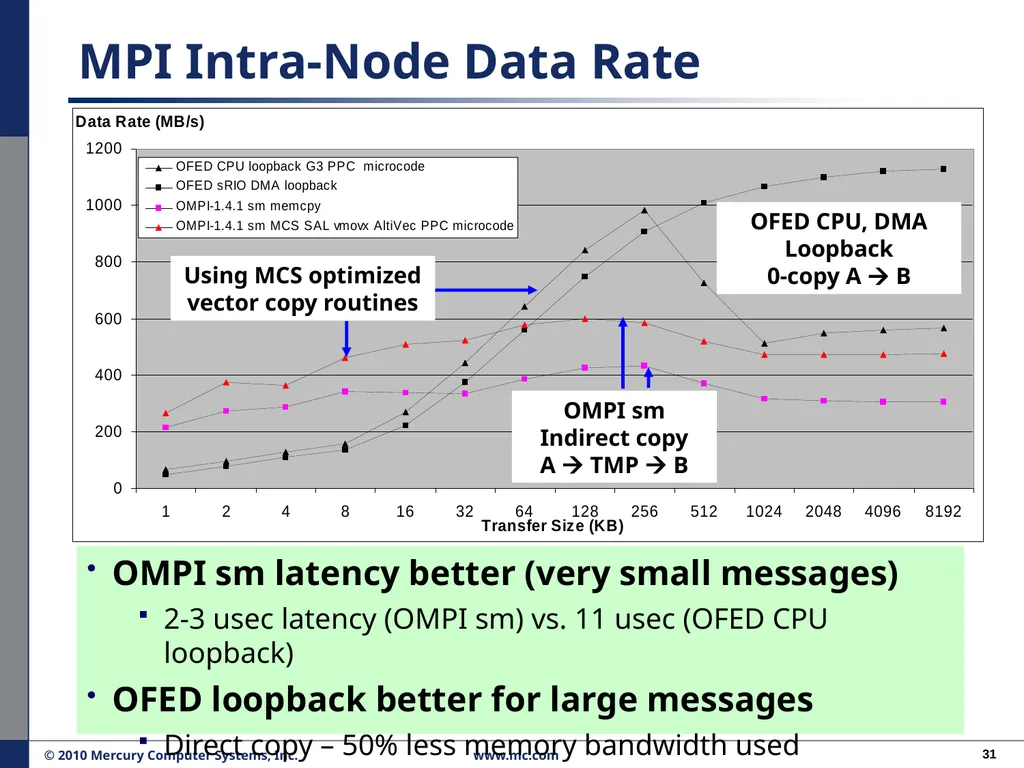
MPI Intra-Node Data Rate OMPI sm latency better (very small messages)
2-3 usec latency (OMPI sm) vs. 11 usec (OFED CPU loopback)
OFED loopback better for large messages
Direct copy – 50% less memory bandwidth used OFED CPU, DMA Loopback
0-copy A B OMPI sm
Indirect copy
A TMP B Using MCS optimized vector copy routines<br>
32
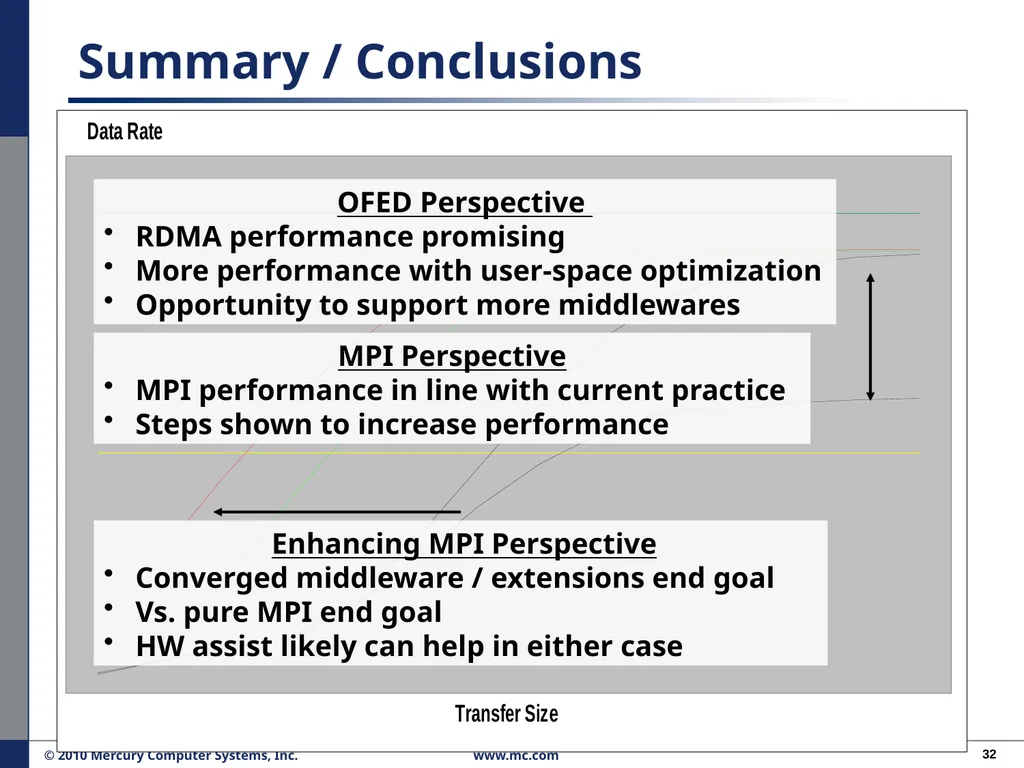
Summary / Conclusions OFED Perspective
RDMA performance promising
More performance with user-space optimization
Opportunity to support more middlewares MPI Perspective
MPI performance in line with current practice
Steps shown to increase performance Enhancing MPI Perspective
Converged middleware / extensions end goal
Vs. pure MPI end goal
HW assist likely can help in either case<br>
33
33 Thank You��Questions? © 2010 Mercury Computer Systems, Inc. www.mc.com Kenneth Cain
kcain@mc.com<br>